One entry point to every AI model: keys, limits, spending and logs in one place — while your programs keep working exactly as before
All your programs talk not to a dozen model vendors one by one, but to a single address on your server. Vendor keys live in one place instead of spreading across employee computers; every person or contractor gets their own access key with its own spending limits and allowed models; and spending shows in money, not in tokens. On top of that, the product converts request formats (a program written for one vendor works with another vendor’s model), strips secrets out of requests before they reach the model, and routes ordinary traffic over HTTP and SOCKS5 through your own channels — your own proxy, SOCKS5, VPN and Happ subscriptions — and gives a chat with the AI agent right in the interface. It is a standalone application on your server: it serves all your programs at once, not only Agent — do not confuse it with the agent’s built-in proxy server, which runs inside a single product.
One address instead of ten: programs talk to the proxy, not to every vendor directly
Vendor keys live on your server and never spread across employee computers
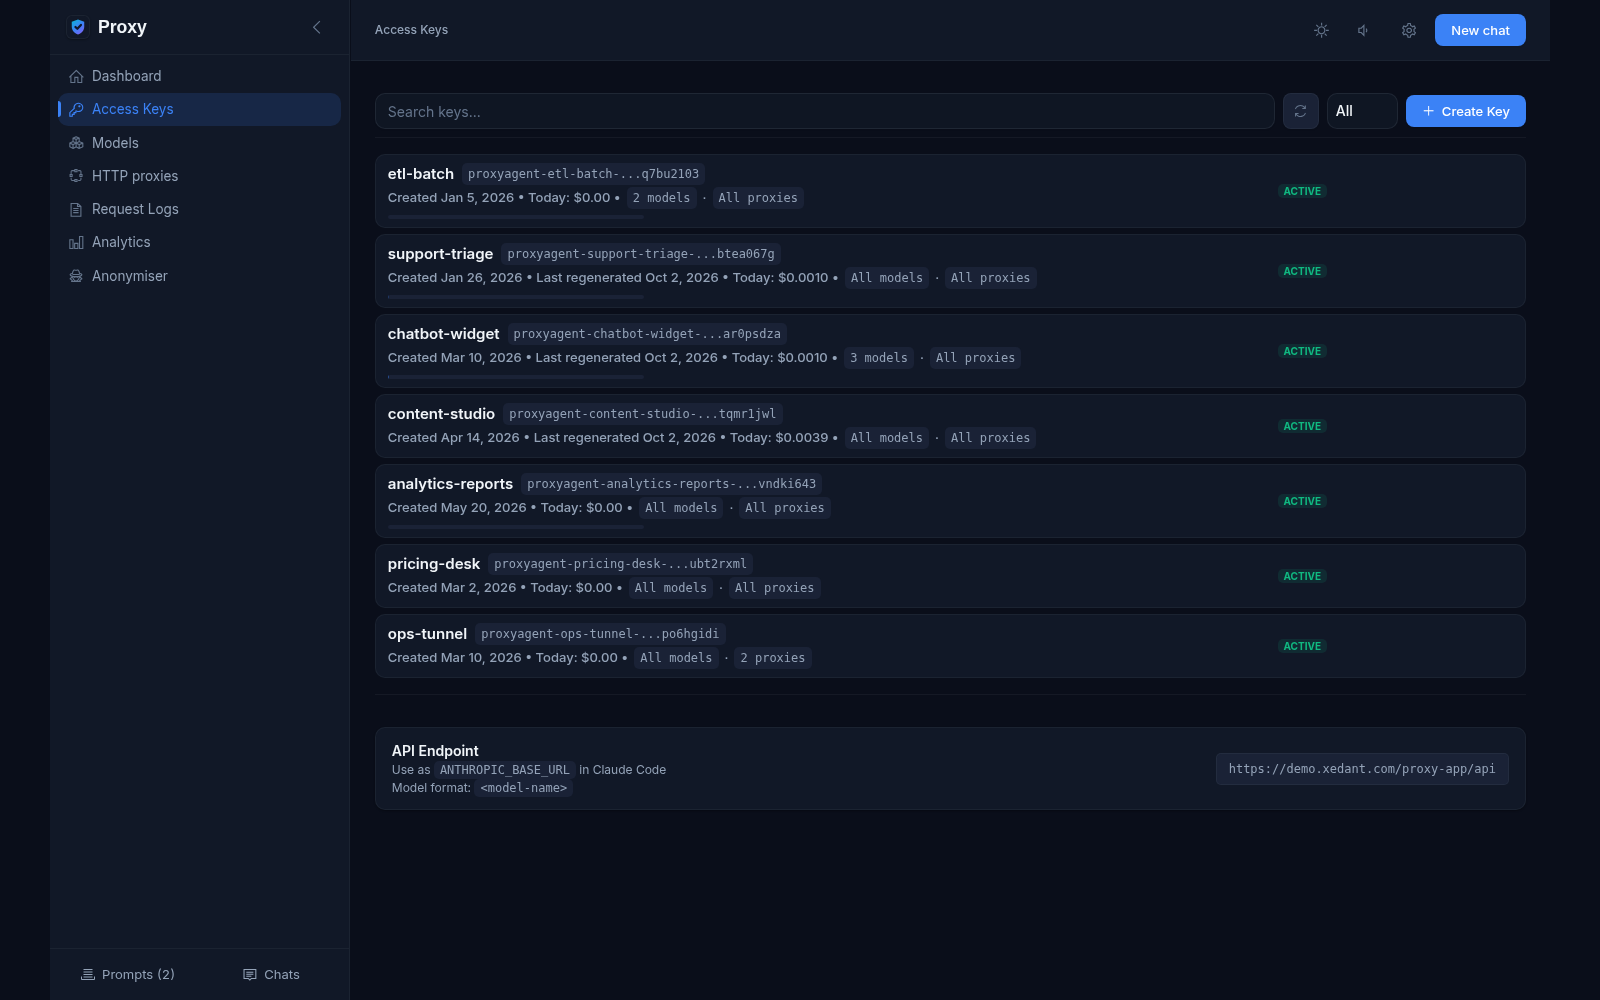
Your own access keys for teams and contractors: a name, the right to revoke, regeneration in one click
OpenAI, Anthropic and DeepSeek behind one address, whichever program you use
Format conversion: a program written for one vendor works with another vendor’s model
The list of available models at a standard address, so a program shows them in its own list
Change a model or a vendor for all programs at once, without reconfiguring each one
Your configuration travels with the project: models, channels and access keys live in plain files
Every model has its own price per million portions of text (tokens), so you see costs in money, not in tokens
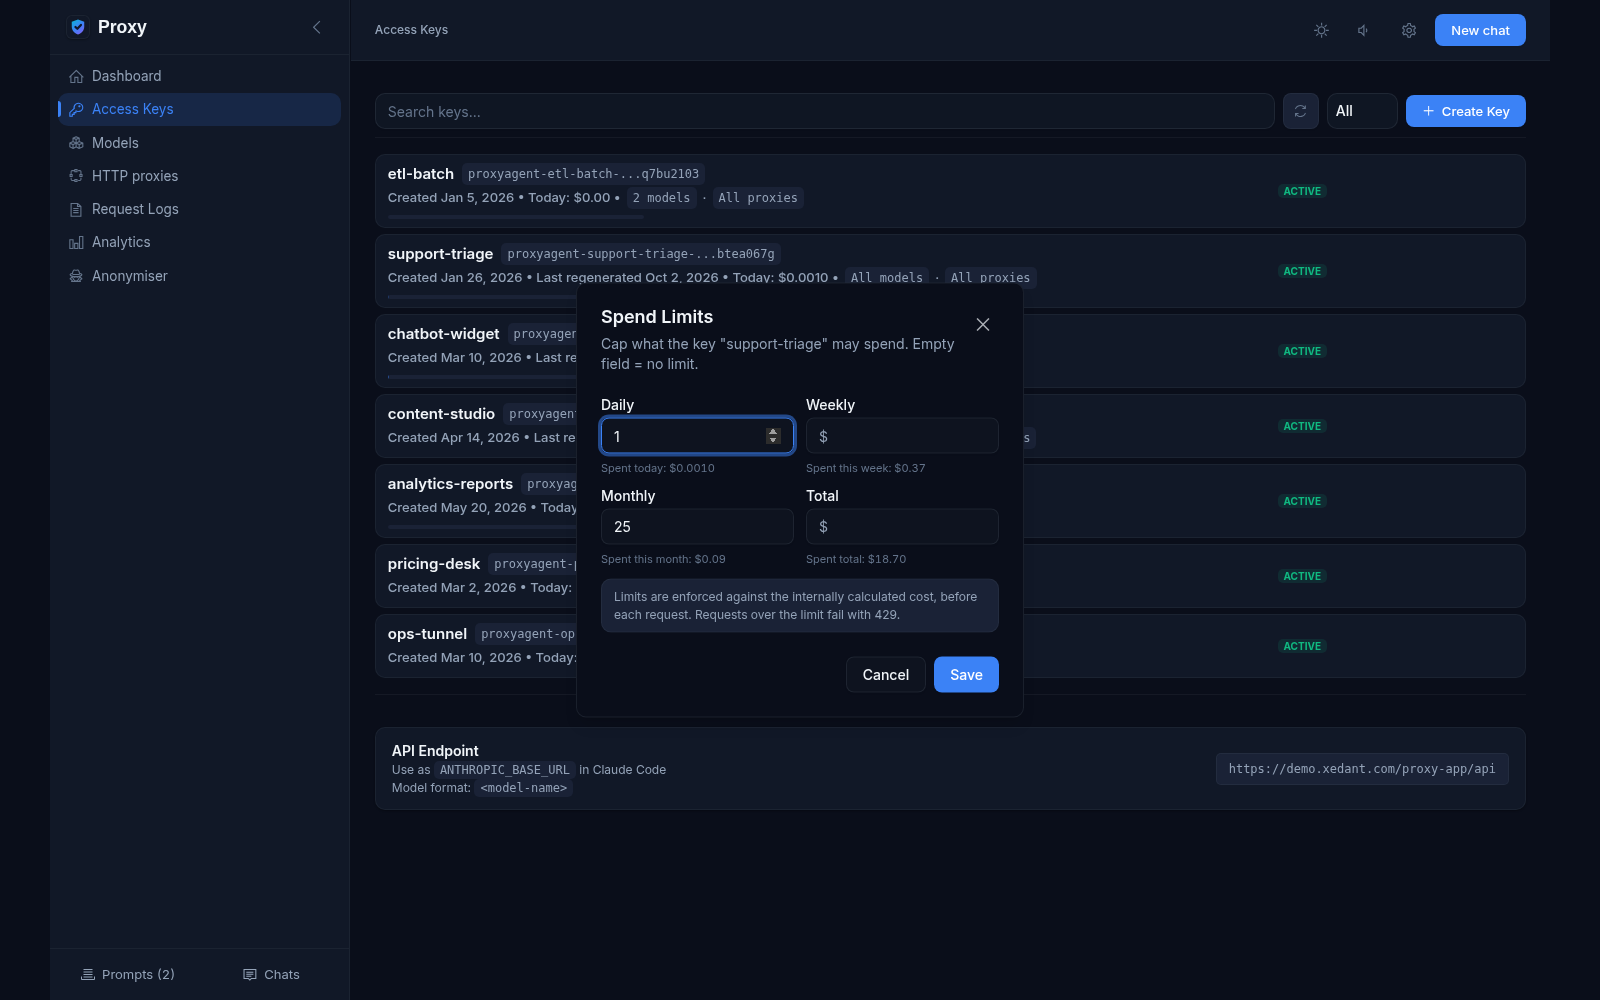
Daily, weekly, monthly and total limits: a contractor or a runaway script will not empty the budget
Model restrictions: a key can be allowed only the models it is supposed to use
Reused input is counted at its own price, so the bill matches the real spend
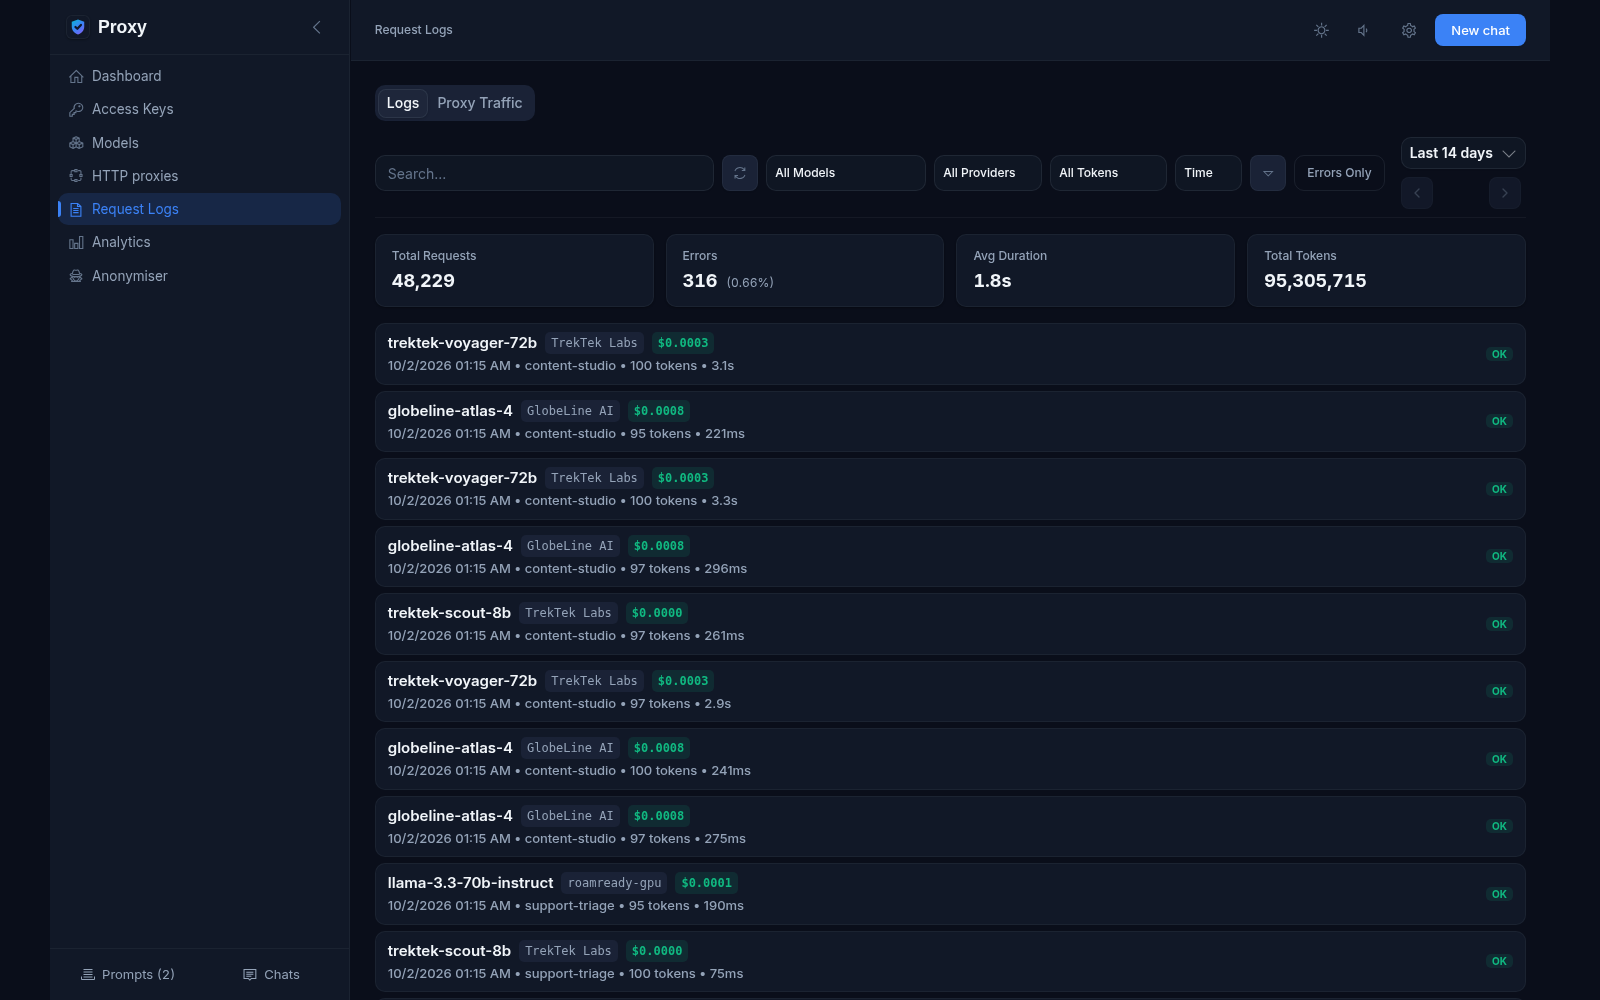
A request log: who, when, which model, how many tokens and how much money
Request and response texts are never stored: the conversation with AI does not pile up in the database
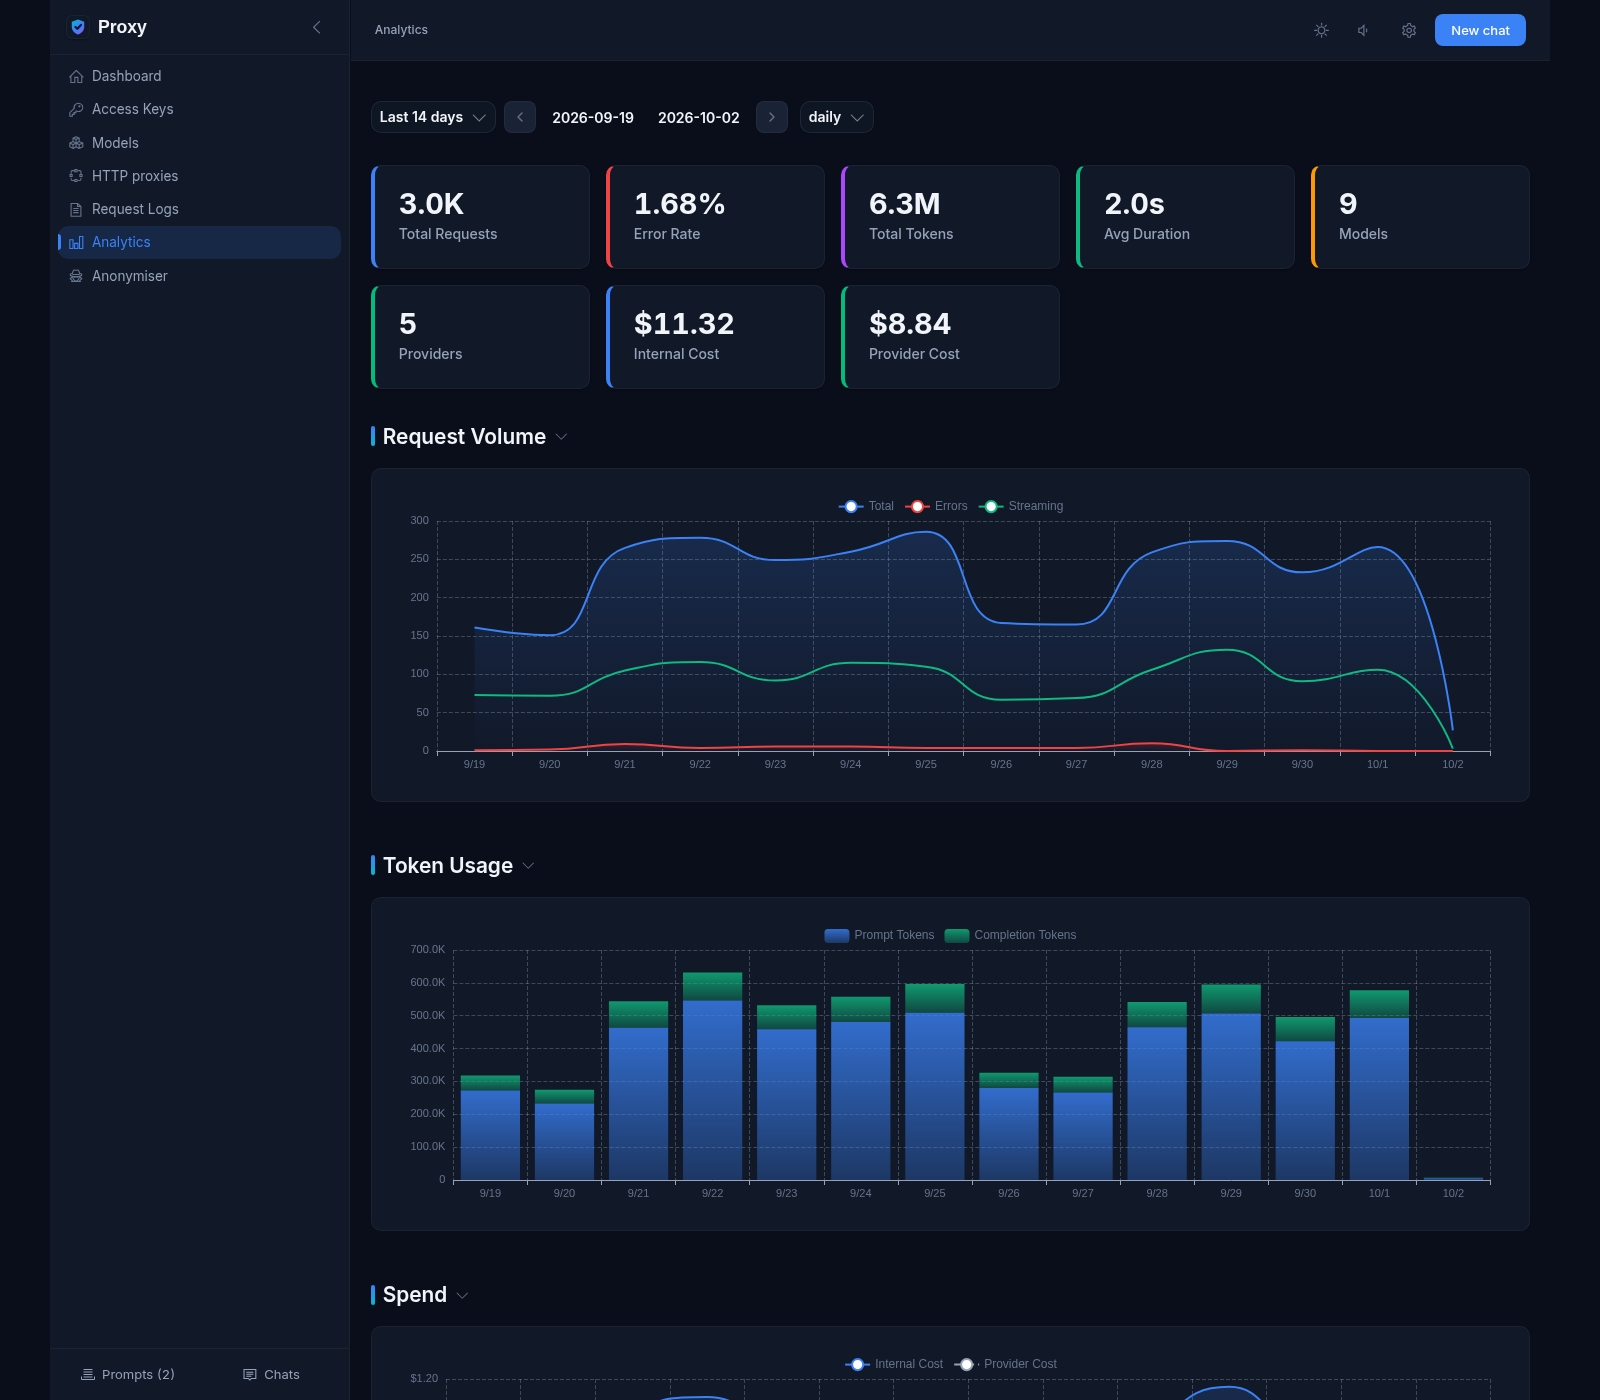
Analytics: request volume, latency, breakdown by models and keys, peak hours, errors
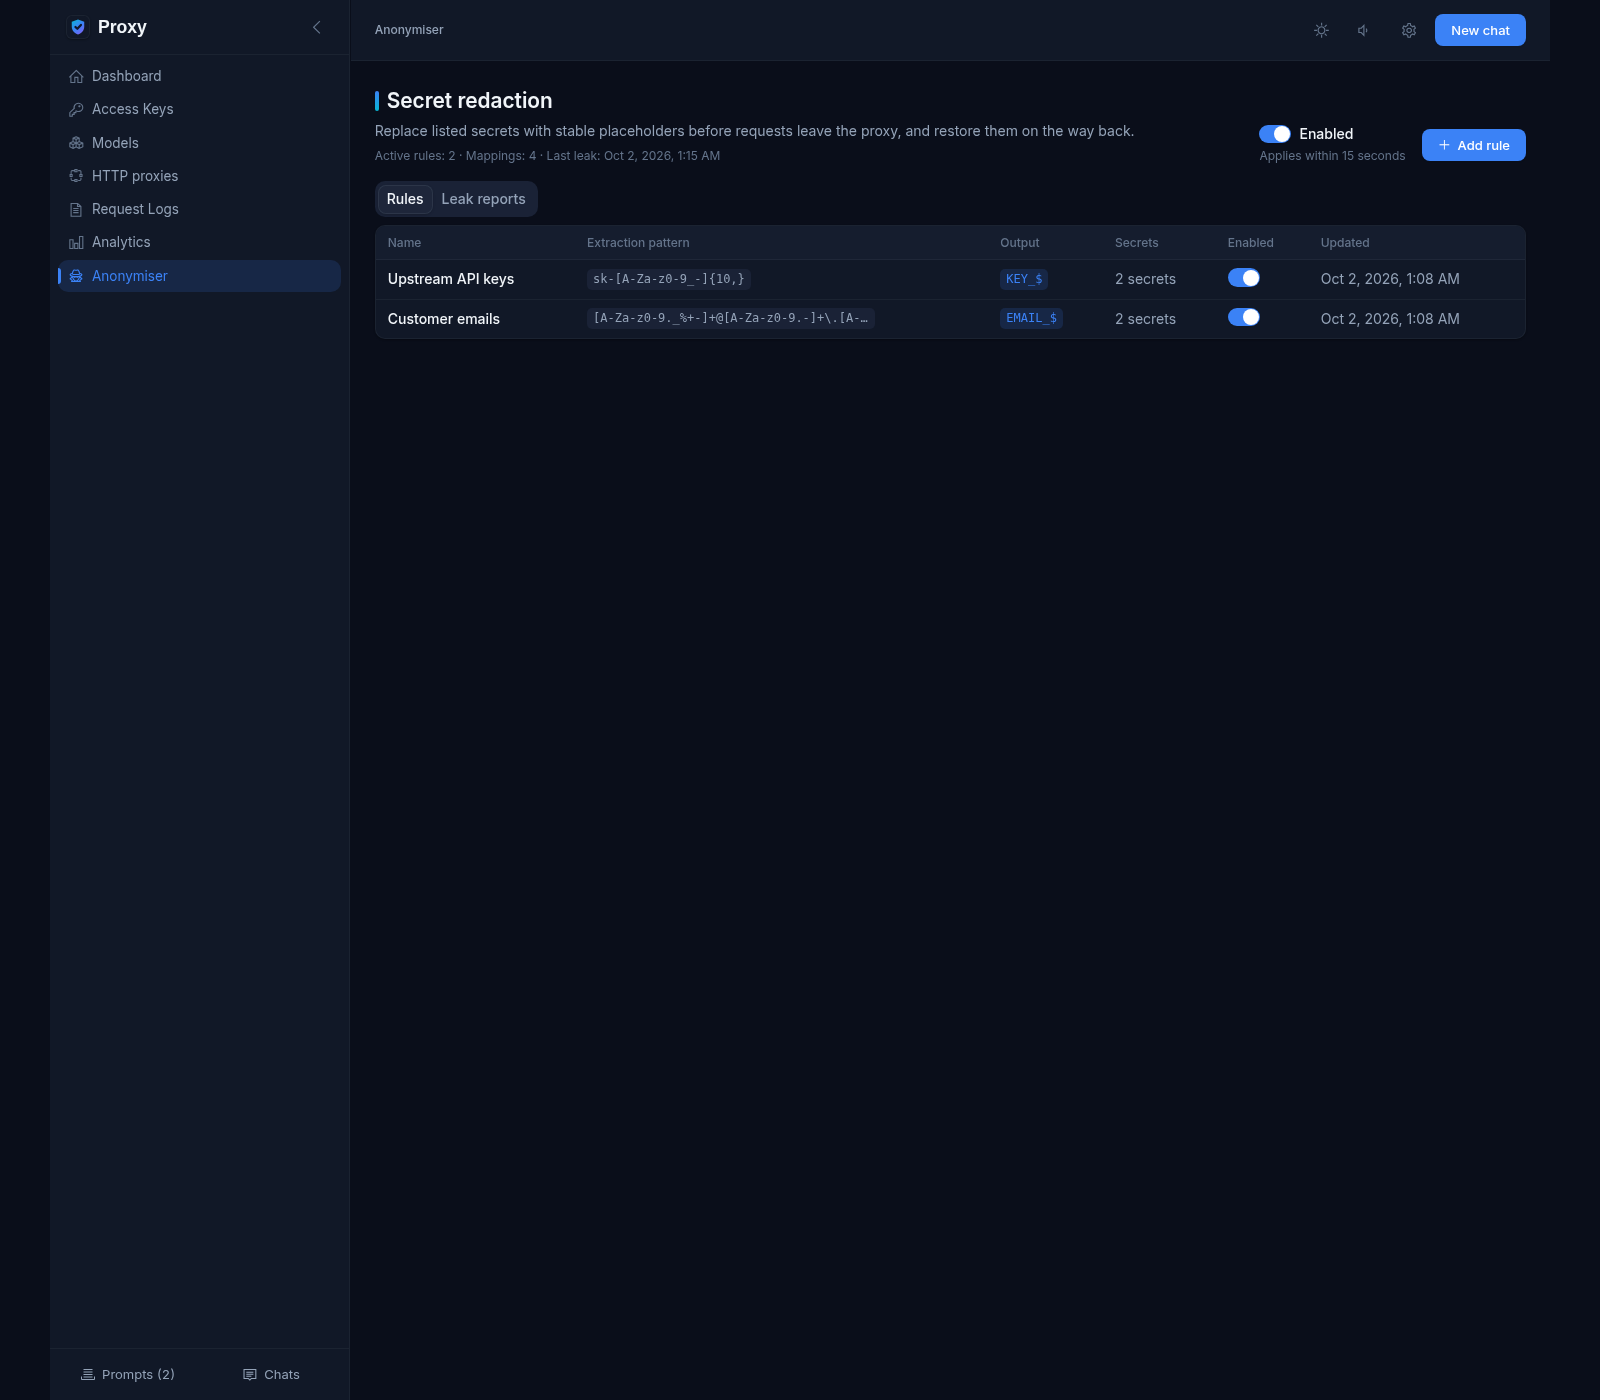
Secret hiding: passwords and keys in requests are replaced with conventional marks and put back
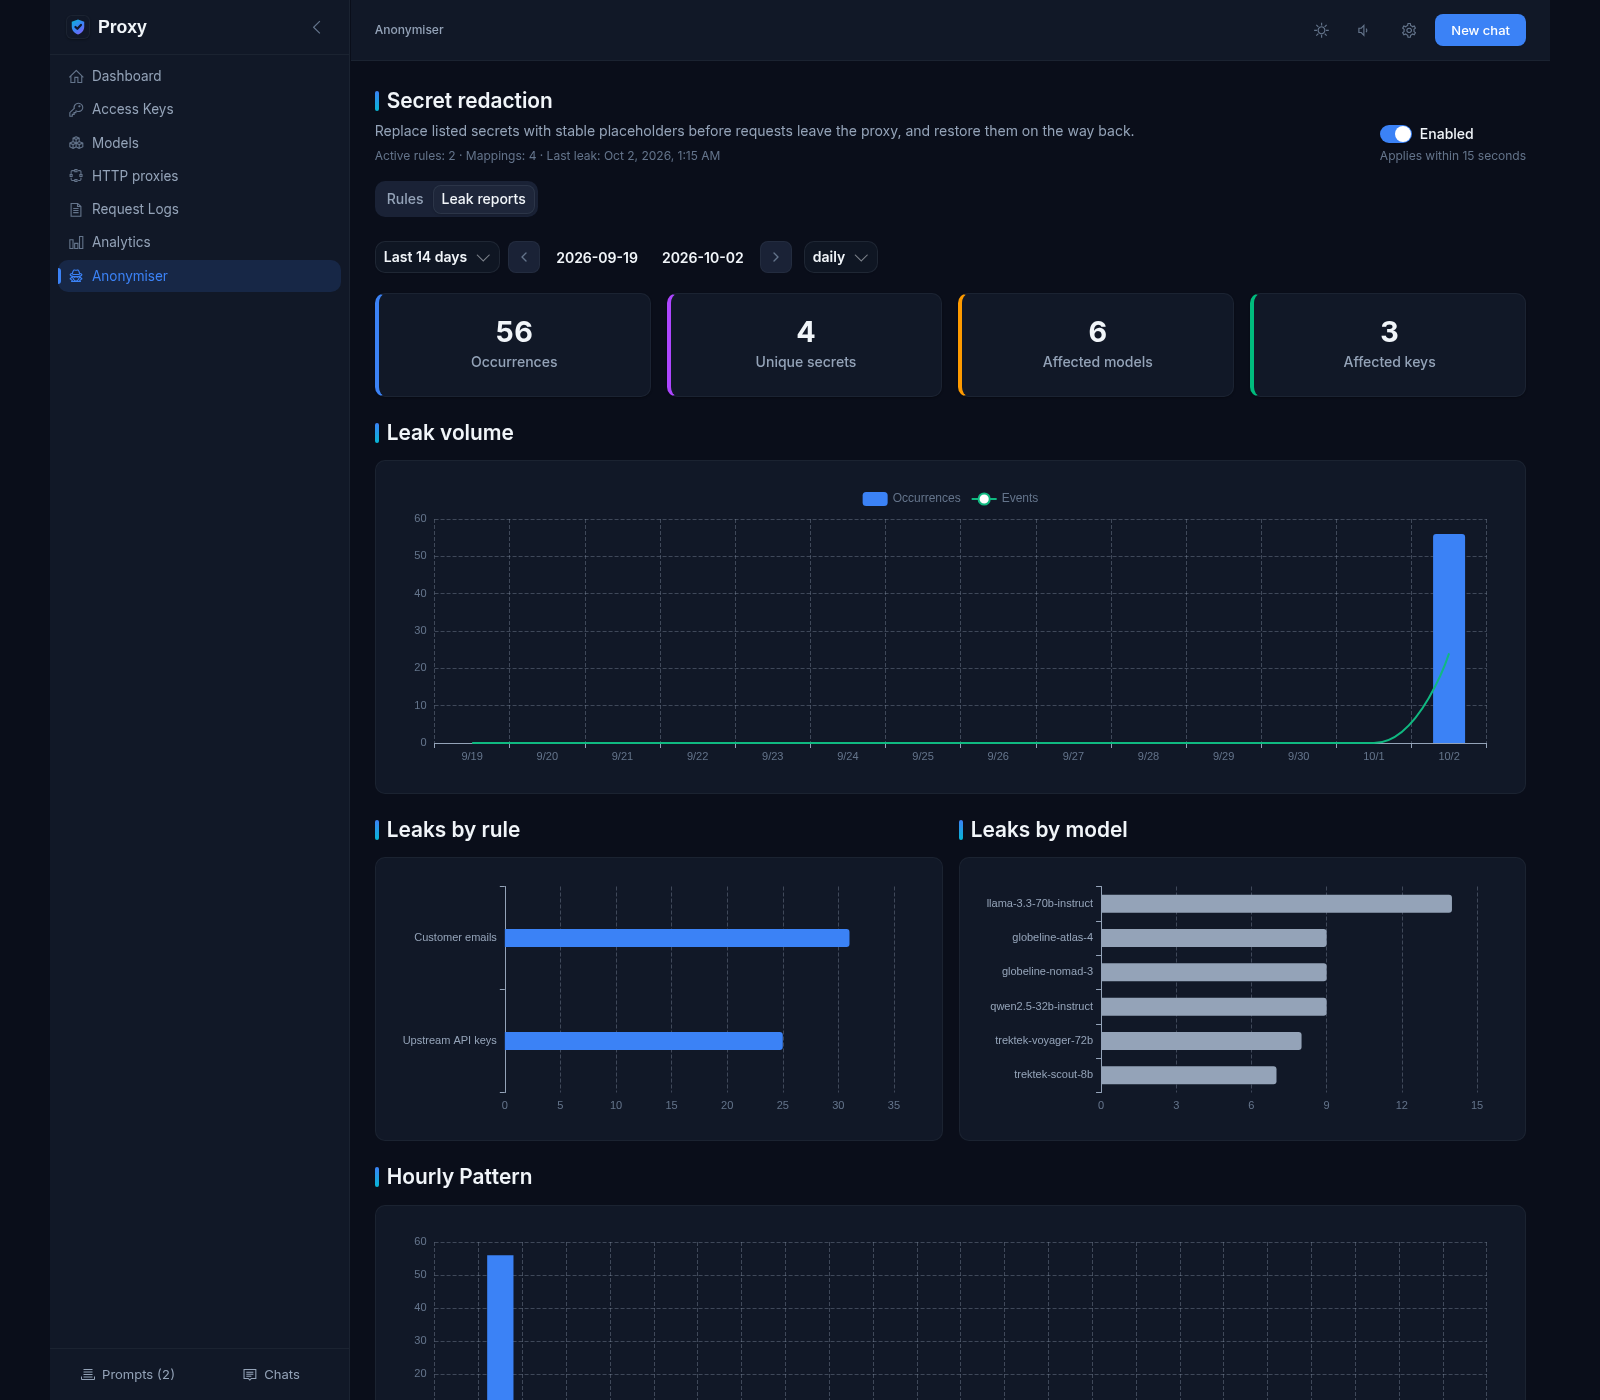
Leak reports: see which rules and models most often touch secrets
A proxy for ordinary traffic: HTTP and SOCKS5 on one listener, with its own port and its own login requirement on every channel
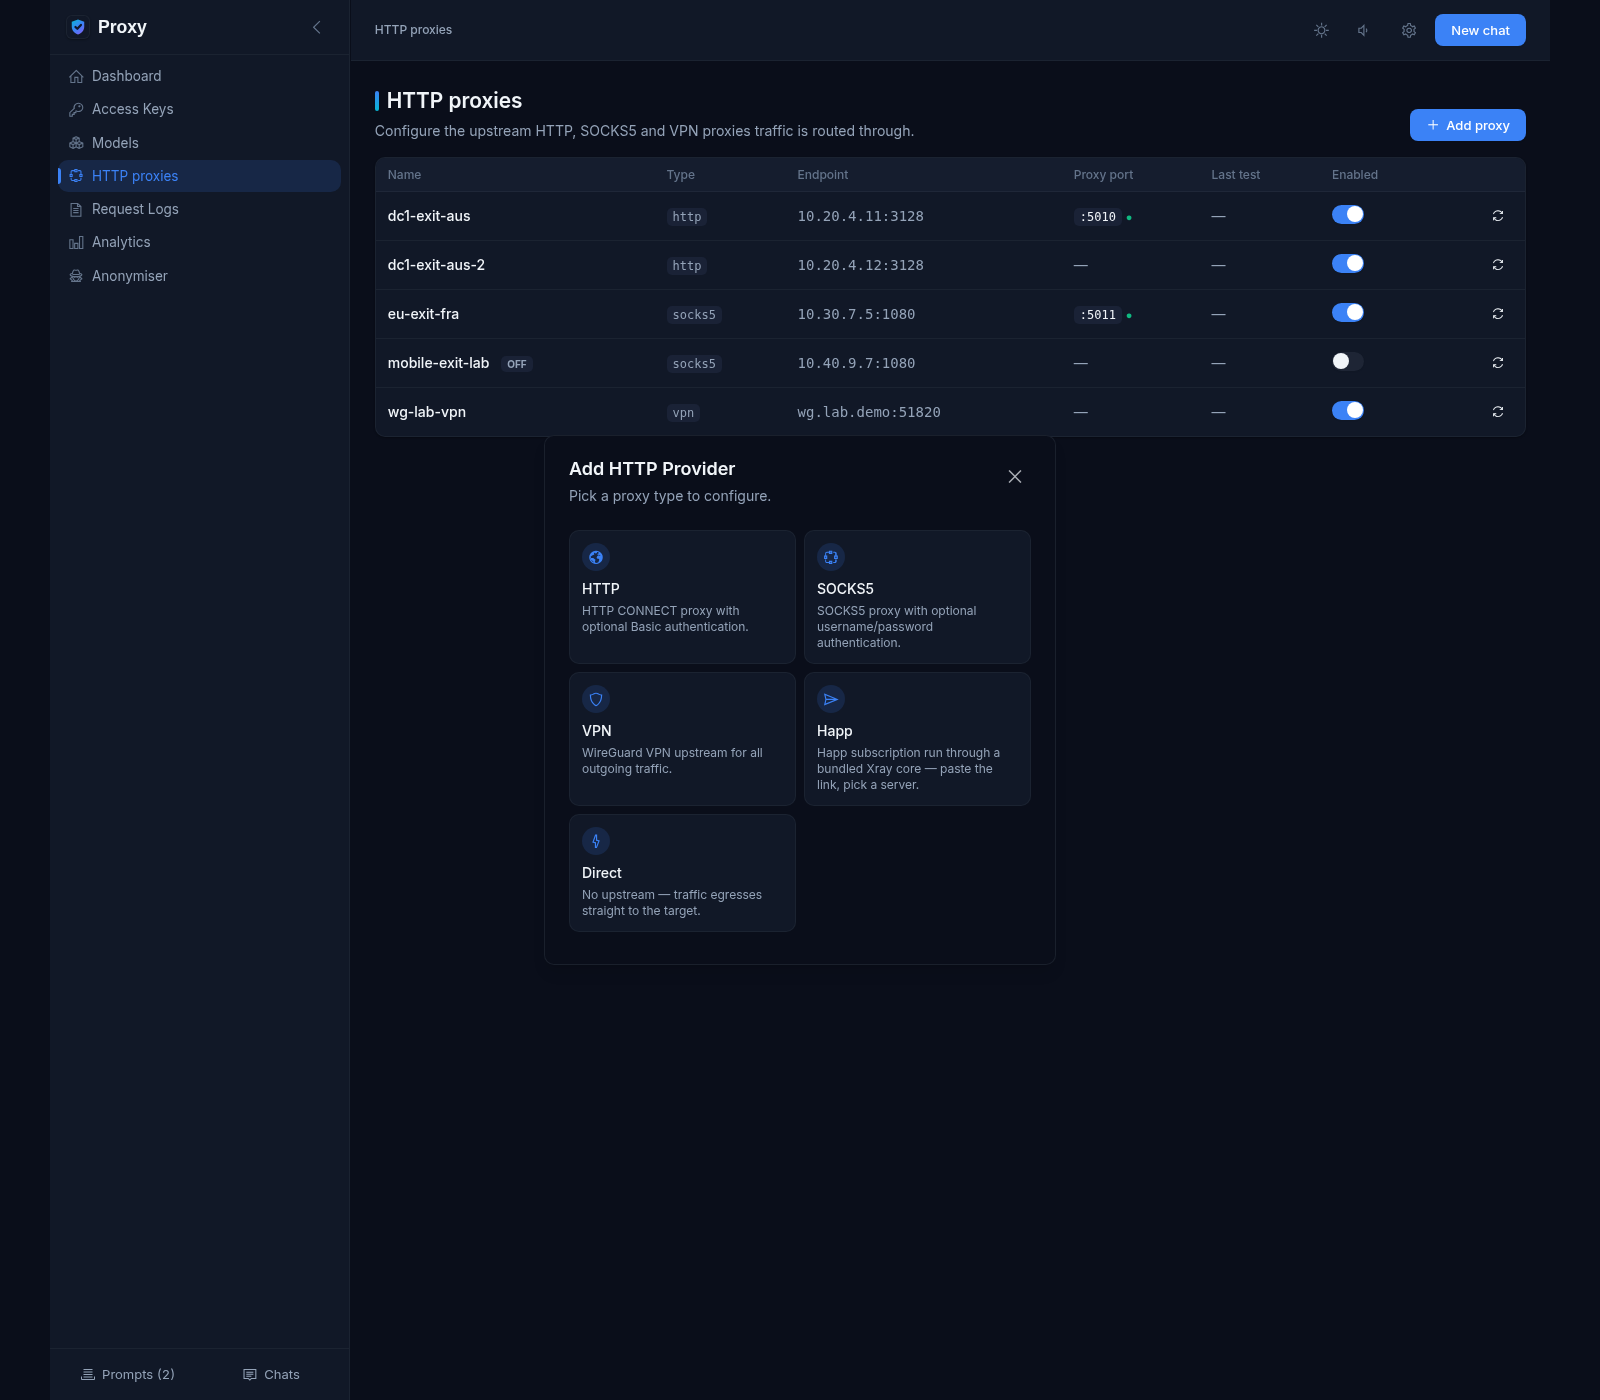
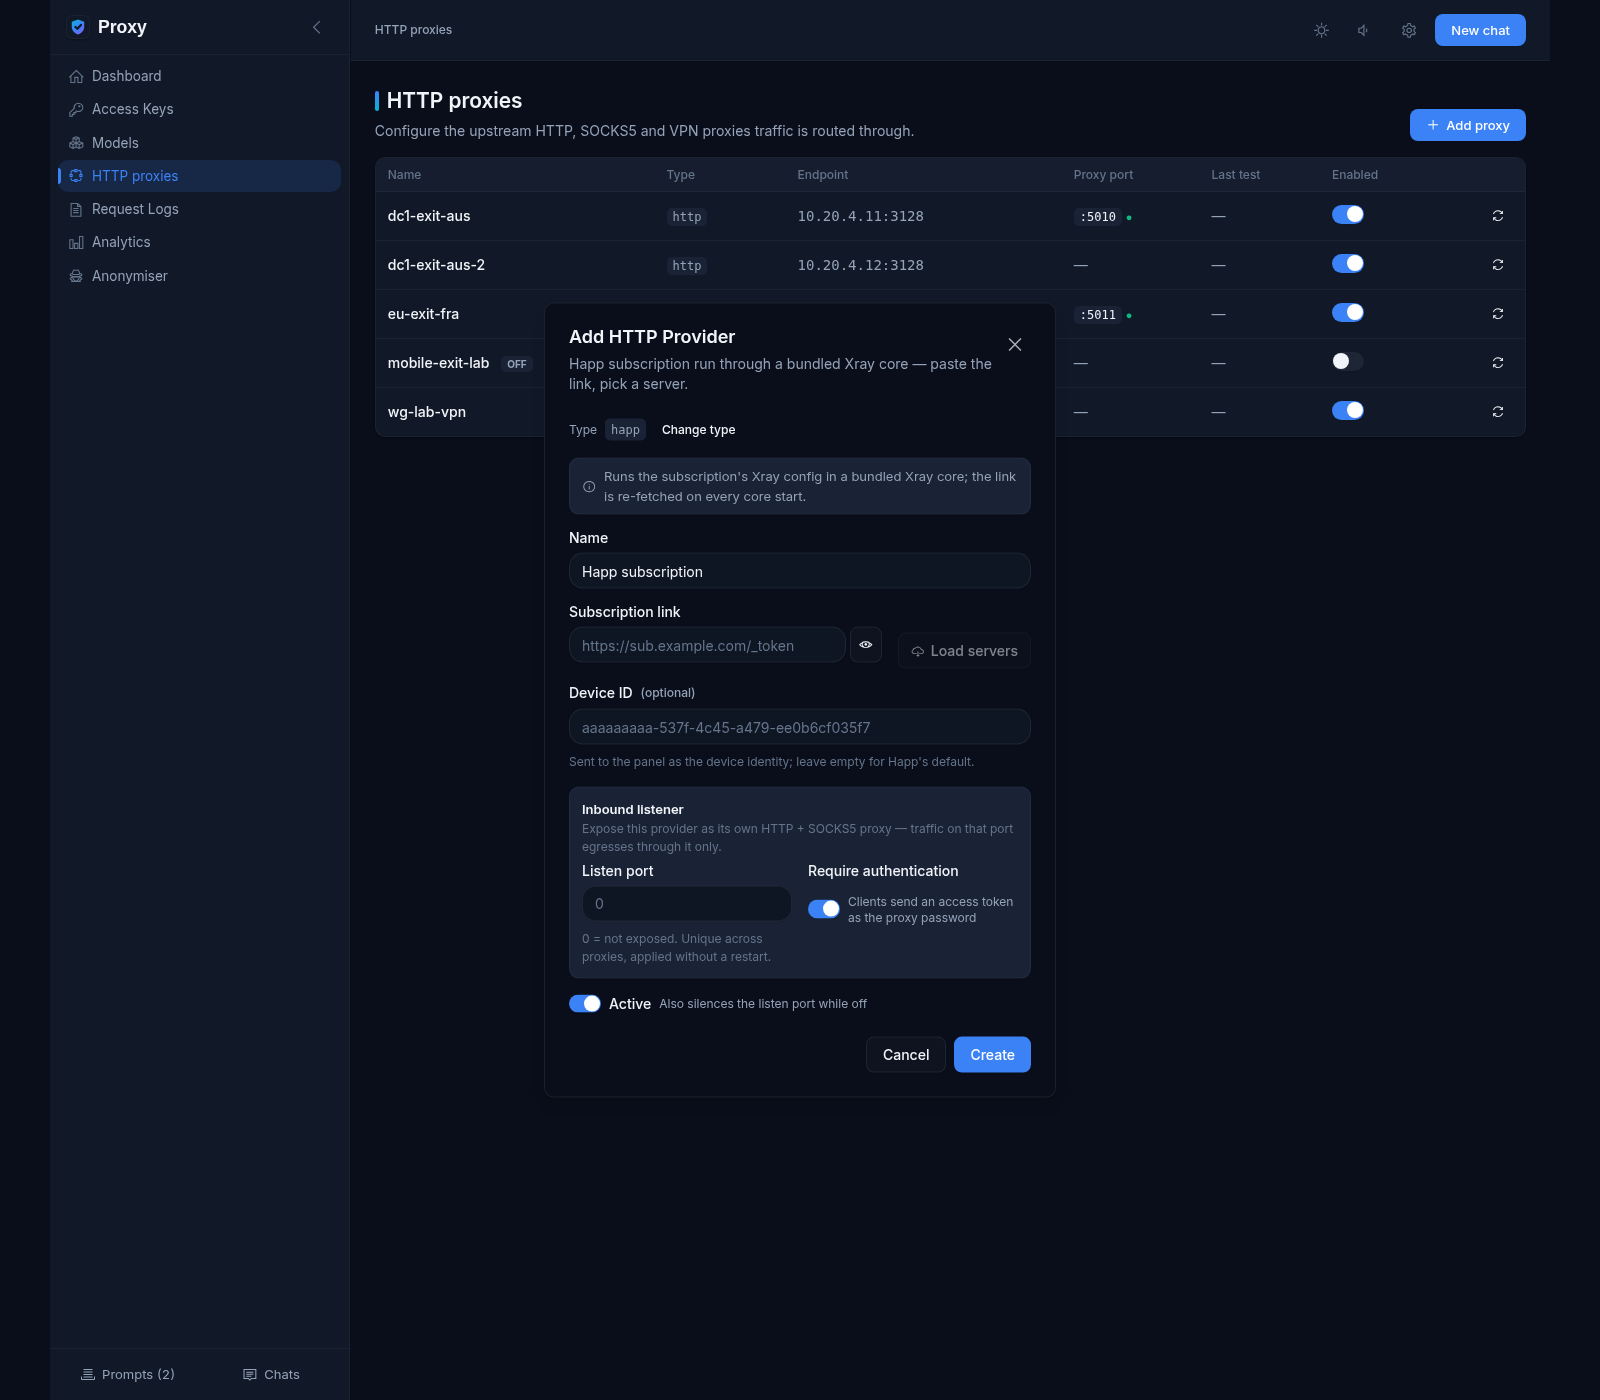
Happ subscriptions as a channel: paste the subscription link, pick a server from the list — a bundled Xray core does the rest
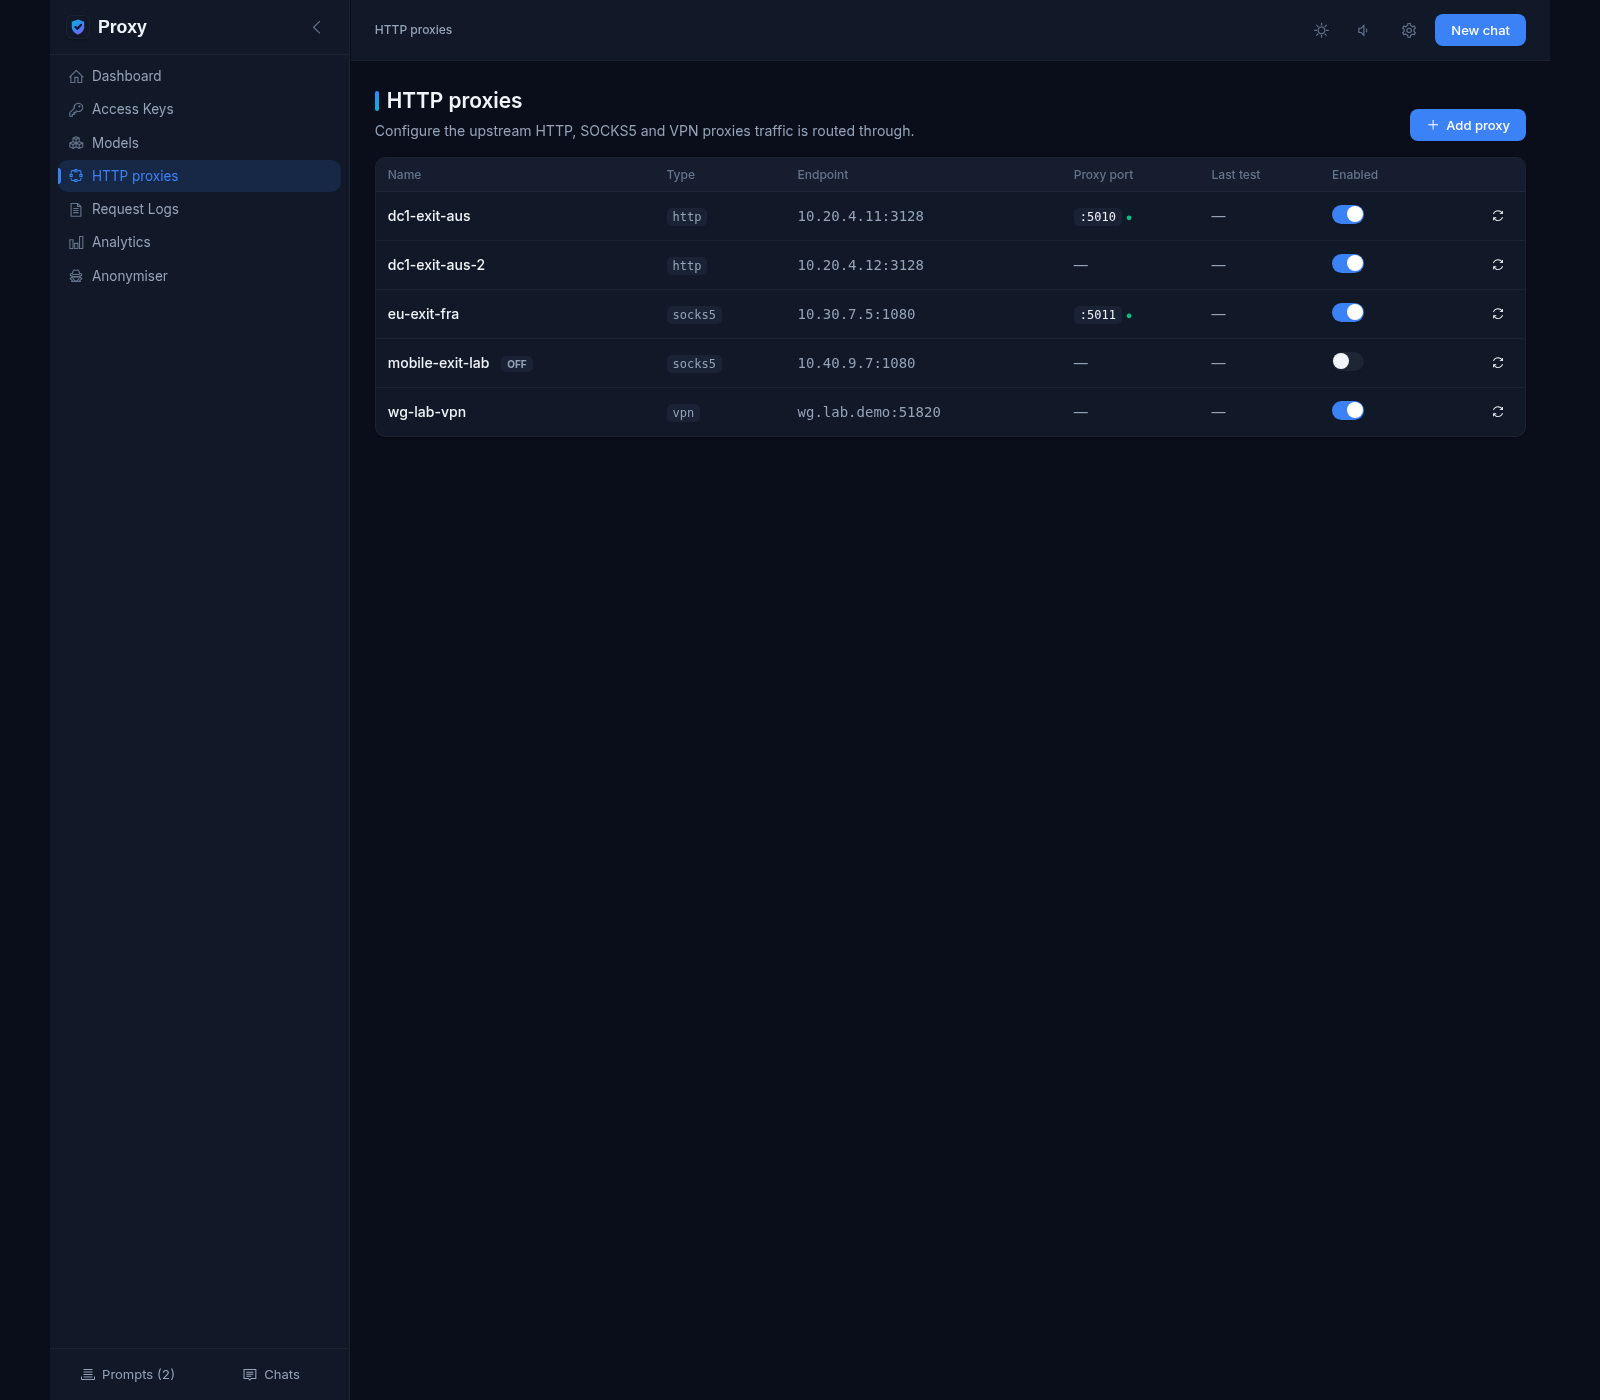
Your own HTTP proxies, SOCKS5 and VPN as channels, with a connectivity check and their own port for contractors
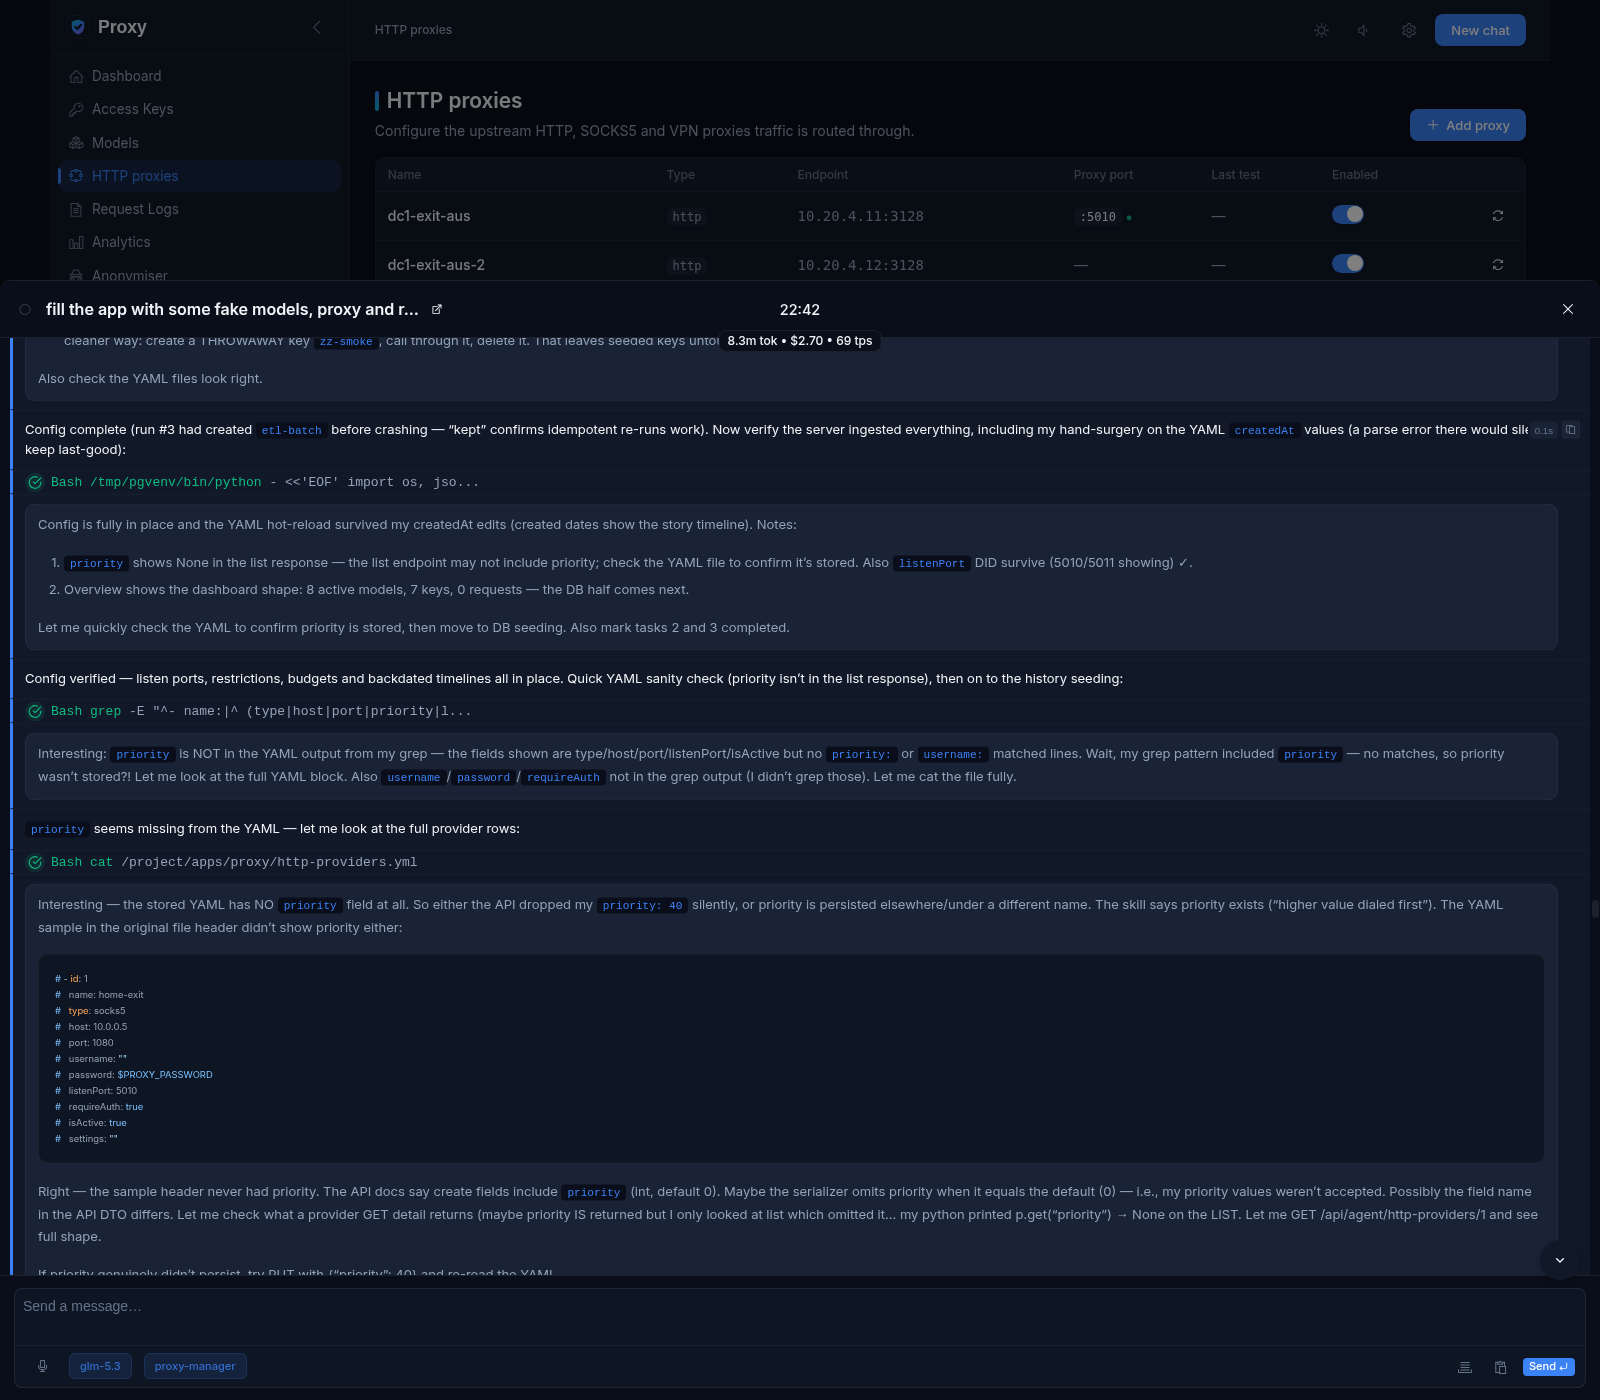
A chat with the AI agent inside the product: connect Agent and ask about the interface in the chat
Everything on your own server: the application, the configuration files and the logs stay with you
The license gates traffic, not the interface: without a key requests are refused, but everything stays configurable
Idle economy: while no traffic flows the app does not load the CPU, and memory is released after 15 minutes without work
One address instead of ten vendors
Programs talk not to each vendor separately but to one address of your server — you configure each program once
Three familiar addresses: /api/chat/completions (OpenAI format), /api/v1/messages (Anthropic format) and /api/models with the list of models
Enter with an access key: Authorization: Bearer or x-api-key — so both OpenAI programs and Anthropic programs fit
Even a key refusal arrives in the familiar OpenAI format, so the program shows a clear error instead of an unknown response
Access keys: who is allowed what
The access key is your own key for entering the proxy: it is not tied to vendor keys and is issued to each person or program separately
The key looks like proxyagent-name-24 characters; the database keeps only a SHA-256 fingerprint and the last 8 characters, and the key itself is shown once
Regeneration instantly revokes the previous key: if a key leaks, the old copy stops working at once
A key can be deactivated, cloned and checked, and its settings open in the Keys section
Models and prices per million tokens
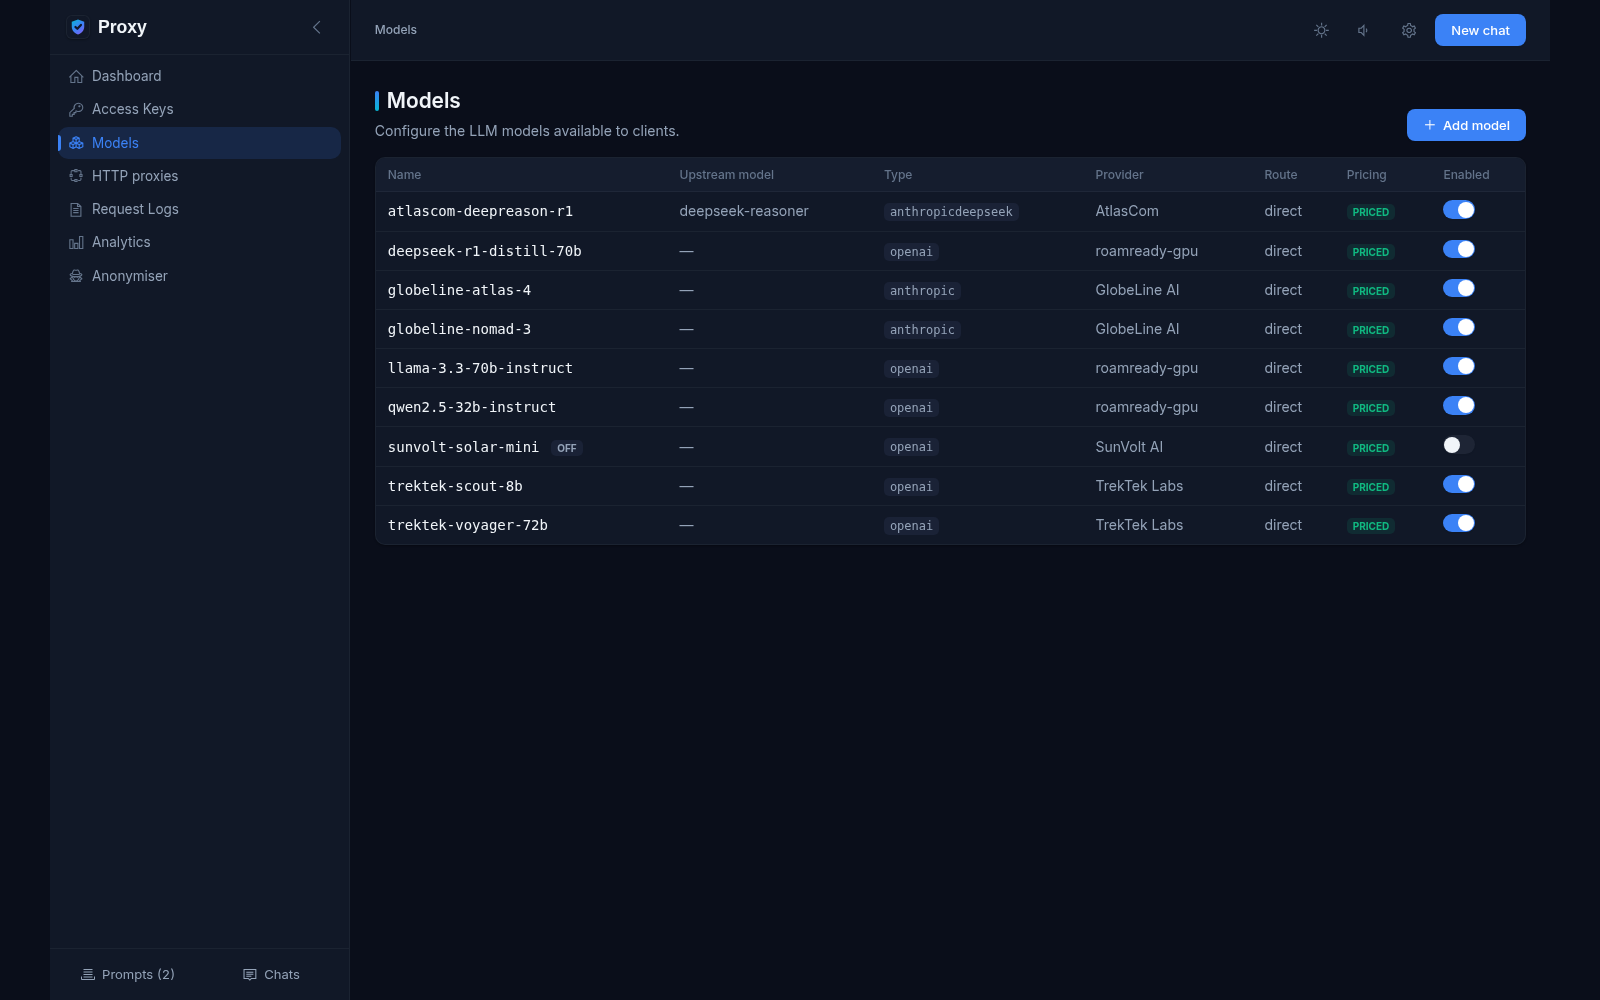
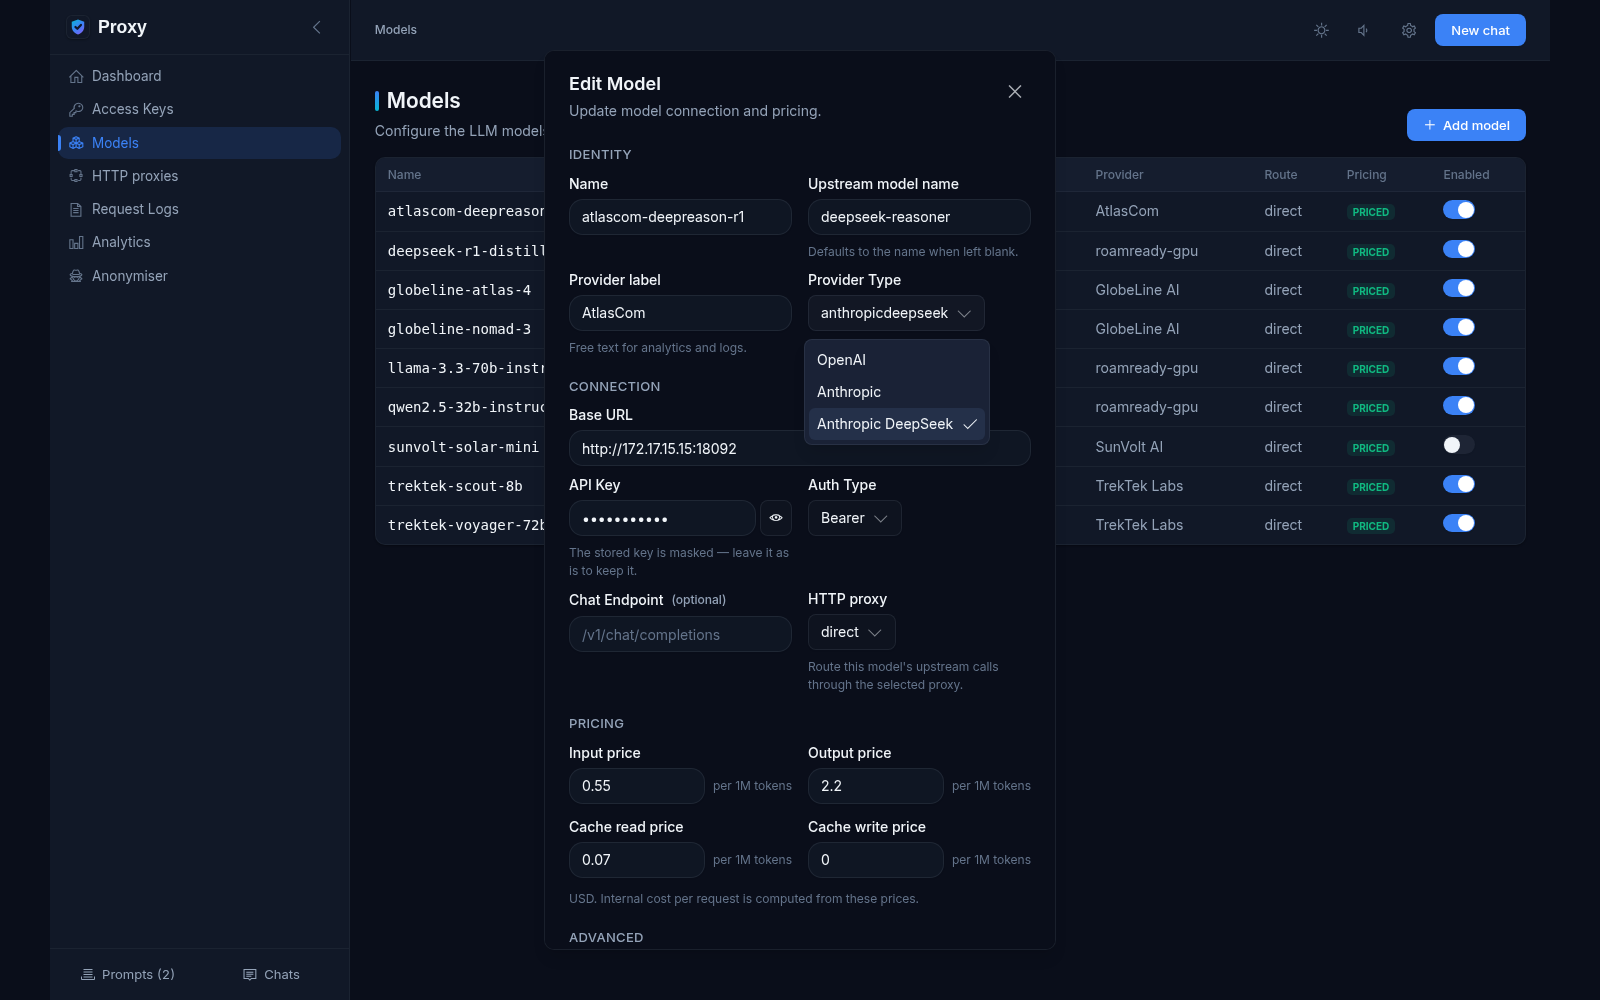
A model is the unit of routing: each has its own connection to the vendor, its own label and its own prices per million portions of text (tokens)
For every model you set prices for input, output and reused input — costs are counted by them
The “Check” button calls the real model address and shows whether the vendor responds; the key is masked
A model can be cloned; it cannot be deleted if that would leave some key without a single allowed model
Any program, any model: format conversion
Three protocol engines work inside: OpenAI, Anthropic and DeepSeek — a program from one vendor works with another vendor’s model
For DeepSeek the request is rebuilt: max_completion_tokens is renamed to max_tokens, and thought blocks are stripped from the text
DeepSeek thoughts are kept for 7 days: to continue a dialogue, the model finds the saved piece and puts it back
If no matching record is found, the model setting decides: a clear “Start a new chat” refusal, or a fixed stand-in
Spending limits: day, week, month, total
Every access key has four spend limits: per day, per week (from Monday), per month and in total; sums are counted in dollars
Limits are checked in order — day, week, month, total; the first one reached stops requests with a clear error message
A limit of 0 blocks the key completely; a request that already crossed the limit runs to the end and is billed in full
The block itself costs nothing, and ordinary proxy traffic is not limited by these limits at all
Request log: who, what, and for how much
The log shows, per request: time, model, key, channel or direct exit, tokens (input, output, reused input) and duration
Two sums stand side by side: the internal one at model prices — it drives limits and analytics — and the vendor price from the response, for reconciliation only
Request and response texts are never stored: the conversation with AI does not pile up in the database and cannot leak from it
Blocked and failed requests are logged too, but with zero cost; ordinary proxy traffic does not get into this log
Requests refused by the license never reach the log: they are stopped before any model is contacted
Settings: appearance, language and service tools
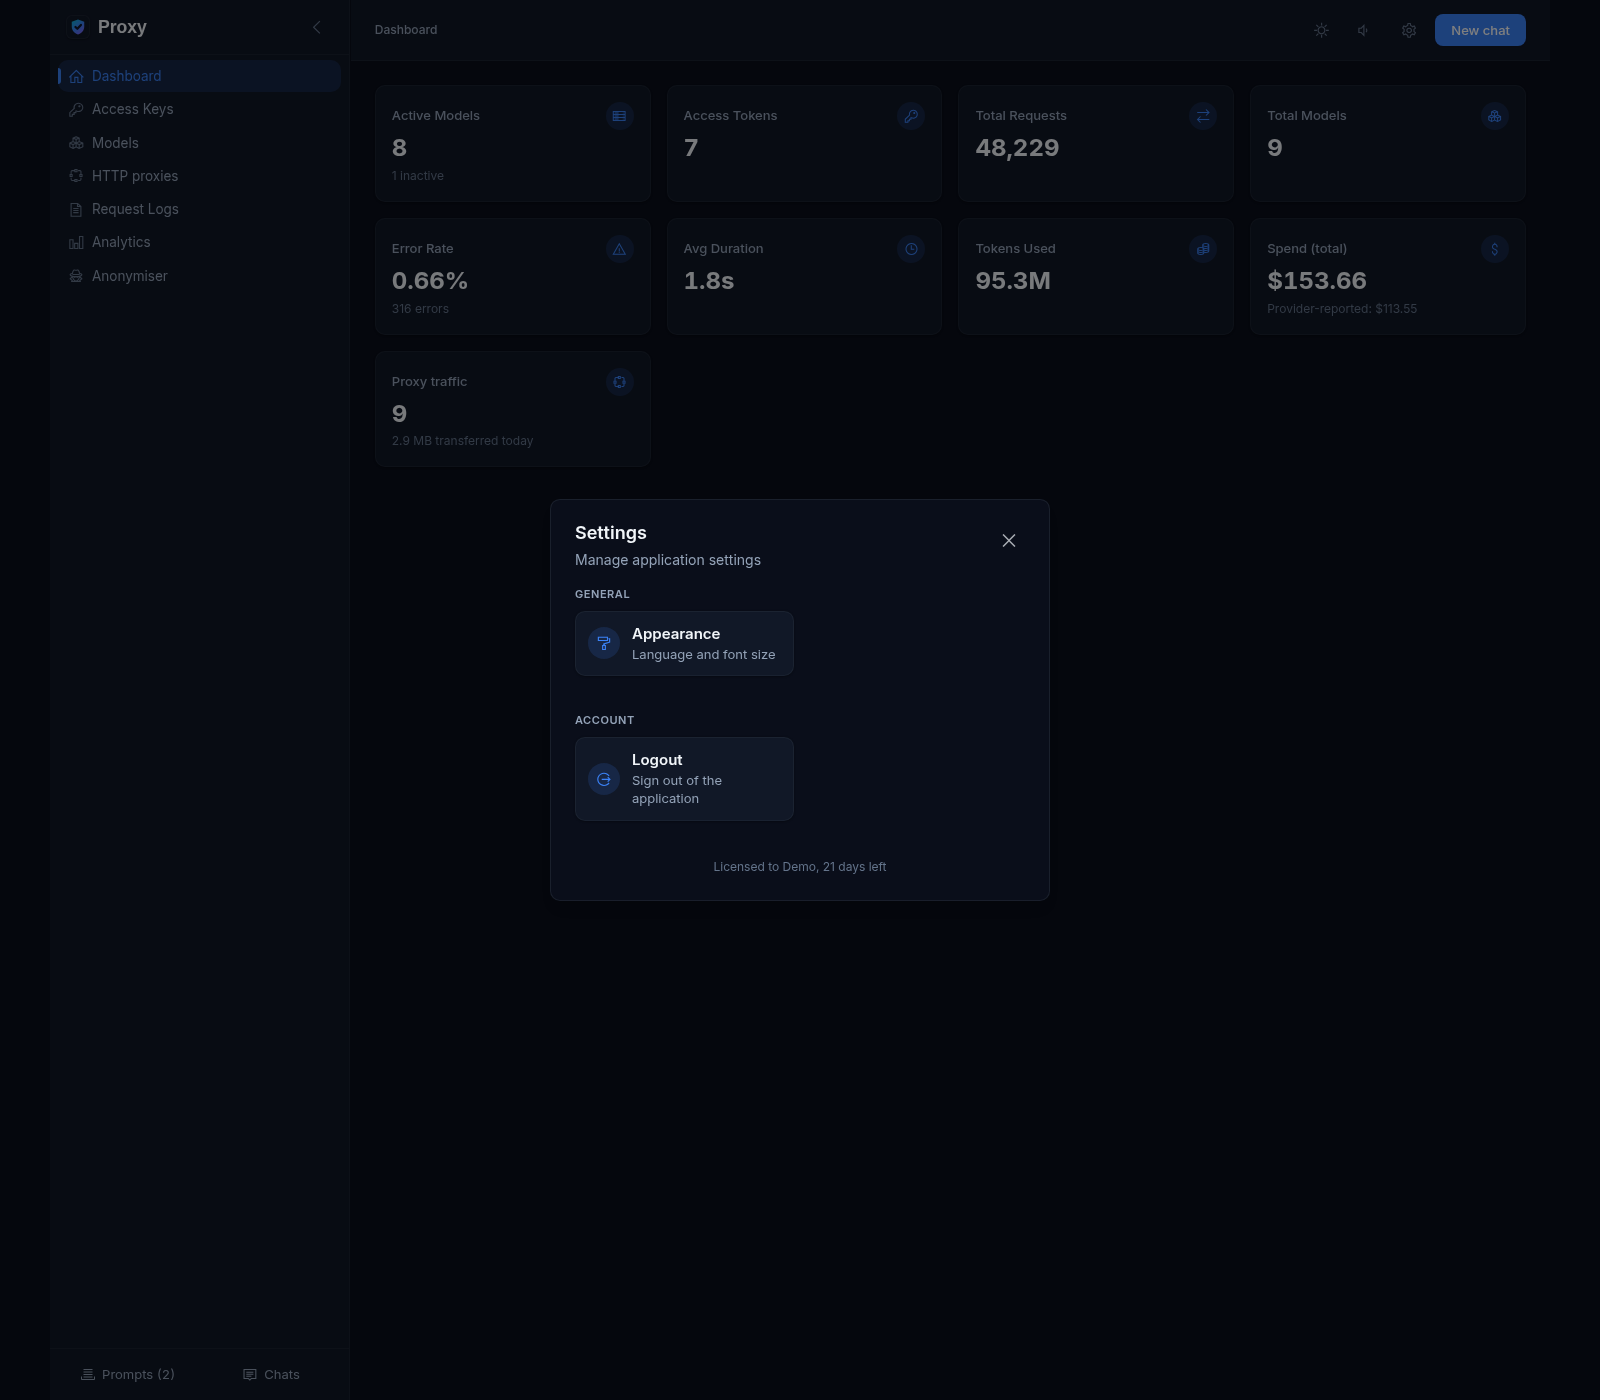
The gear in the header opens the “Settings” window straight away: the “Appearance” card and account “Logout” live there
“Appearance” holds the interface language and the font size; both choices survive a reload. The light and dark themes are switched by a separate button in the header
Two more things only make sense here: the master switch for secret hiding, and how long leak reports are kept — 90 days by default
Service buttons: a connectivity check and, when statistics are sent to an external store, restoring missed ClickHouse days. The license line sits at the bottom of the window and opens the license details
Analytics: volume, latency, breakdowns
Ready-made ranges from “today” to “365 days” plus a custom period; detail is hours, days, weeks (from Sunday) or months
You see the request volume and the latency: average, median and the 95th percentile — the value that 95 percent of requests fit into
There is a breakdown by models, keys and channels, distributions, an hour-of-day profile, error analysis and a comparison with the previous period
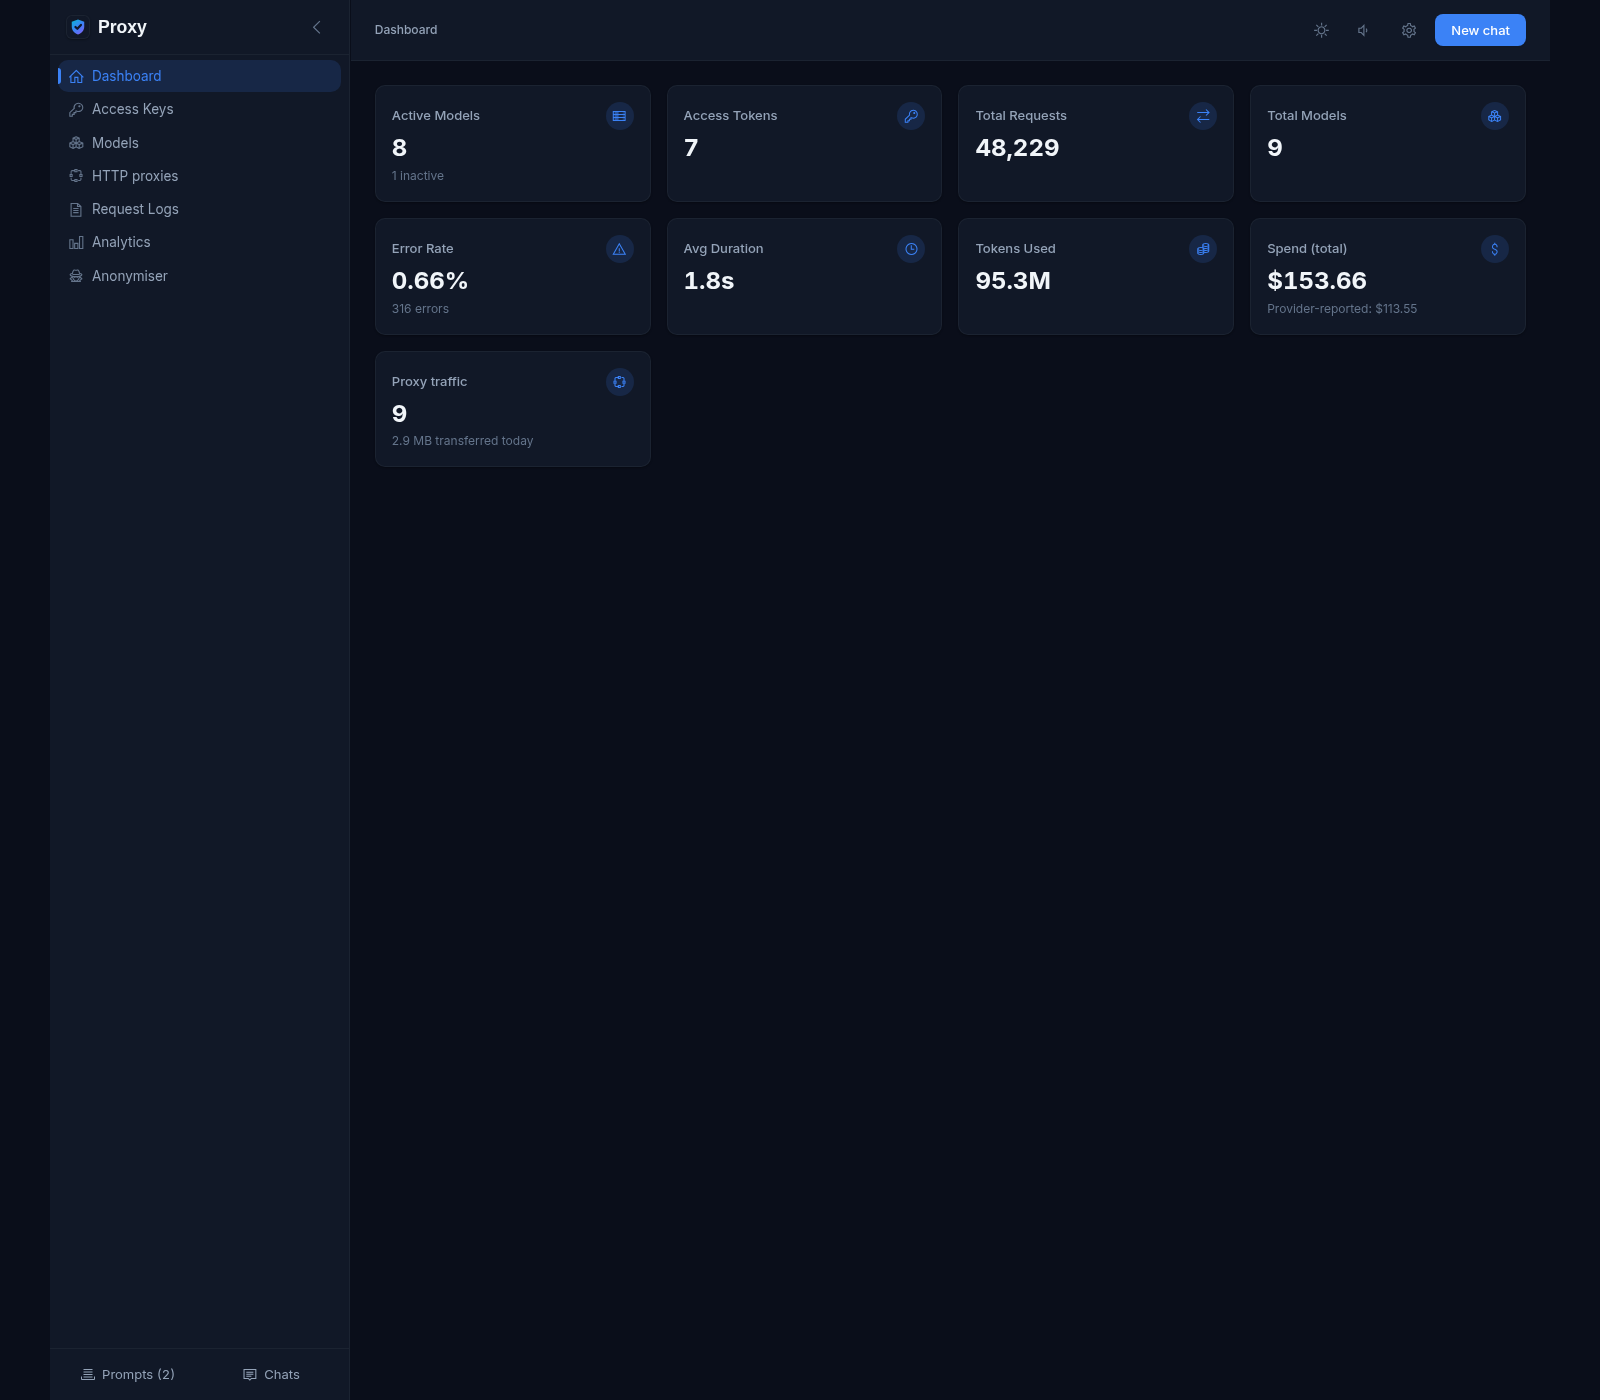
Summary tiles on the Home screen show the day at a glance; statistics can be sent to ClickHouse and missed days restored
Secret hiding: placeholders and putting them back
A rule is a name, a search pattern (a regular expression) and an output template: secrets from the list are replaced with conventional marks before the model sees them
Only values from the list are replaced; numbering is continuous and permanent, and the model never sees the secrets
Putting back works in all responses, including streaming ones, and keeps working after a rule is changed or deleted
If a rule check fails, the request does not go to the vendor — a safe refusal instead of a leak; there is a rule tester for this
Leak reports: where secrets try to escape
Every rule hit is recorded as a leak event — the report shows exactly where a secret could have slipped into a model
Secrets in reports are masked: the value itself cannot be restored from a record
How long reports are kept is set in the settings, 90 days by default; after that, records are deleted
The chat with the AI agent and ordinary proxy traffic do not pass through secret hiding — a deliberate limitation
A proxy for ordinary traffic: HTTP and SOCKS5
The proxy service accepts HTTP and SOCKS5 on one port — it fits browsers, scripts and programs that have nothing to do with AI
Nothing listens right after deployment or after an update: a listener belongs to a channel, and every channel has its own port, its own switch and its own login requirement
Whoever connects to a channel’s port goes out through that channel — support can use one channel and scripts another
Entry is by access key: in HTTP this is ordinary authorization where the password equals the key; in SOCKS5 the same key is checked. The check can be switched off, but the product warns about the risk
Up to 256 simultaneous connections per listener, 30 seconds to establish a connection, and no time limits after that
Each exposed port is opened separately; such traffic goes into its own log (bytes, duration, status, error) and is never counted in money or against limits
Channels: your own proxies, SOCKS5, VPN and Happ subscriptions
A channel is what your traffic goes out to the internet through: your own HTTP proxy, SOCKS5, VPN (WireGuard) or a Happ subscription
Traffic goes only through the channel you picked: there is no automatic failover and no fallback direct exit — binding means “from here only”
There is a connectivity check and password masking; a channel cannot be deleted while models or keys refer to it
A VPN channel needs rights inside the container and WireGuard; the connection is raised on demand and drops after 60–75 seconds of idle time
A Happ subscription is a channel too: the link is re-fetched on every core start, the server is matched by name, and a server the core cannot run is flagged as unsupported
A chat with the AI agent inside the product
The chat is an optional add-on: it connects to an external Agent by address and key, and without that setting it is simply hidden
The agent key stays on the server and never reaches the browser; answers arrive in real time
In the chat you can ask about the interface, sort out an error and get a settings hint — all without leaving the product
Without the chat everything else works: keys, models, logs, limits, analytics, secret hiding and the proxy service
Hosting: configuration, runtime state and logs
One container serves both the interface and the /api/* addresses; the only required setting is an external PostgreSQL database
One port is enough for the interface and the /api/* addresses; proxy service ports are published separately, one per exposed channel, and HTTPS is configured outside
Settings, models, channels, access keys and secret-hiding rules live in plain files in the configuration folder: keep them with the project, edit them by hand, move them to another server — an edit is picked up in about 300 ms
Runtime state (saved thoughts, the session signing key, secret matches, VPN configurations and the working files of Happ subscriptions) lives in a separate volume, while the logs and the spend totals stay in PostgreSQL
Without the volume, secret matches and saved thoughts are lost; without a permanent session signing key, every issued login session is lost
Secrets can live in one .env file next to the project: the product folds it in at startup and follows edits while it runs
License: the interface works, traffic needs a key
The license key is set on the server with the AGENT_LICENSE variable — either the key itself or a path to a file with it. The key is read at startup, so a new key needs a container restart
Without a valid key traffic does not pass: model requests get a clear refusal and the proxy service turns connections away — every such refusal is visible in the log
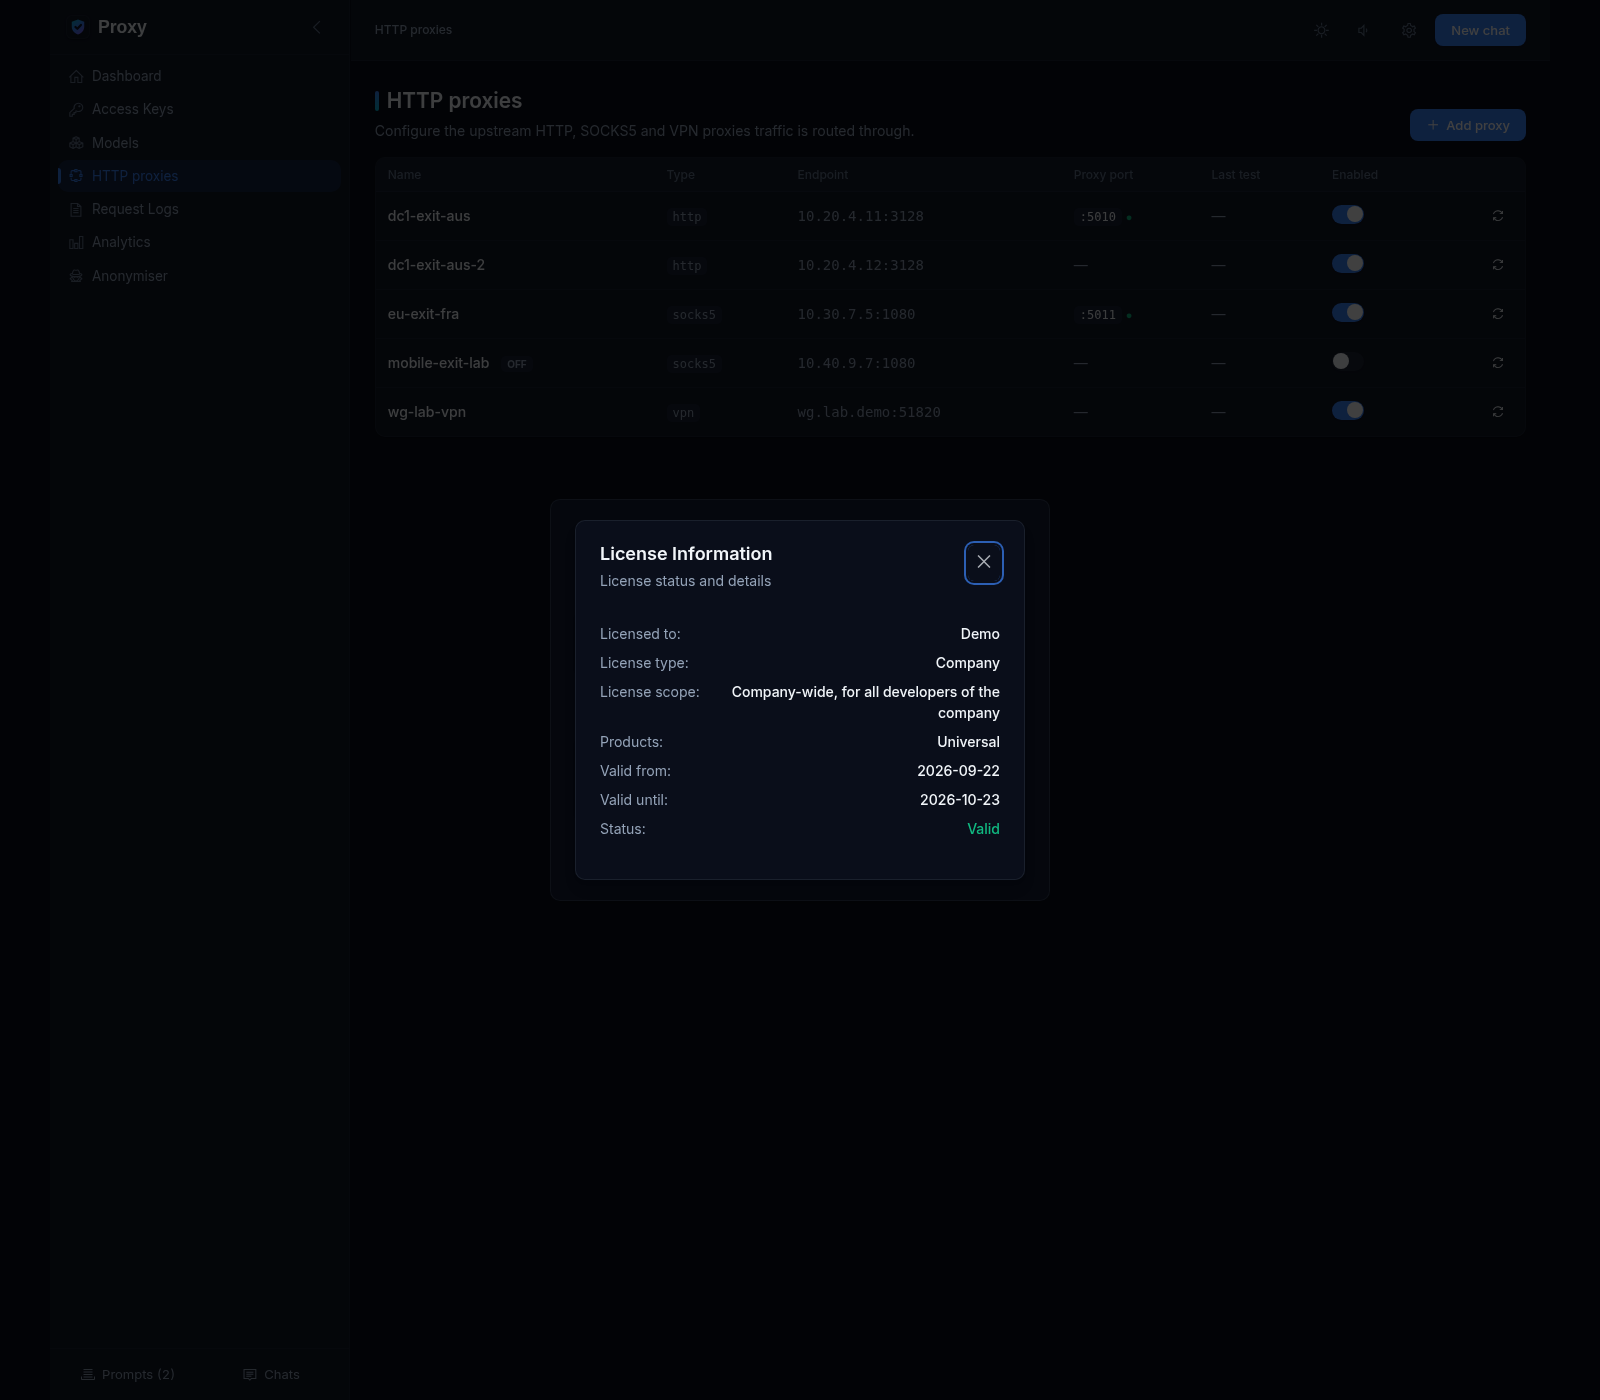
The interface, the settings, the logs and the management API are never gated by the license: you can always sign in, look at the state and configure everything. The license line sits at the bottom of the settings window and opens the license details when clicked
The expiry is checked on the fly: when a key runs out of its date, traffic stops at once, without a restart. A trial key is no different from a paid one in what it can do
Happ subscriptions: someone else’s VPN behind your proxy
A Happ subscription is a ready-made internet access sold for the Happ client: one link instead of an address, a login and a password
Paste the link into a new channel: the bundled Xray core fetches it on start and brings the connection up by itself — the core is already part of the product
The server is picked from the list the product shows for that link, together with the remaining traffic and the expiry date; servers the core cannot run are flagged
If the subscription stops responding, the working files of the last successful download keep working; the core starts only on demand and shuts down after 60 seconds of idle time