Interface testing that learns once: capture a page and describe the problem in words — from then on the agent re-checks it with rules and compares every build against an approved baseline
Test Agent is a program for checking your website, app or internal system, which you run on your own server. You open a page in Chrome, capture the screen and explain in words what is wrong — the AI turns the comment into a rule: a small check that from then on runs right in the browser. A rule works fast, costs nothing and finds the same problem on all similar pages, so the longer the product works, the less AI is left in it and the cheaper checking becomes. Tests are assembled from rules and recorded actions, tests run on a schedule — the built-in runner inside the container executes them, so a separate computer with Chrome is not required — every step leaves a snapshot as evidence, identical errors merge into a single issue, and the agent repairs broken checks by itself. The product also compares every build against an approved baseline: a shifted layout, a changed color or a missing block is visible in the picture, even though they are hard to describe as a rule. A human reviews the differences — the AI only suggests. And if something is missing, you can extend the product with your own Python scripts: a file in the project folder becomes a test step, a comparison engine or a finished-run handler — no rebuild of the product needed for that. And search across the whole app helps find what you need — a rule, a screen, an issue or a knowledge file: just start typing in the sidebar field.
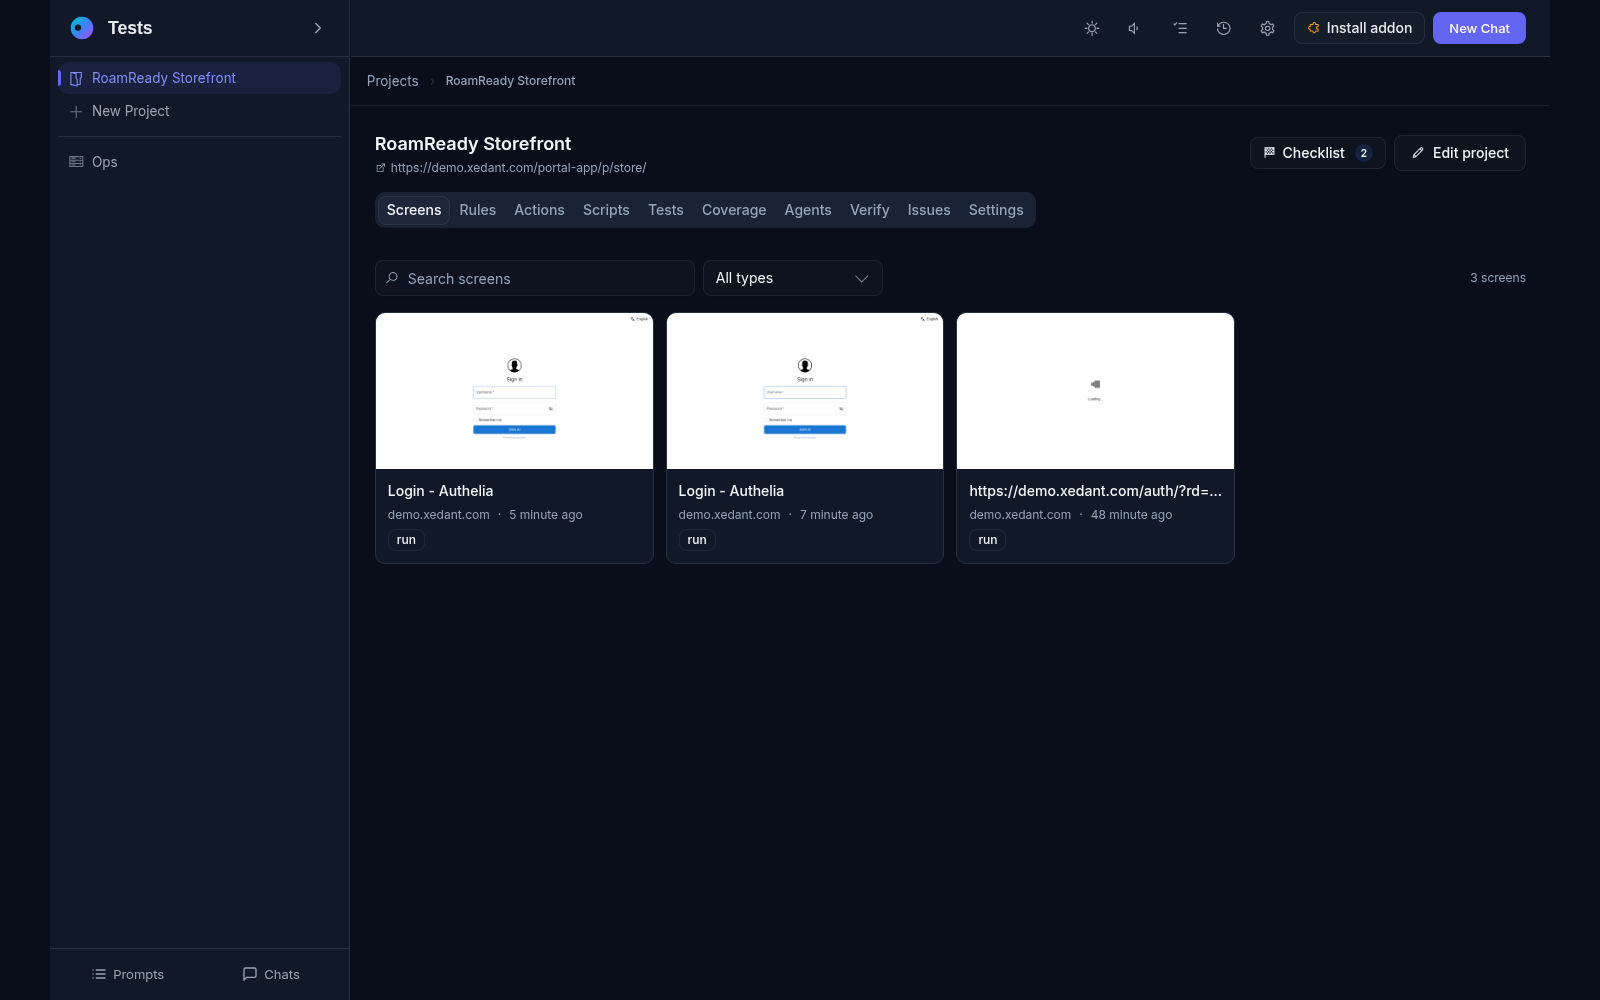
Screens in one click: a snapshot of the visible area, the address, the title and the page structure are saved at once
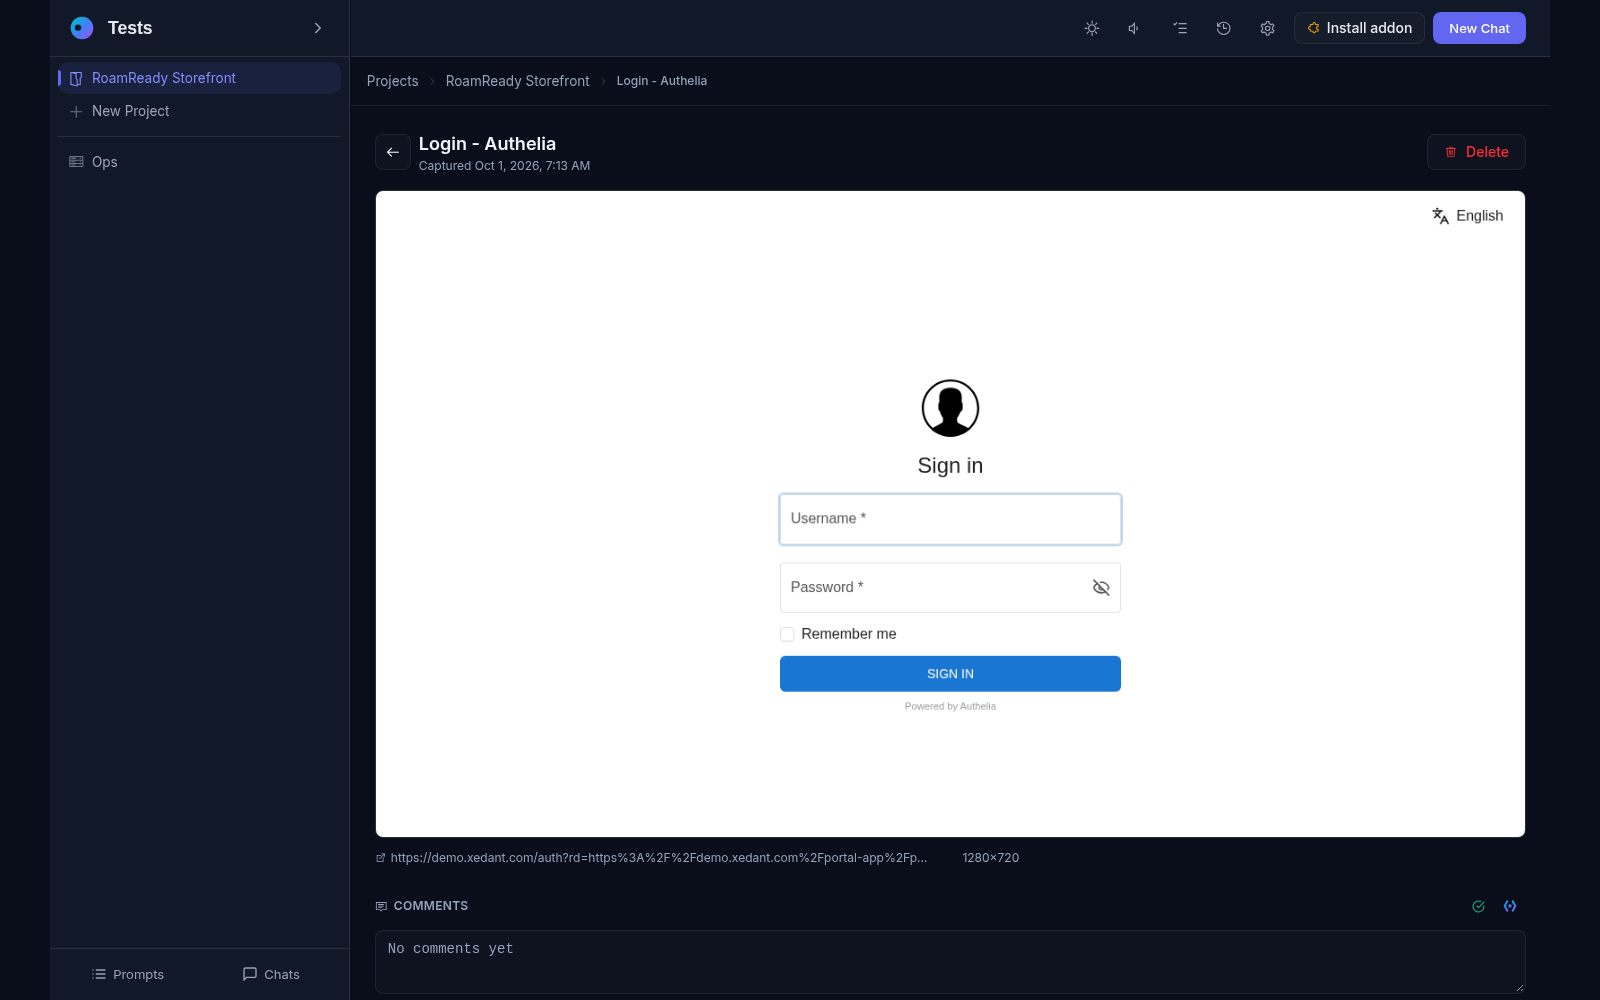
Comments in plain words right on the page: “the button is invisible on the dark background” — and that is all, no machine-style wording
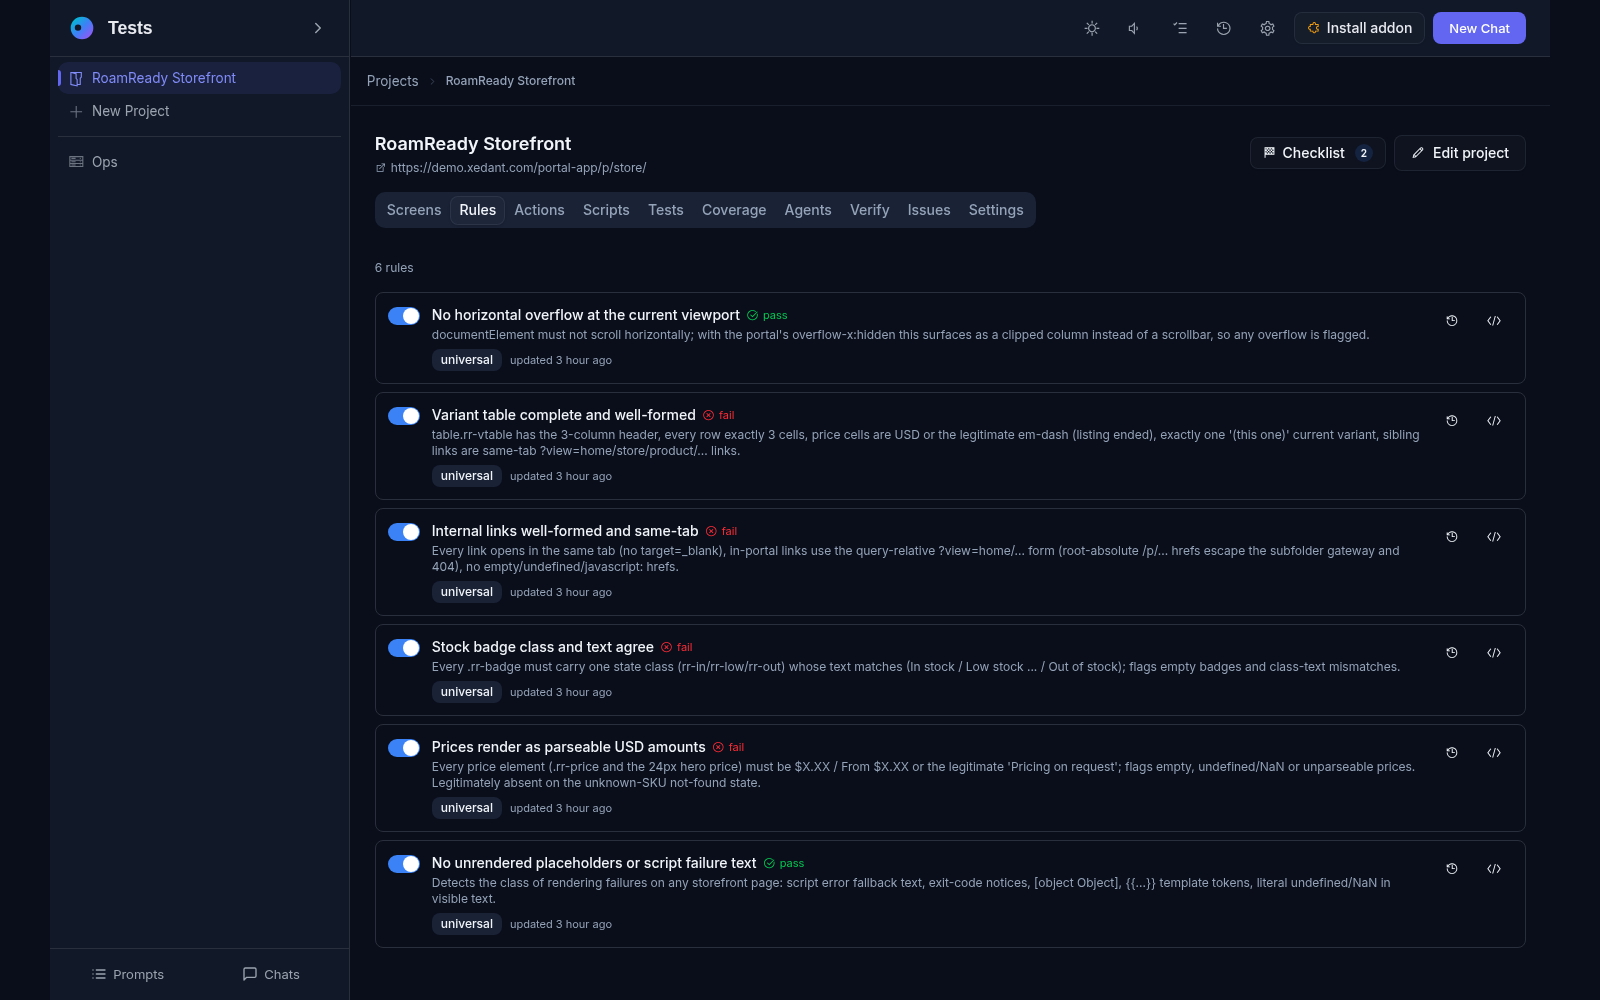
AI turns one comment into a check for a whole class of problems, not for a single page
A check is plain JavaScript that runs in the browser without calling the model: fast and free
The test-manager skill is bundled and tells the agent how to write checks
A knowledge box for the project: the agent writes down what it has learned about your interface
Screen types: login, payment, account — checks are bound to the pages they belong to
Visual capture for a test step: a full-page shot with anti-flake stabilization and masks over dynamic regions
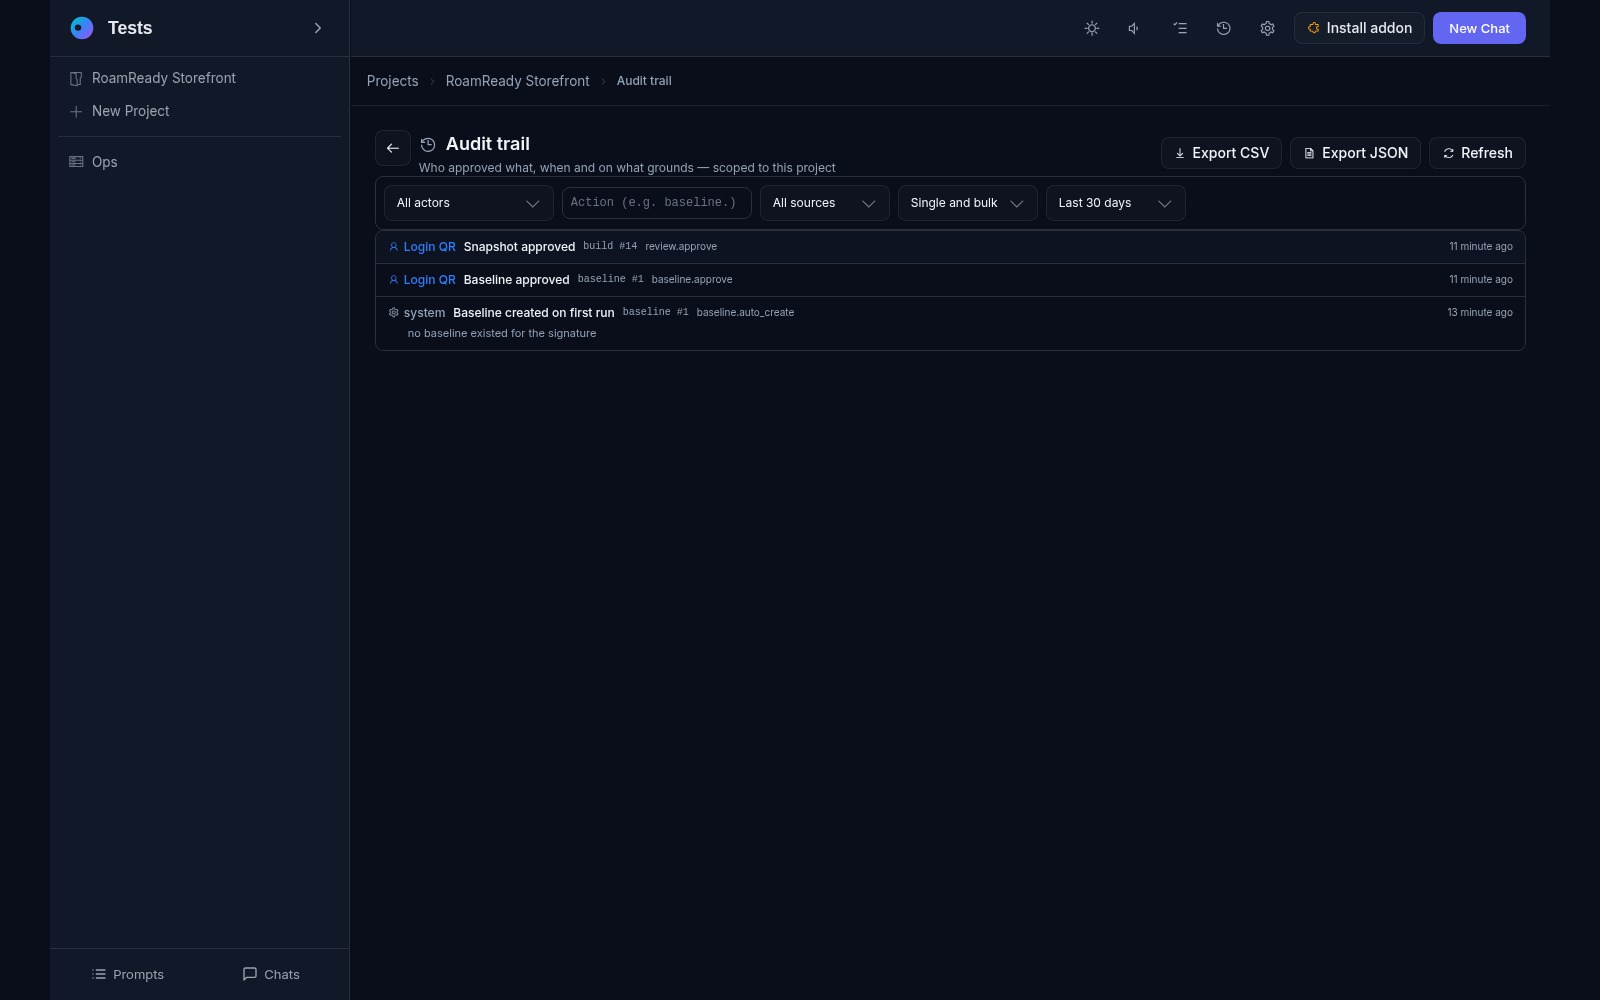
Baselines under control: every one keeps its version history and shows who approved it and when
Scripts extend the product without a rebuild: a Python file in the project folder becomes a test step, a comparison engine or a run handler
Runs out of the box: the built-in runner inside the container executes tests with no separate Chrome and no addon
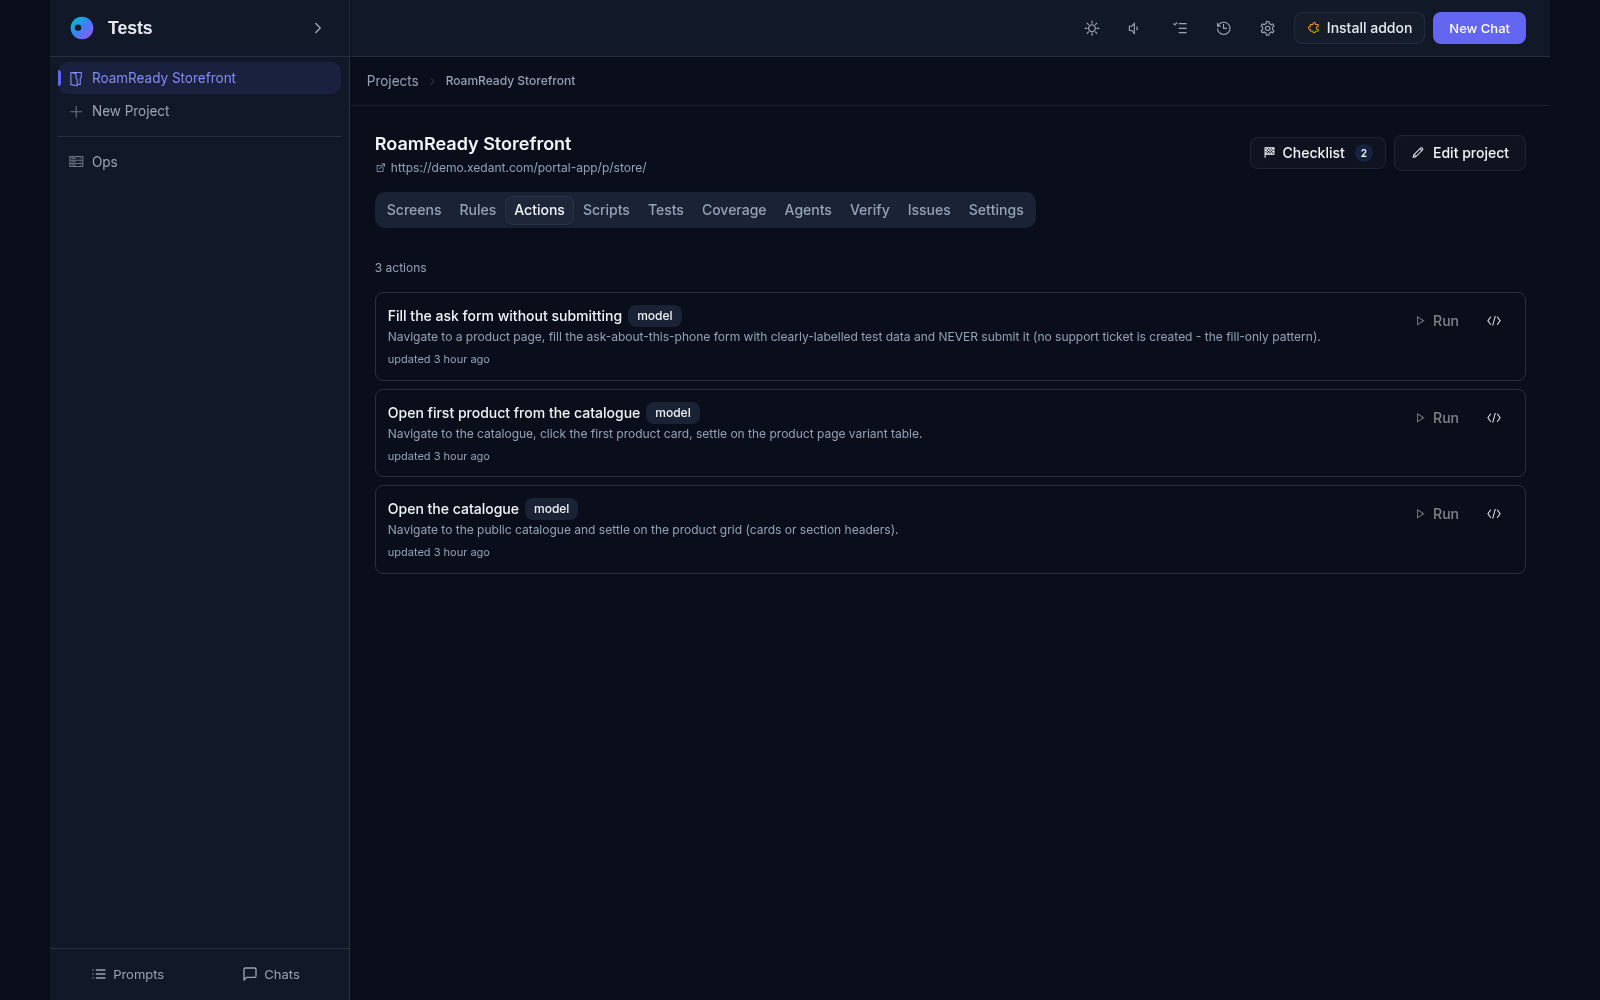
Actions: record the login and the clicks once — they repeat on every run
Actions in plain words: describe the task — the agent writes the script, you run it and confirm
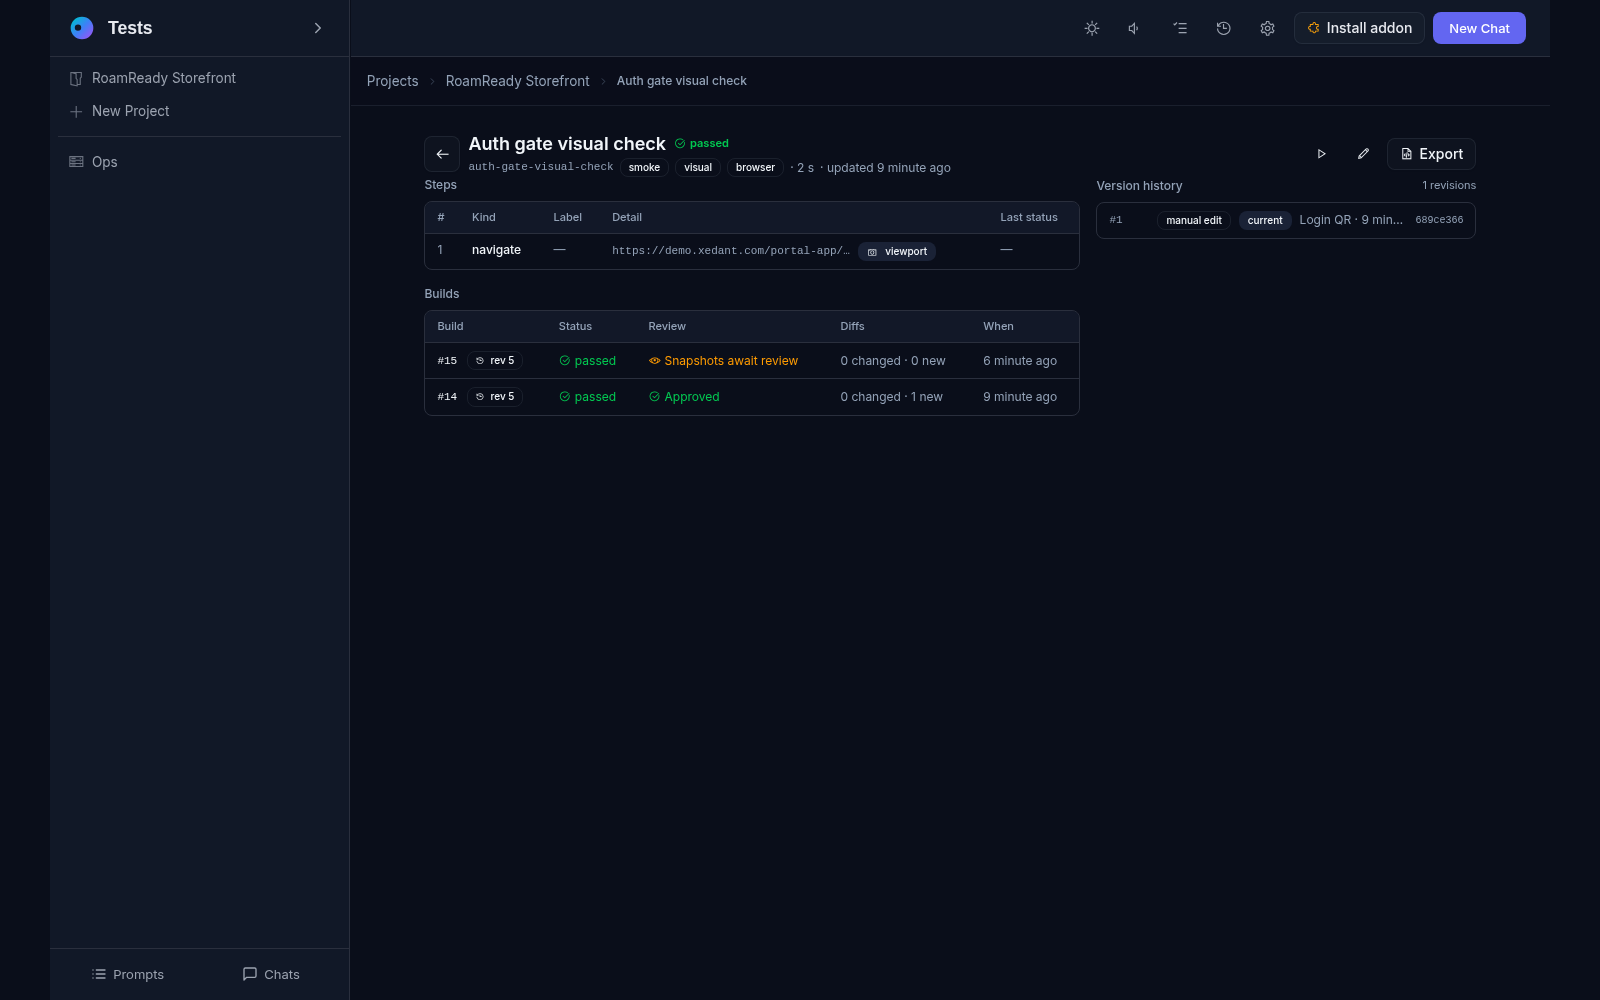
Tests: a sequence of steps — open a page, run actions, check the rules
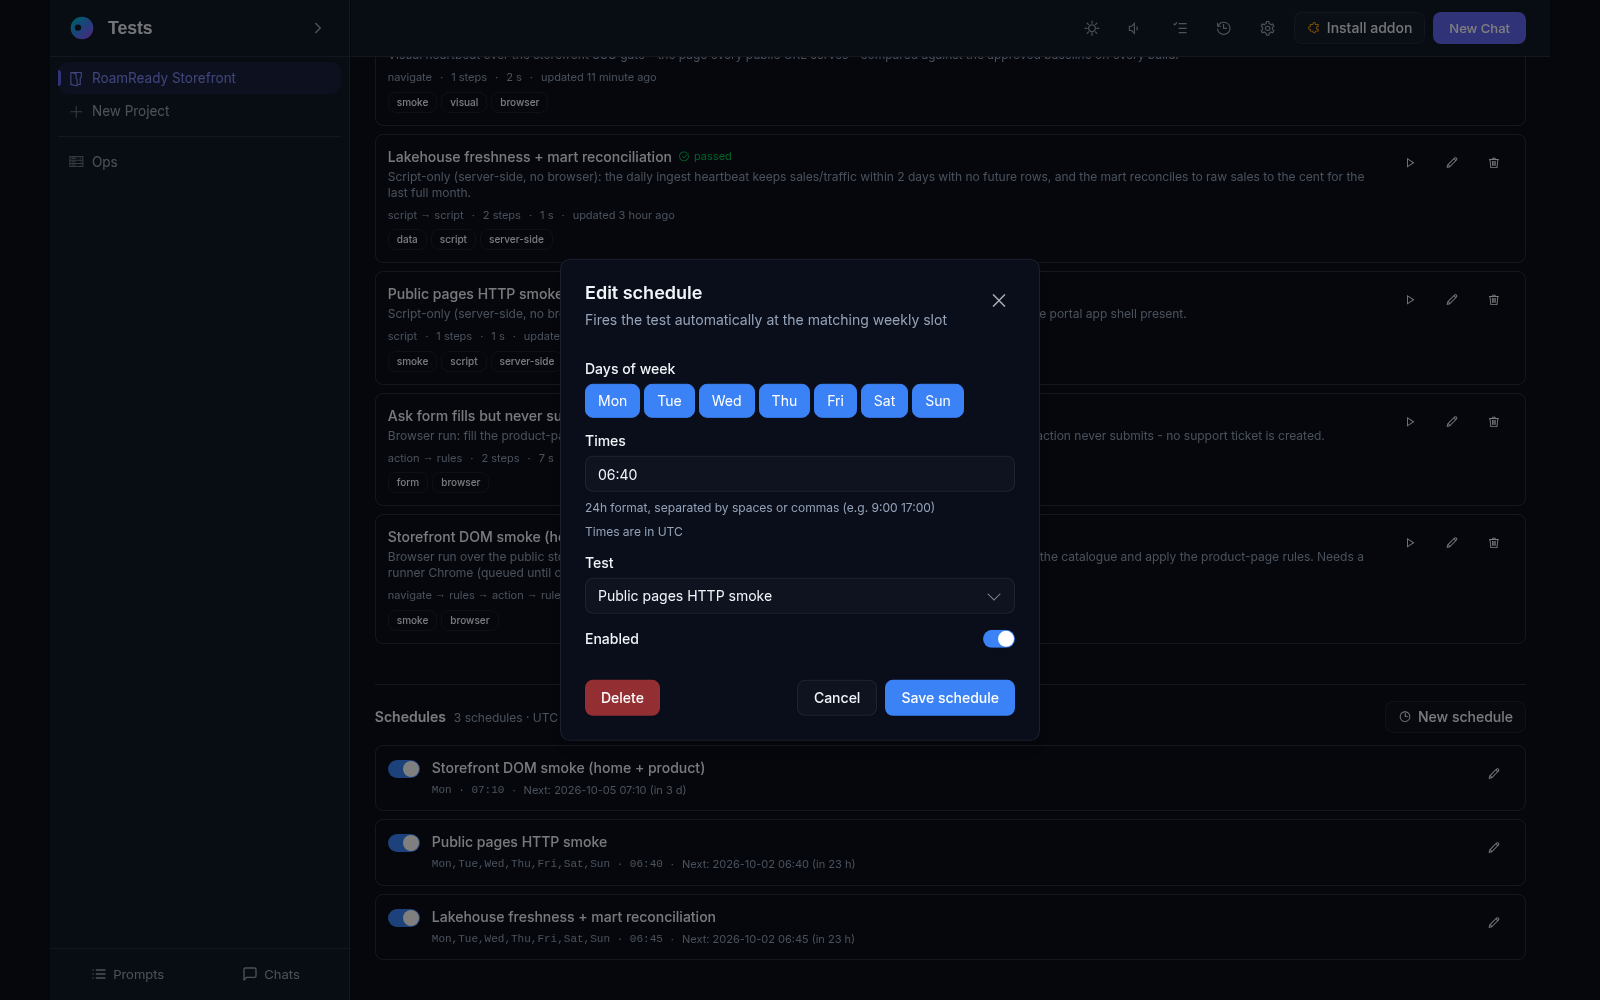
Schedule: checks every day or on the weekdays and hours you pick
Evidence: a screenshot for every step, including the failed ones
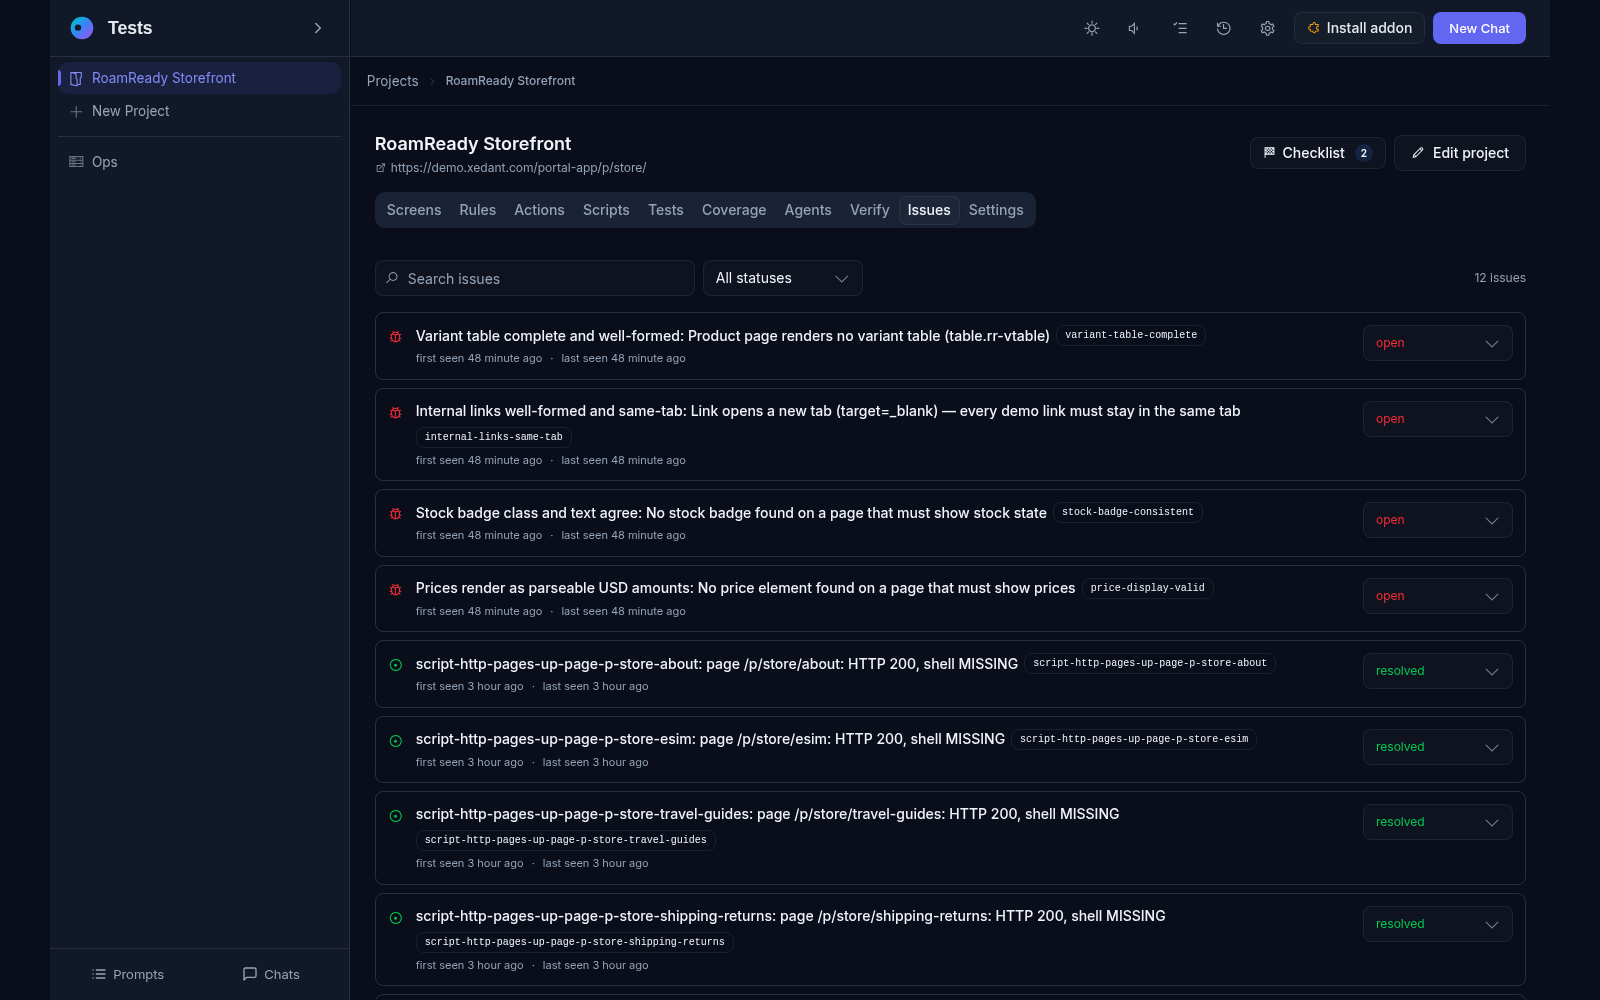
Issues: identical errors merge into a single entry with a repeat count
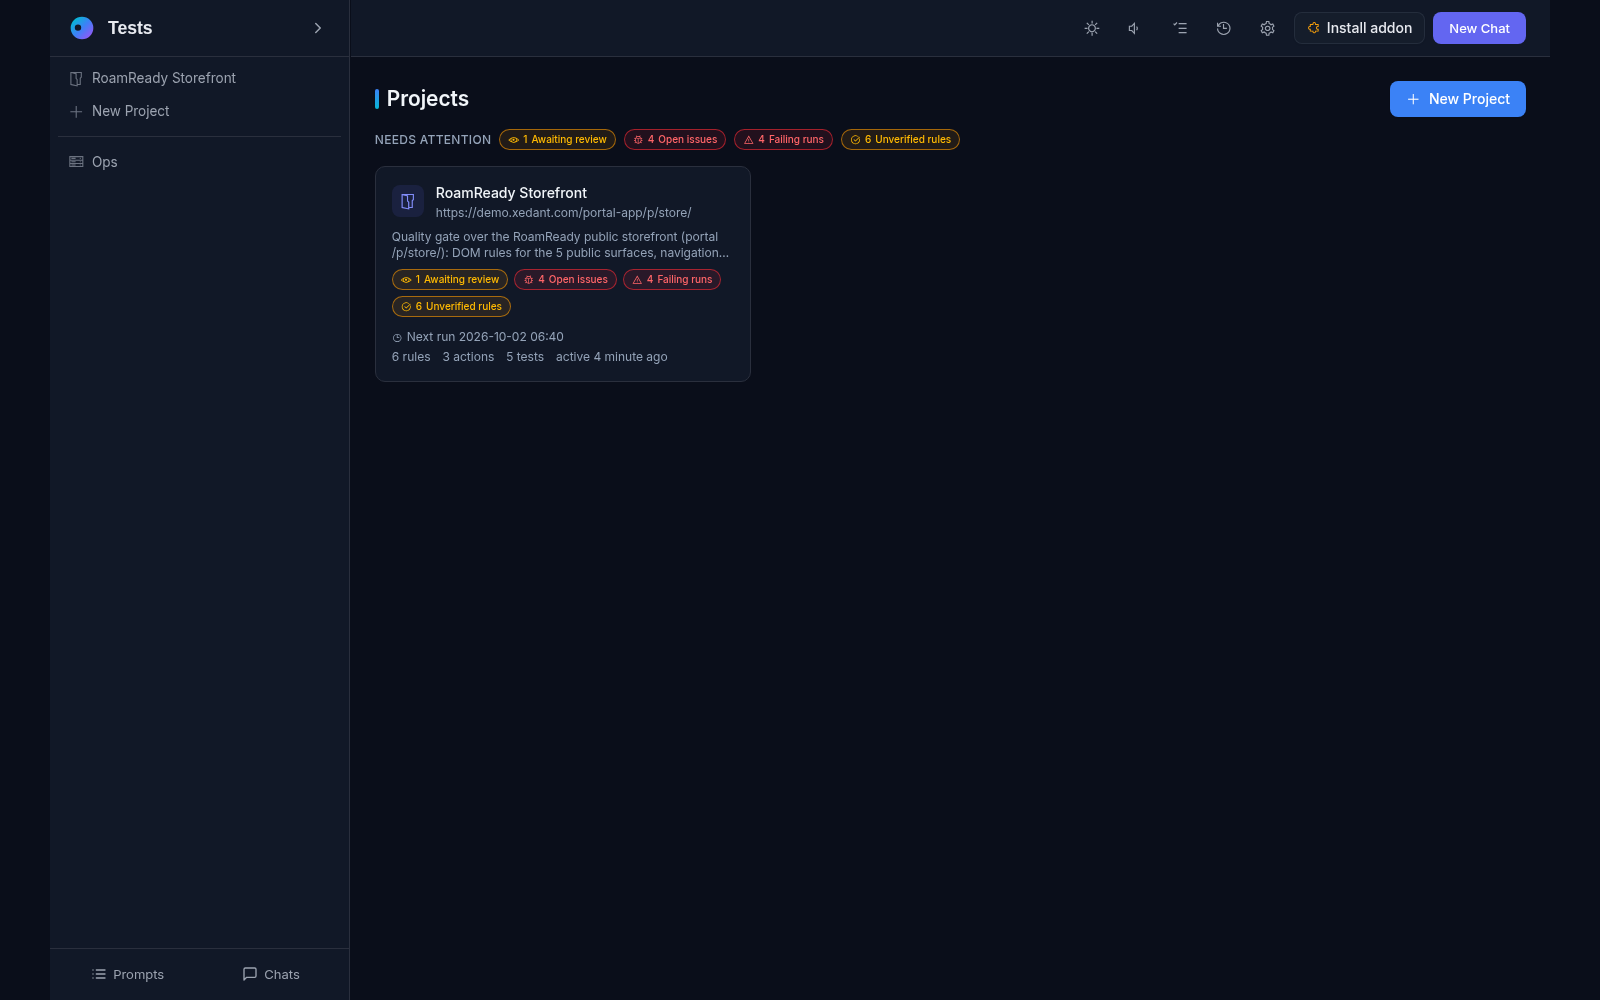
An attention summary: badges per project and a jump to the right tab
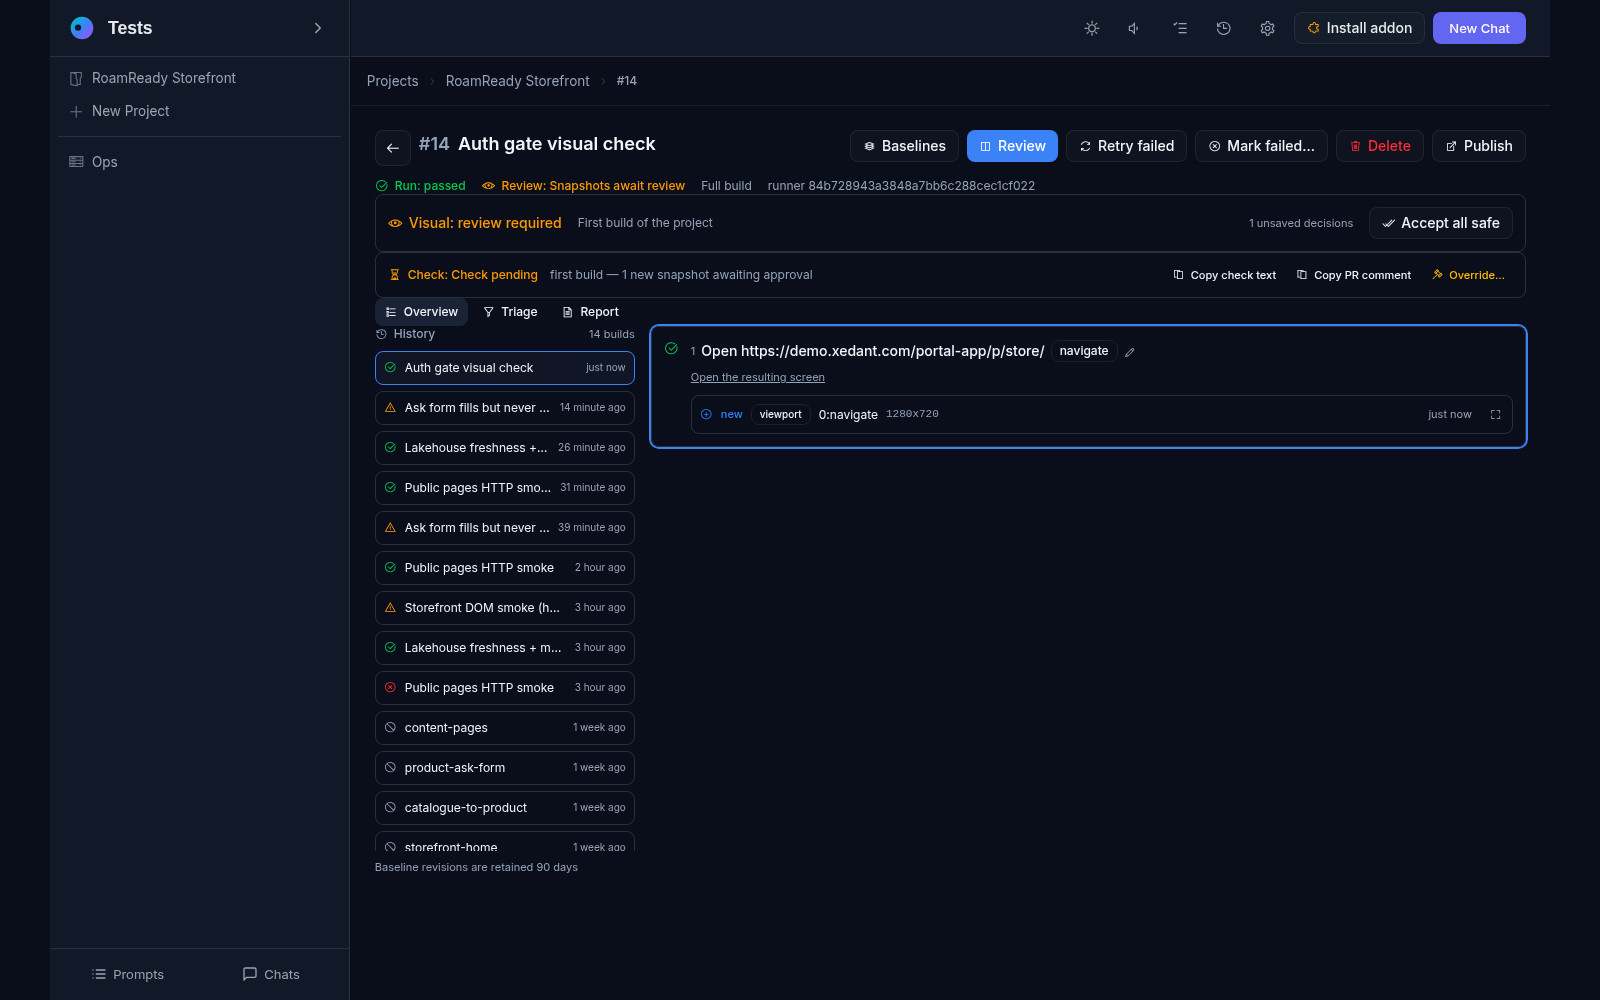
Builds instead of single runs: every one carries a branch, a mode and a review state
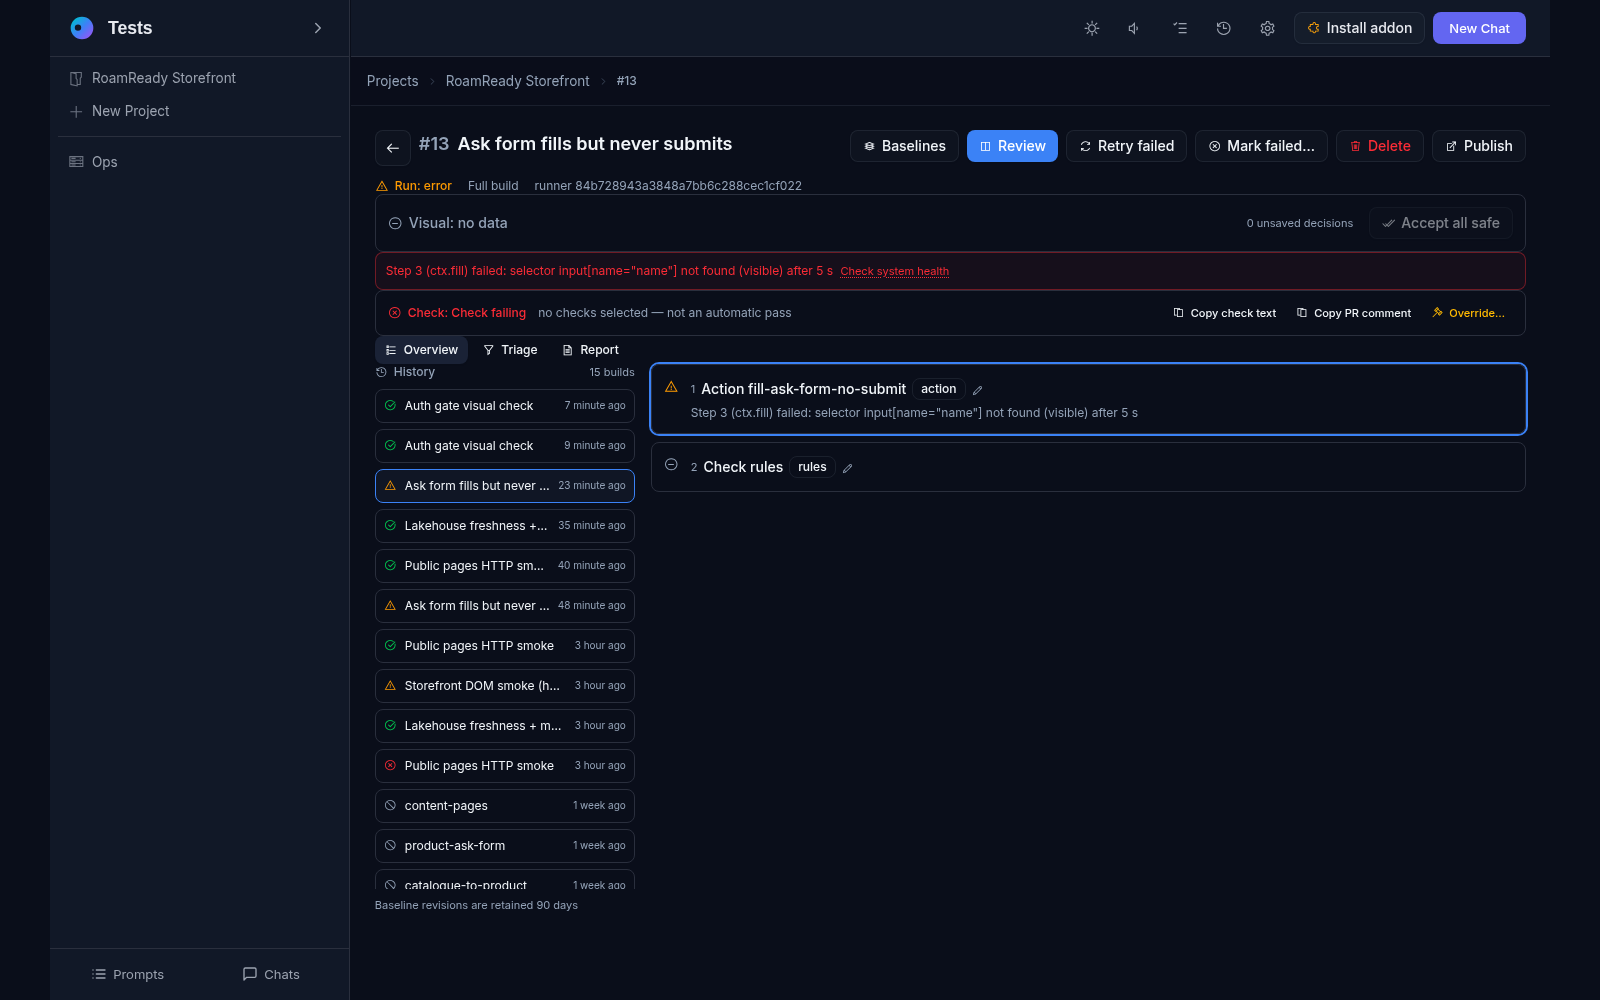
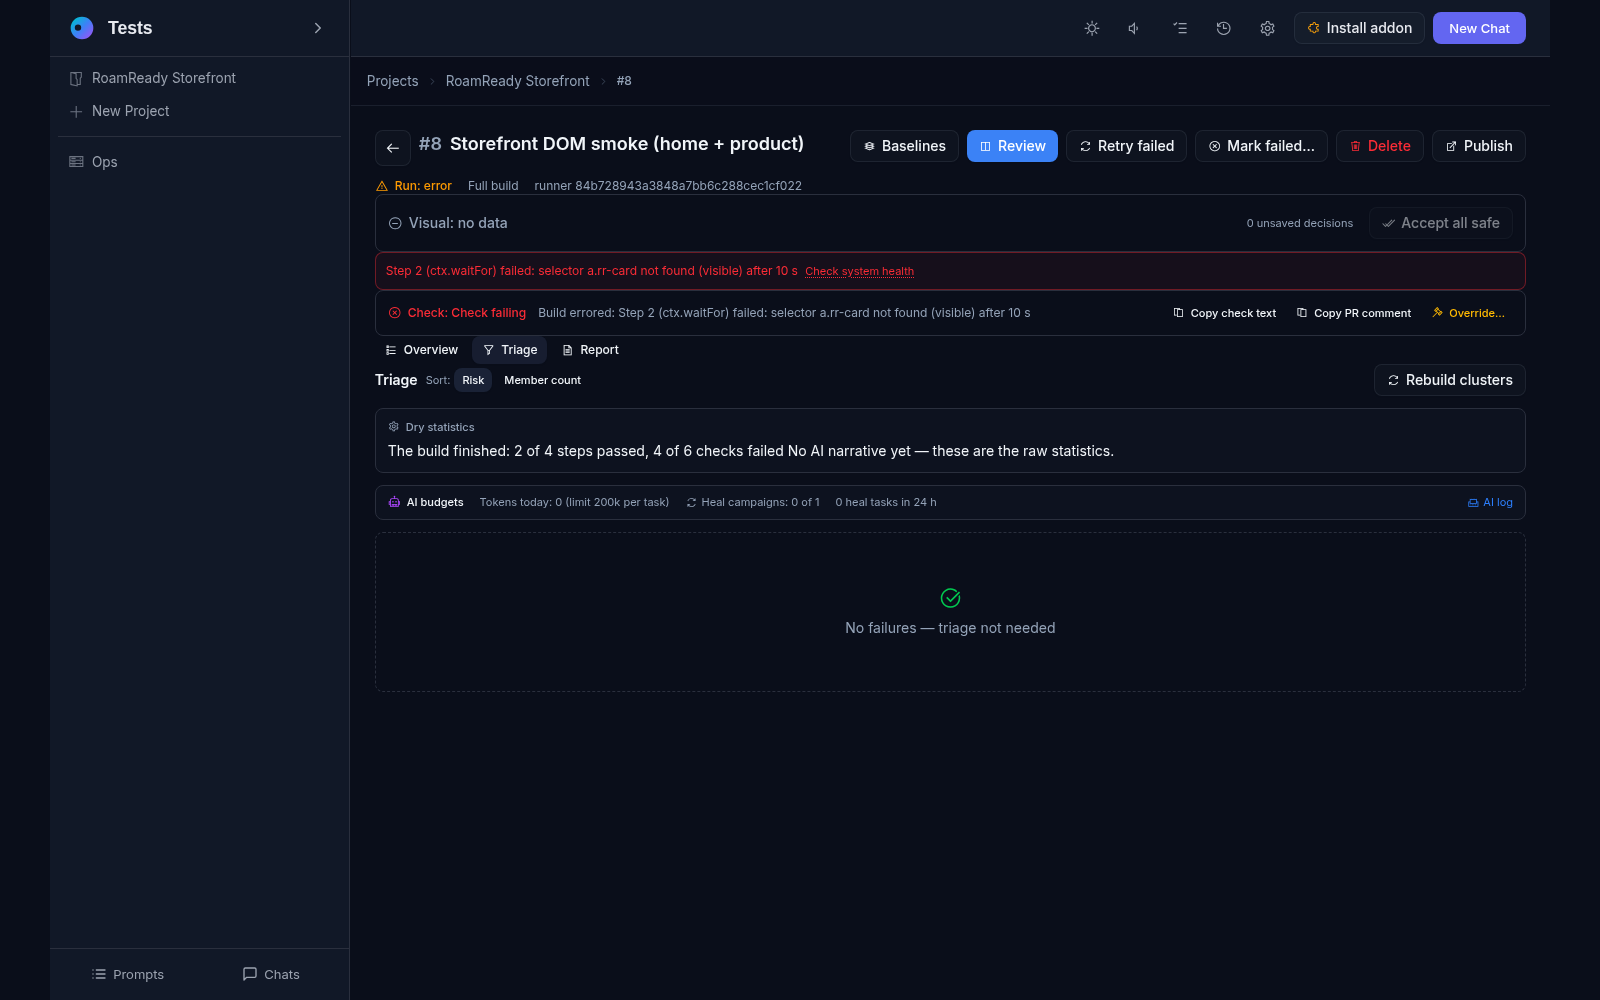
Build failure triage: identical failures cluster by root cause with a plain-language explanation
A test made entirely of scripts runs without a browser: API address, database and file checks run on a schedule like ordinary tests
Search across the whole app: projects, screens, rules, tests, issues, scripts, knowledge and docs files in one field (⌘K)
Self-repair: if a check breaks, the agent fixes it and marks it as needing a review
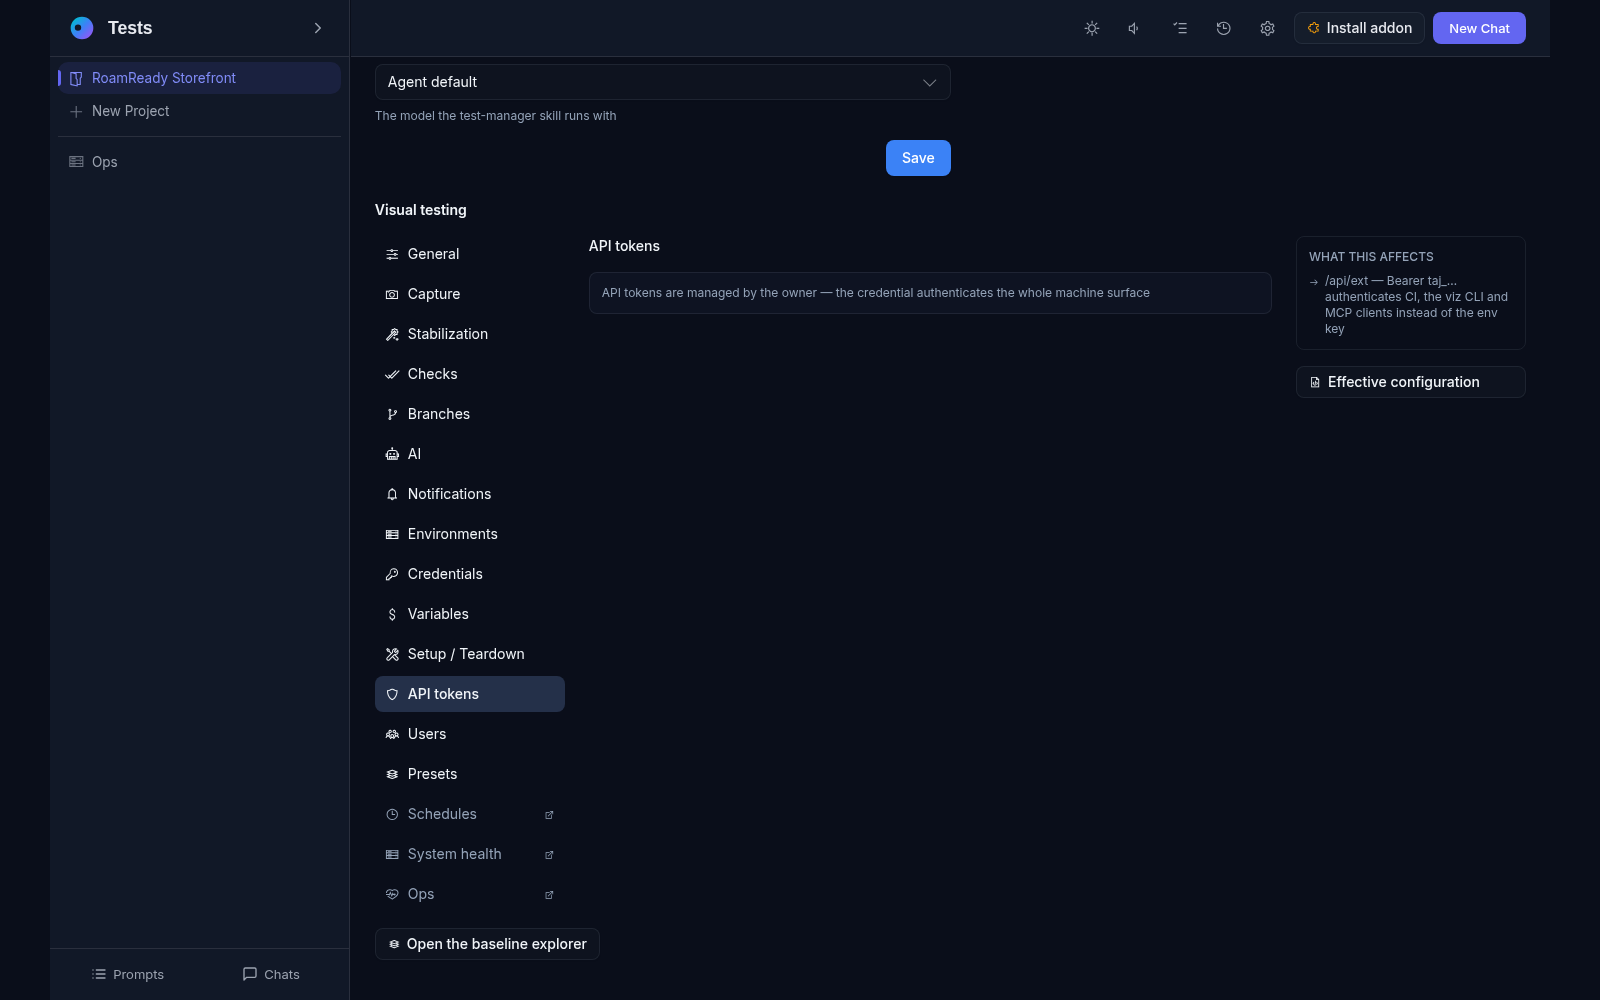
External access: list issues and change their status by a key — for a coding agent
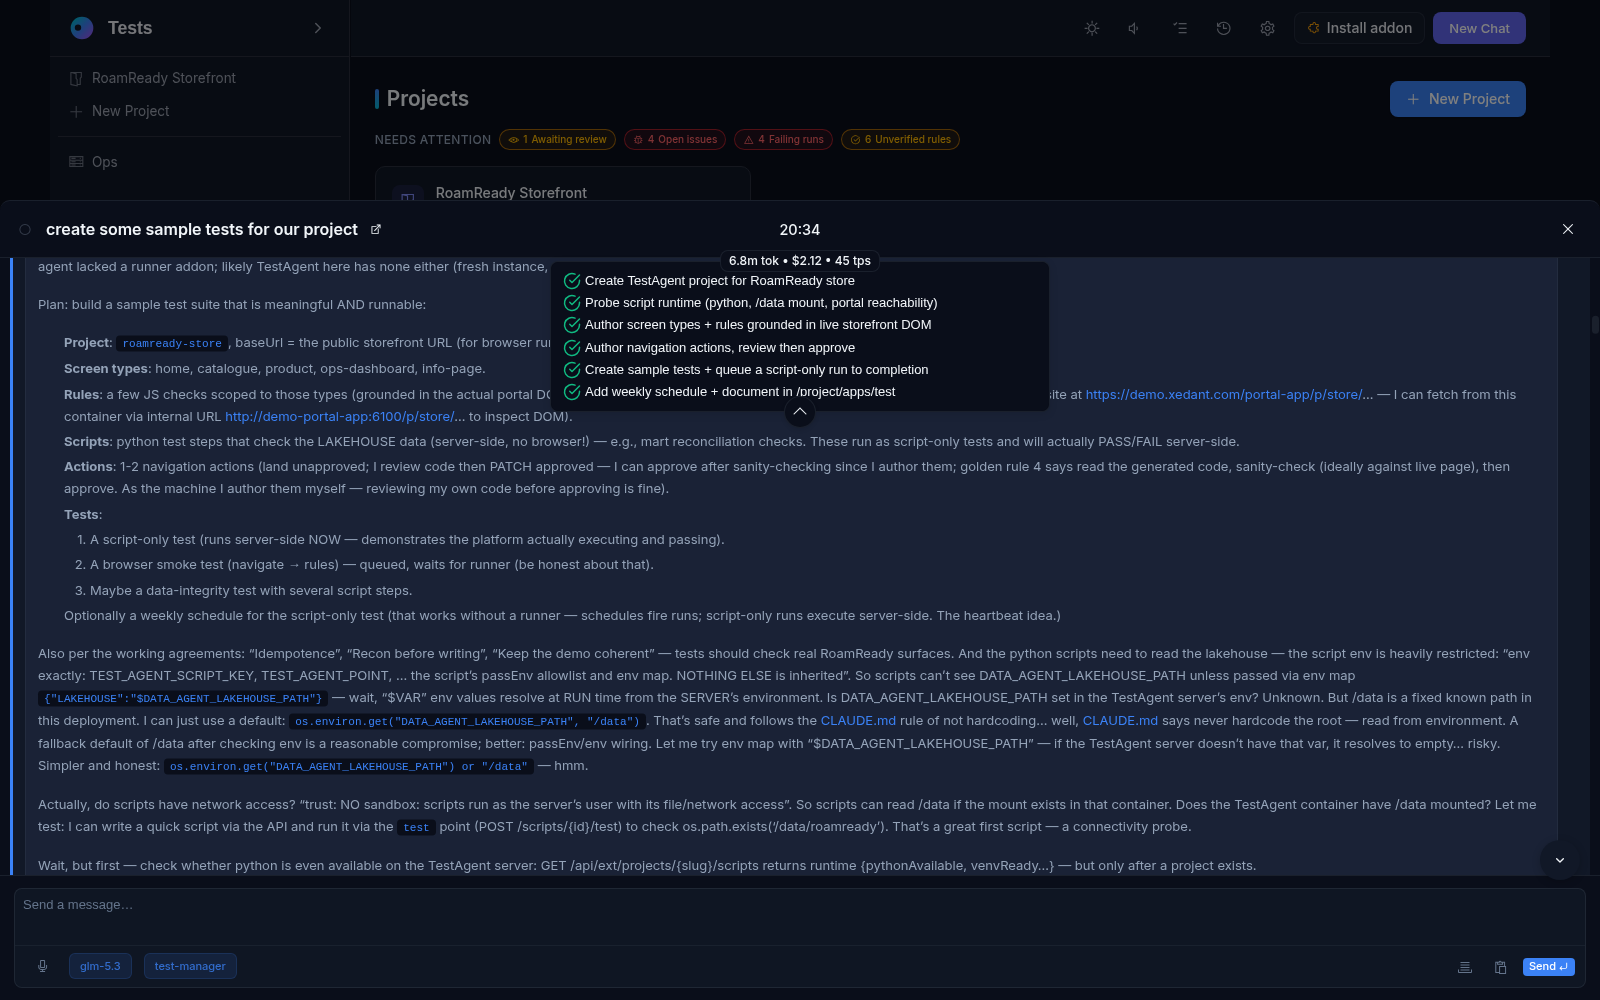
A chat with the AI agent inside the product: analyses, fixes and questions about the interface
A live page: the model can look at and click through your open Chrome tab
Everything on your own server: one container, the data and the screenshots stay with you
Projects are folders under git: checks, actions and tests are plain files
A license is needed only to send a message to the agent: checks and runs always work
The verdict is always a human’s: the AI only suggests, a reviewer approves or rejects
Coverage and the app map: see what the tests already protect and what is still open
Every script run leaves a log entry: the connection point, the source, the status and the error tail on failure
Idle is quiet: background tasks wake on events instead of timers, and memory is returned after 15 idle minutes
Auto-repair is opt-in per test: the agent fixes broken checks only when the test’s switch is on — off by default
Screens: what the page looks like right now
A screen is a snapshot of the visible area plus the page’s address, title and structure
The snapshot is taken with one button from the addon panel and saved at once — no interim “review and save” step
Every capture shows where it came from: taken manually, produced by an action, or left by a run
The image is stored in the database together with the project — files are not scattered across the disk
A comment in plain words — and the check is ready
A comment is plain text: “the button is invisible on the dark background” — no machine-style wording
Press “Call agent” — a report is placed into the chat: the comments, the snapshot, the project’s knowledge and rules
The reply is a finished rule — a small check you can run right away
Comments are not analyzed on their own: a person starts the analysis, so nothing is spent in vain
Checks without AI: fast, free, every day
A rule is a small script the browser runs by itself, with no calls to the model
A check fits into a couple of seconds, so you can run it on every release
The more rules you accumulate, the less work is left for AI — checks get cheaper
A rule sees contrast, sizes, counts and the text of elements, not just “the element exists”
Actions: log in, pay, open the account — record once and replay
Start recording in the panel, work as usual, stop — the steps appear as a list
Passwords never reach the files: a variable from the project settings is substituted instead of the value
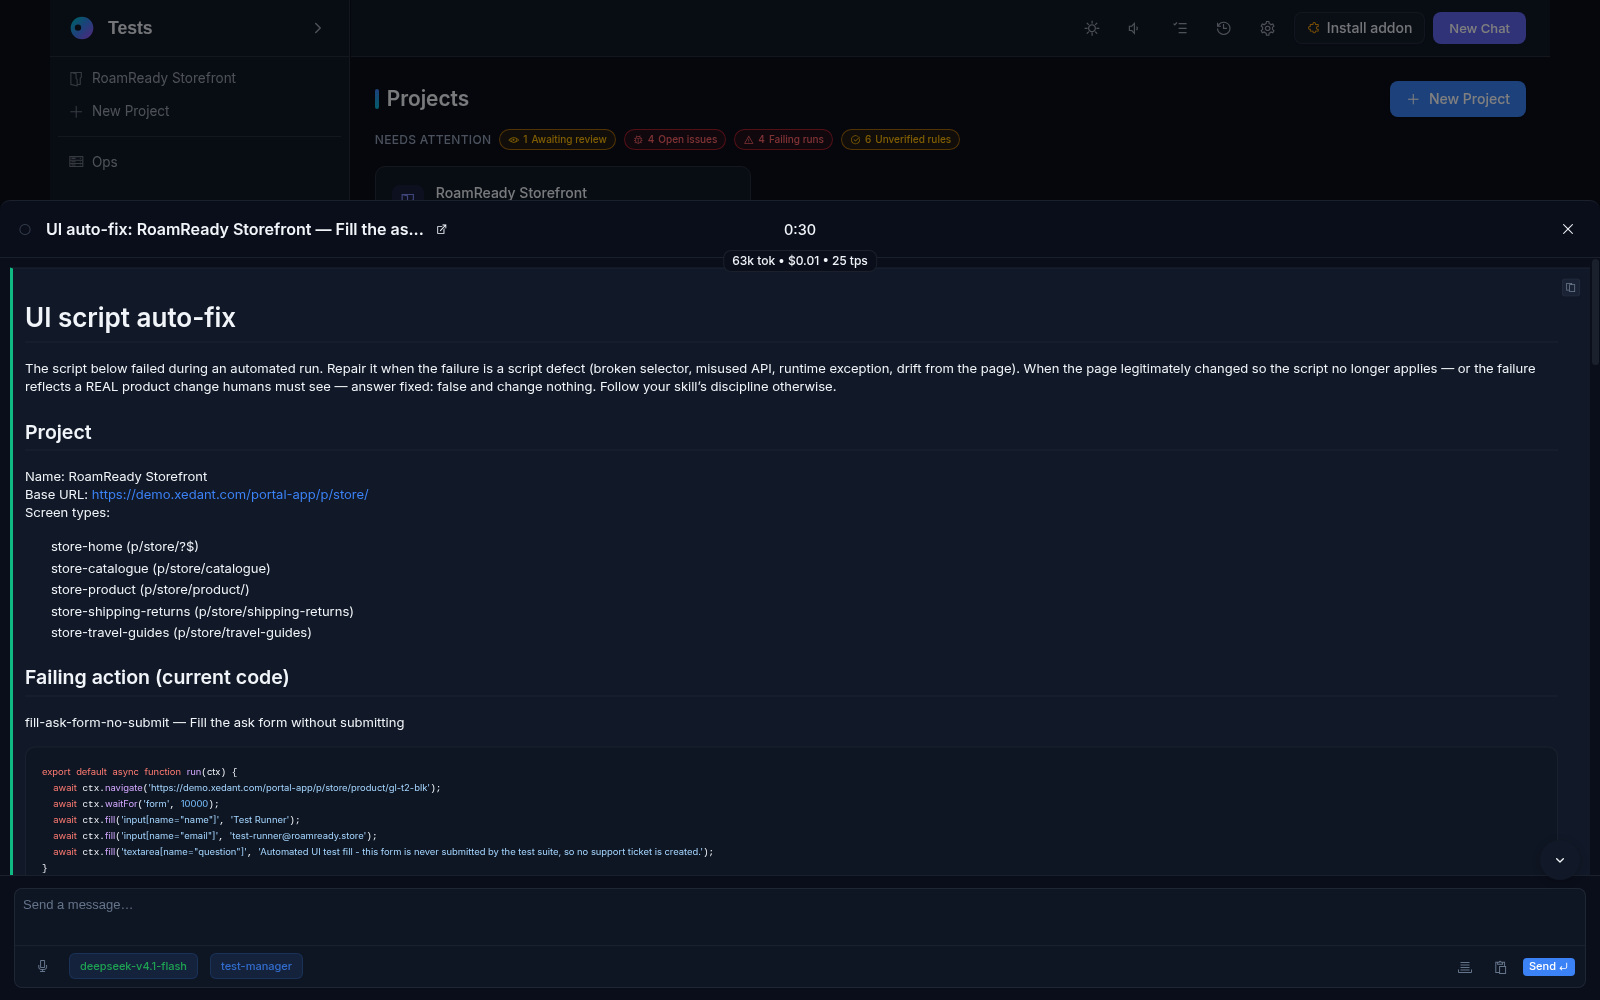
An action can be described in words — the agent writes the script, you dry-run it and approve
Steps run one line at a time, with no loops or conditions — that is what survives page transitions reliably
Tests: steps and order
A test is a sequence: open a page, run an action, check the rules
Steps are assembled in the interface and each is validated on save: you cannot reference a deleted action
A step has a “continue on error” switch — for places where one error should not stop everything
A test lives as a plain file in the project folder and lands in your edit history
A step may declare a visual capture — then queuing the test produces a build compared against baselines
Runs: queue, executor, evidence
A run goes into the queue on the server and is picked up by the first free runner: the built-in one (headless, in the container) or Chrome with the addon in runner mode — the addon setting that makes this browser execute the checks
The queue does not wait: both runners park at the queue door, so a queued run is claimed within milliseconds, not after a few seconds
There is no race: one runner takes the run. The built-in runner and Chrome keep different baseline families, so an engine is picked per project; the first build on the other engine arrives as new baselines
Every step leaves a screenshot and check results — you can see exactly where it broke
The verdict is plain: “passed”, “failed” or “error” — and each comes with something to back it
If the executor disappears, the run is marked with an error after half an hour and does not continue by itself
A run with visual checks is called a build: it carries a branch, a mode and a review state
Schedules: a check every morning
A weekly grid: pick the days of the week and the times when the test should run by itself
Times follow the project’s timezone — the one you set when creating it
Missed slots are not caught up: a powered-off computer means a missed run; the next one fires on time
A schedule needs an always-on computer with Chrome — the reliability of your checks equals the reliability of that machine
Issues: one problem — one line
Issues appear only from runs: manual checks do not create them — those are evidence, not problems
Identical errors are merged by fingerprint — the project, the rule and the depersonalized error text
The card shows the latest snapshot, the element, the originating run and how many times it repeated
A closed issue reopens by itself only when the same error repeats; an “ignored” one never does
Auto-fix: the agent repairs its own checks
If a check broke — not the site — the agent repairs it itself: it gets the code, the error text and a snapshot
The fix is applied at once and marked “auto-fixed · needs review”
Spending stays under control: one fix per target per hour and no more than five per project per day
The answer “this is not a broken check, the page really changed” is a legitimate outcome — then nothing is changed
Auto-repair is a checkbox in the test itself and is off by default: the agent fixes checks only where you allowed it; you can ask it to repair one manually at any time
The “what needs attention” summary
Global totals on top: open issues, failing runs over the week, unverified rules
Separately — auto-fixes waiting for review and comment analyses that failed or sit in the queue
Each project shows only non-empty badges; a click opens the project right on the tab you need
The numbers update by themselves, without a reload — and you can see when the next scheduled run is
The Chrome extension: a panel right on the page
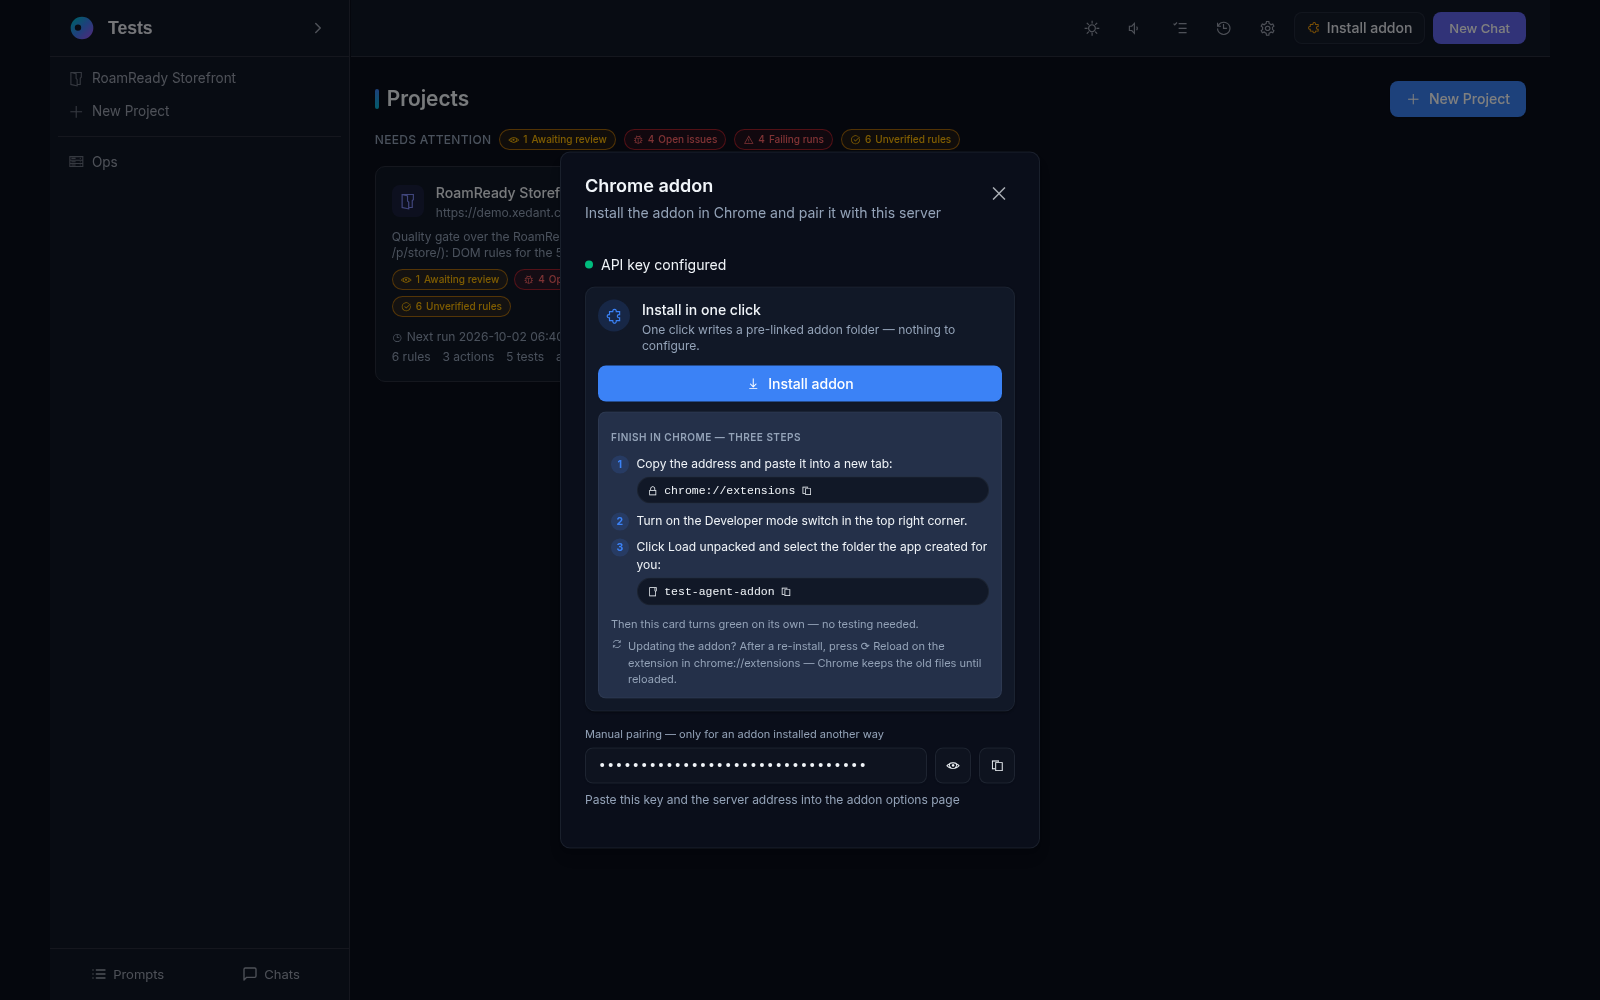
The addon installs in one click from Settings → UI testing: the server writes a folder with the pairing pre-configured
The panel is a draggable 380×560 window on the page: capture a screen, check the rules, record an action
The project is recognized by the page address — nothing to choose by hand
Honestly: the addon is private and is not in the Chrome Web Store; after a server update you rewrite the folder and press “Update” in the browser
The addon is no longer required to run tests: the built-in runner does the runs. Chrome with the addon is for hand captures, recordings and runs in a live window
A closed panel is unloaded from memory: while collapsed the page holds nothing, and the heartbeat runs only while the panel is shown
Issues go to the coding agent
By key: the issue list and card — including the snapshot link — and status changes
A coding agent reads the issues, fixes the site’s code and closes them by itself
Without a key the addresses answer “not configured”; with a wrong key — refused; sign-in by password does not work here
The key is like a password: hand it only to those who really need the access
Chat with the AI agent and the live page
The chat is powered by an external Xedant Agent: its address and key are set at installation
In the chat the agent analyzes comments, writes actions and repairs broken checks
The model can look at your open tab — through the live-page address or the common language of browser commands
It cannot close your tabs: only the ones it opened itself
Projects and files: everything under git, everything on your own server
A project is a folder on disk: settings, rules, actions, tests and comments as plain files
All of it is under git: the edit history is visible, any version can be restored, the folder moves to another server
Commits are made by a person — the server never does it on its own, so you decide what gets recorded and when
The daily flow (screens, runs, issues, schedules) lives in the database: there is too much of it for files
Visual checks: comparison against a baseline
A test step declares what to capture: the viewport, the full page, a component or a single element
Text snapshots are taken alongside: the page structure, styles, the accessibility tree and the order of URLs — they catch what a picture cannot show
Identical captures compare by content hash and cost nothing — the AI joins only the ambiguous cases
The build verdict is clear: visual pass, review required, fail or no data
Build verification and the difference viewer
A build is a run with visual checks: it carries a branch, a mode and a review state
Modes: full (every declared check), smart (only the affected ones), comparative (two environments side by side)
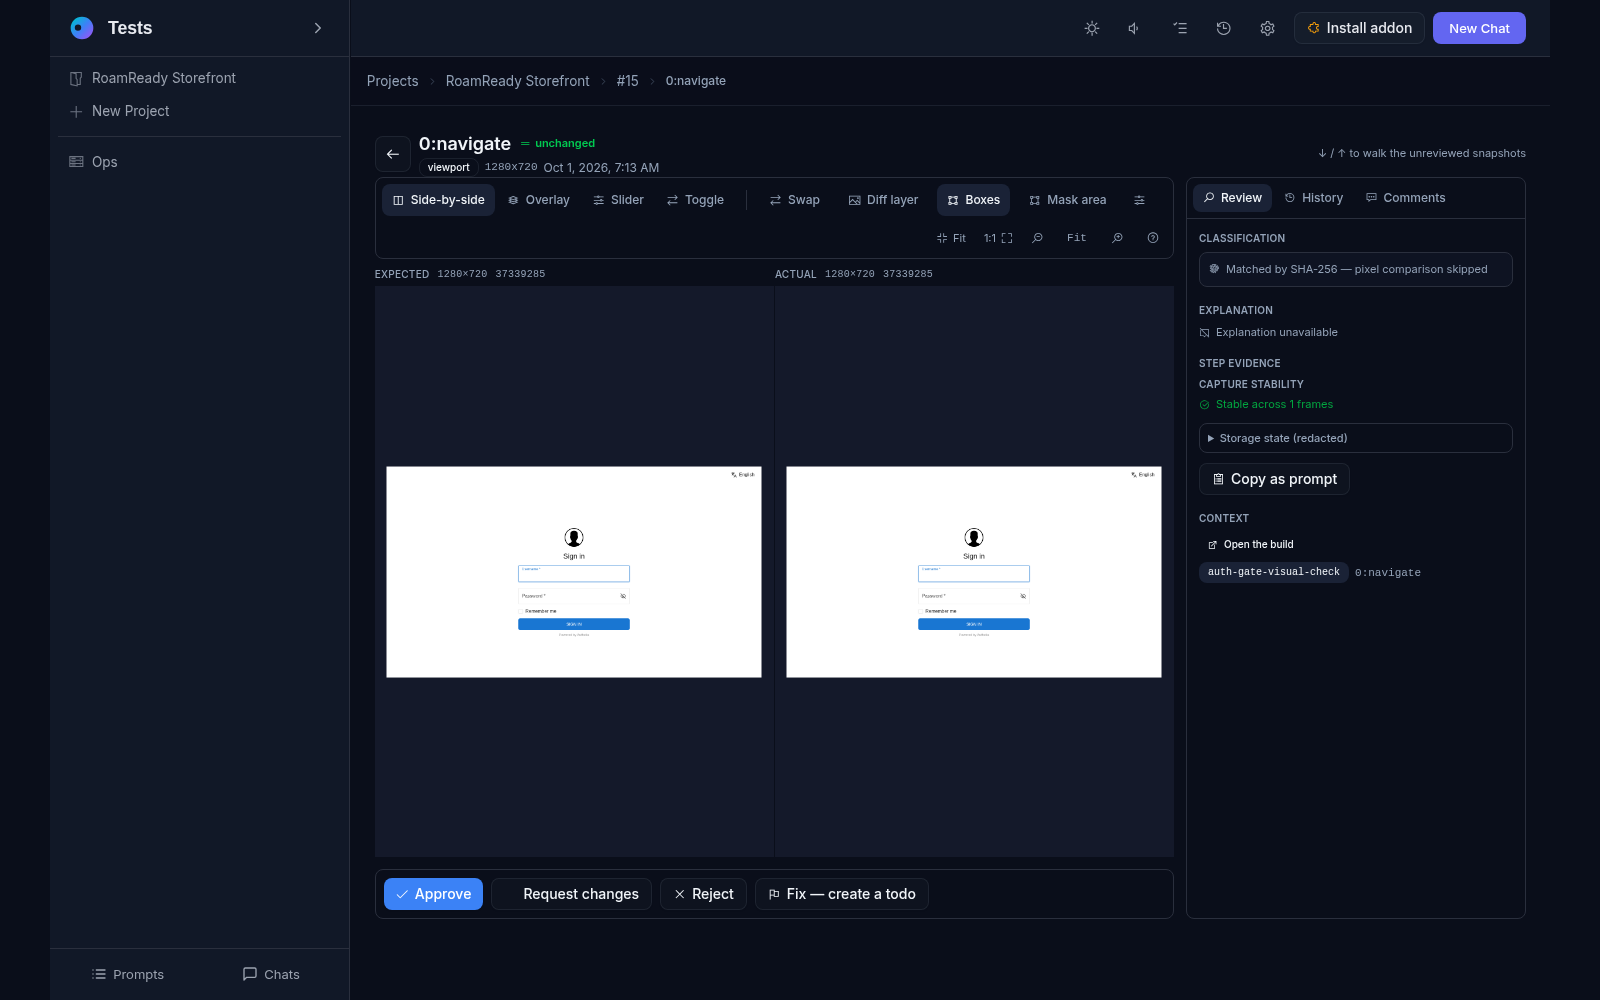
Differences compare four ways: side by side, overlay, a slider and a toggle
Every step keeps its snapshot and check results — you can see exactly where it broke
Review: the verdict is always a human’s
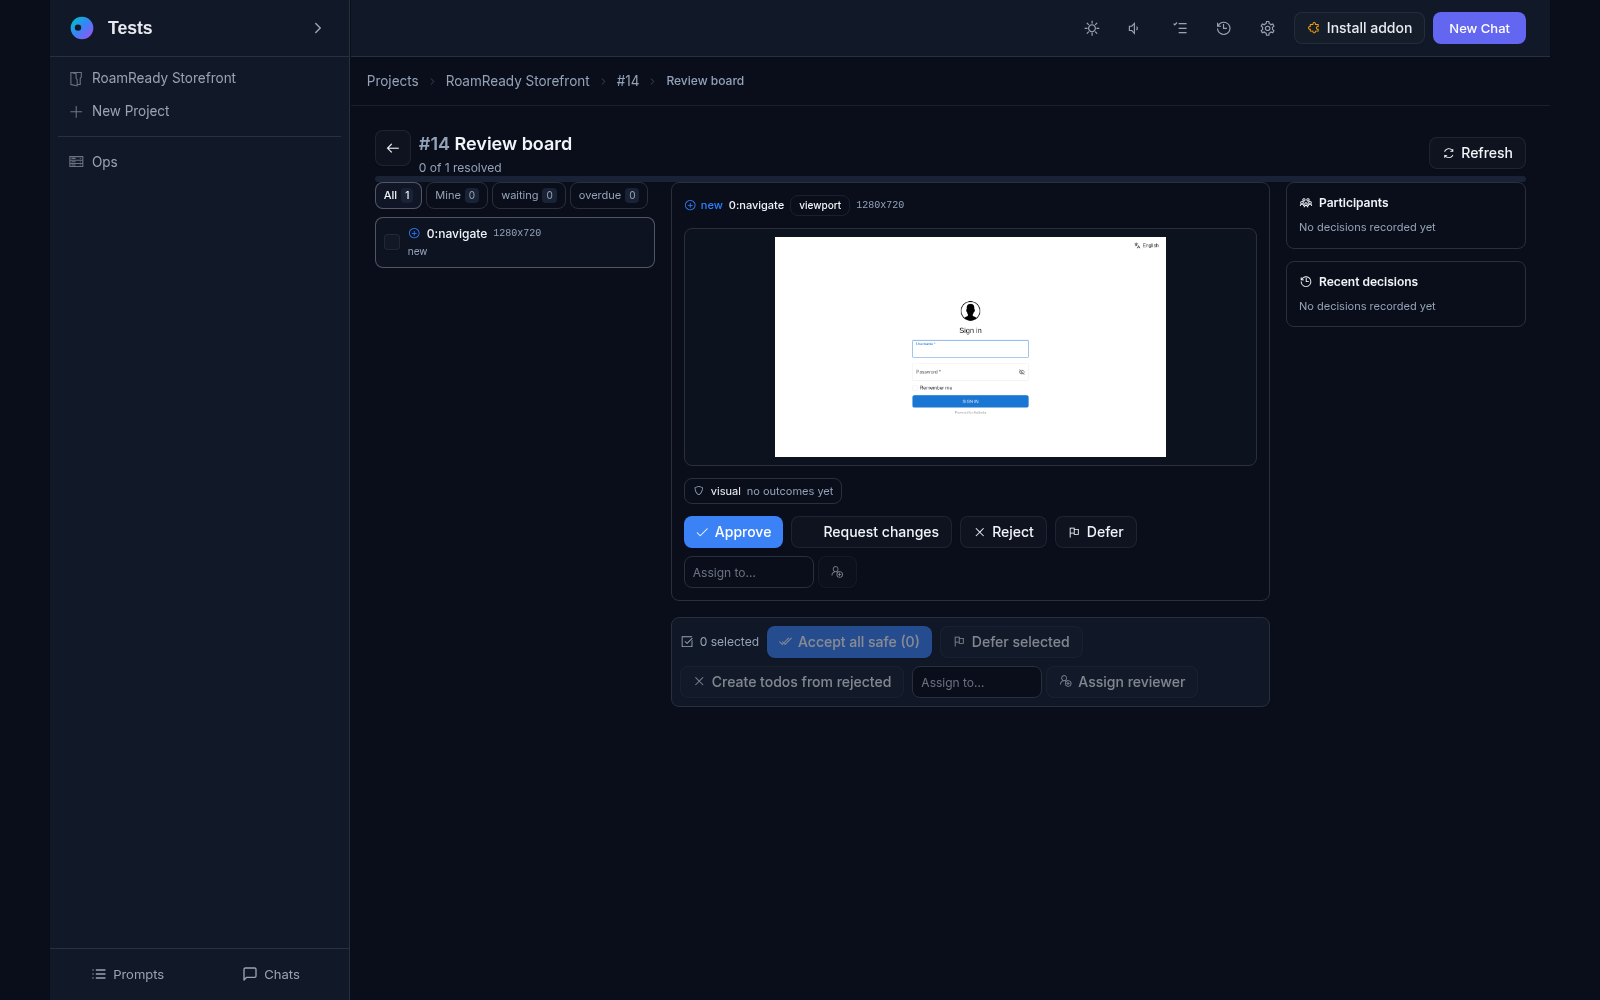
The review board gathers everything awaiting a decision, plus the fix todos it creates
Approve, request changes, reject or file a fix todo — a human decides; the AI only suggests
Bulk acceptance covers only the differences the deterministic rules proved safe
Roles and the design-approver flag: who looks, who decides and who approves shared components
The audit trail remembers who approved what, when and on what grounds
Build triage and test healing
Identical failures cluster by root cause — no need to dig through the same break ten times
Every cluster carries a plain-language explanation; with the AI down it honestly shows dry statistics
The AI suggestion and the reviewer’s verdict are stored apart and never substitute for each other
Test healing goes through a human: proposal, approval, a verification build and an exact rollback to the previous file
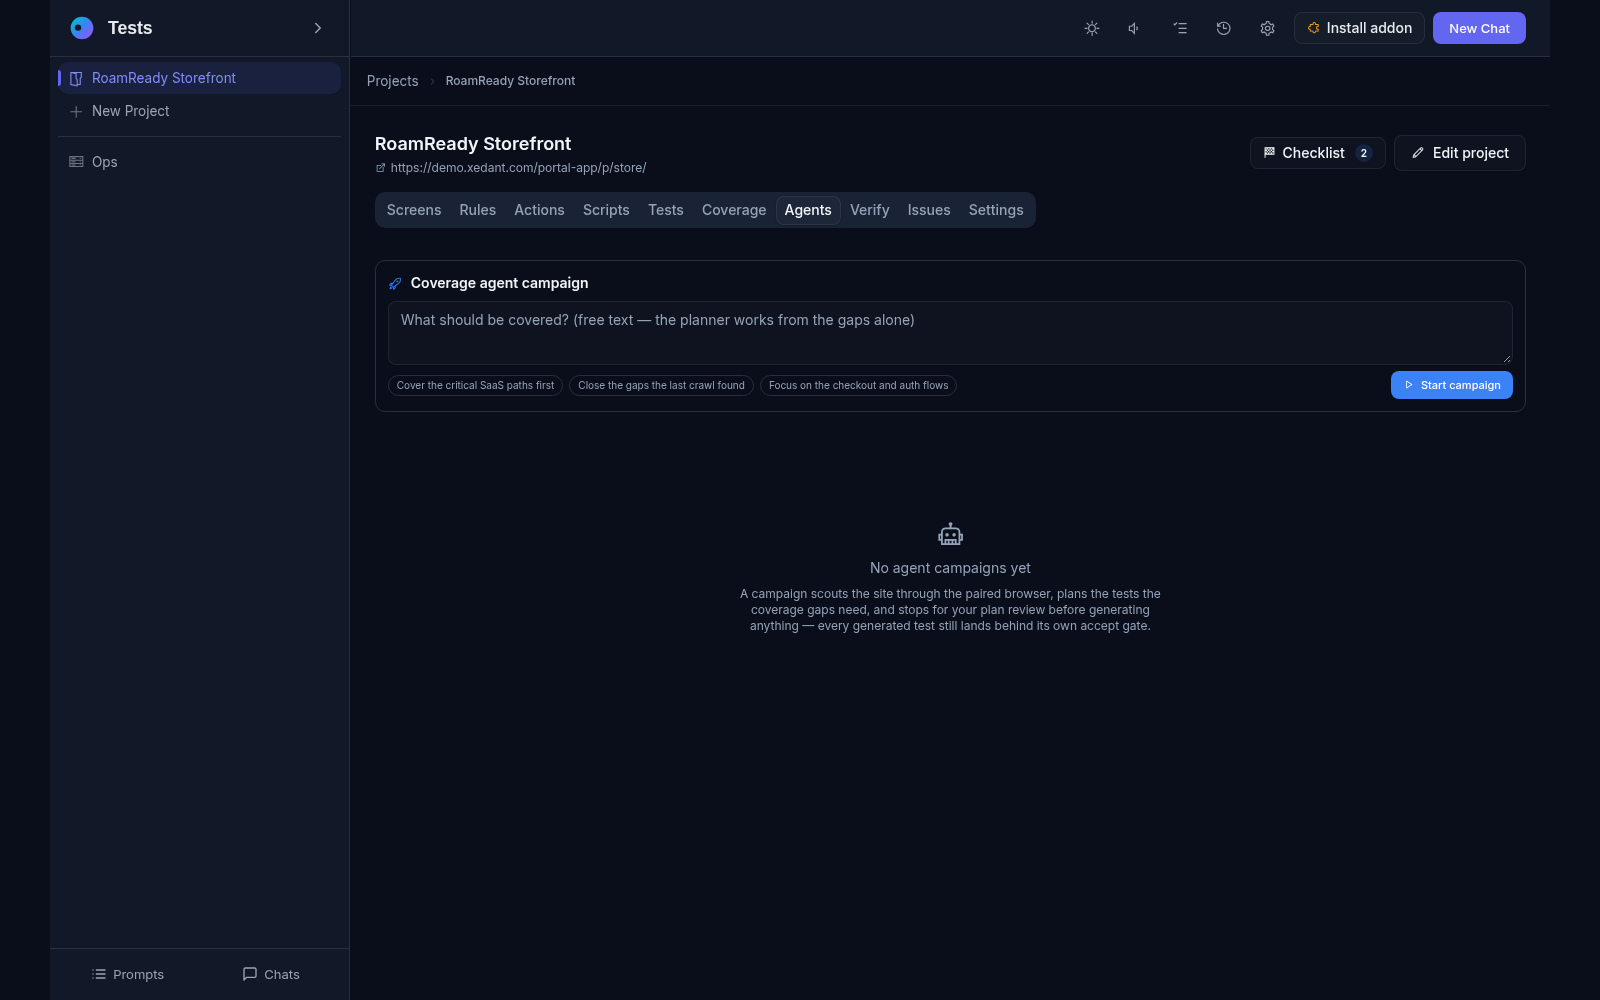
Coverage, the app map and agent campaigns
A surface-by-state inventory: every row shows whether tests cover it and who owns it
A deliberately-uncovered decision needs a reason and a review date — there are no empty cells
The crawler builds the app map right from the browser; routes can be colored by actual coverage
A coverage-agent campaign runs from scouting to the summary and pauses until a human approves the plan
CI, the report and share links
CI reads the build status from live rows: pending, failure or success
Honestly: a build that selected no checks is a failure, not an automatic pass
The viz tool answers the same facts from the command line; its exit codes are the CI contract
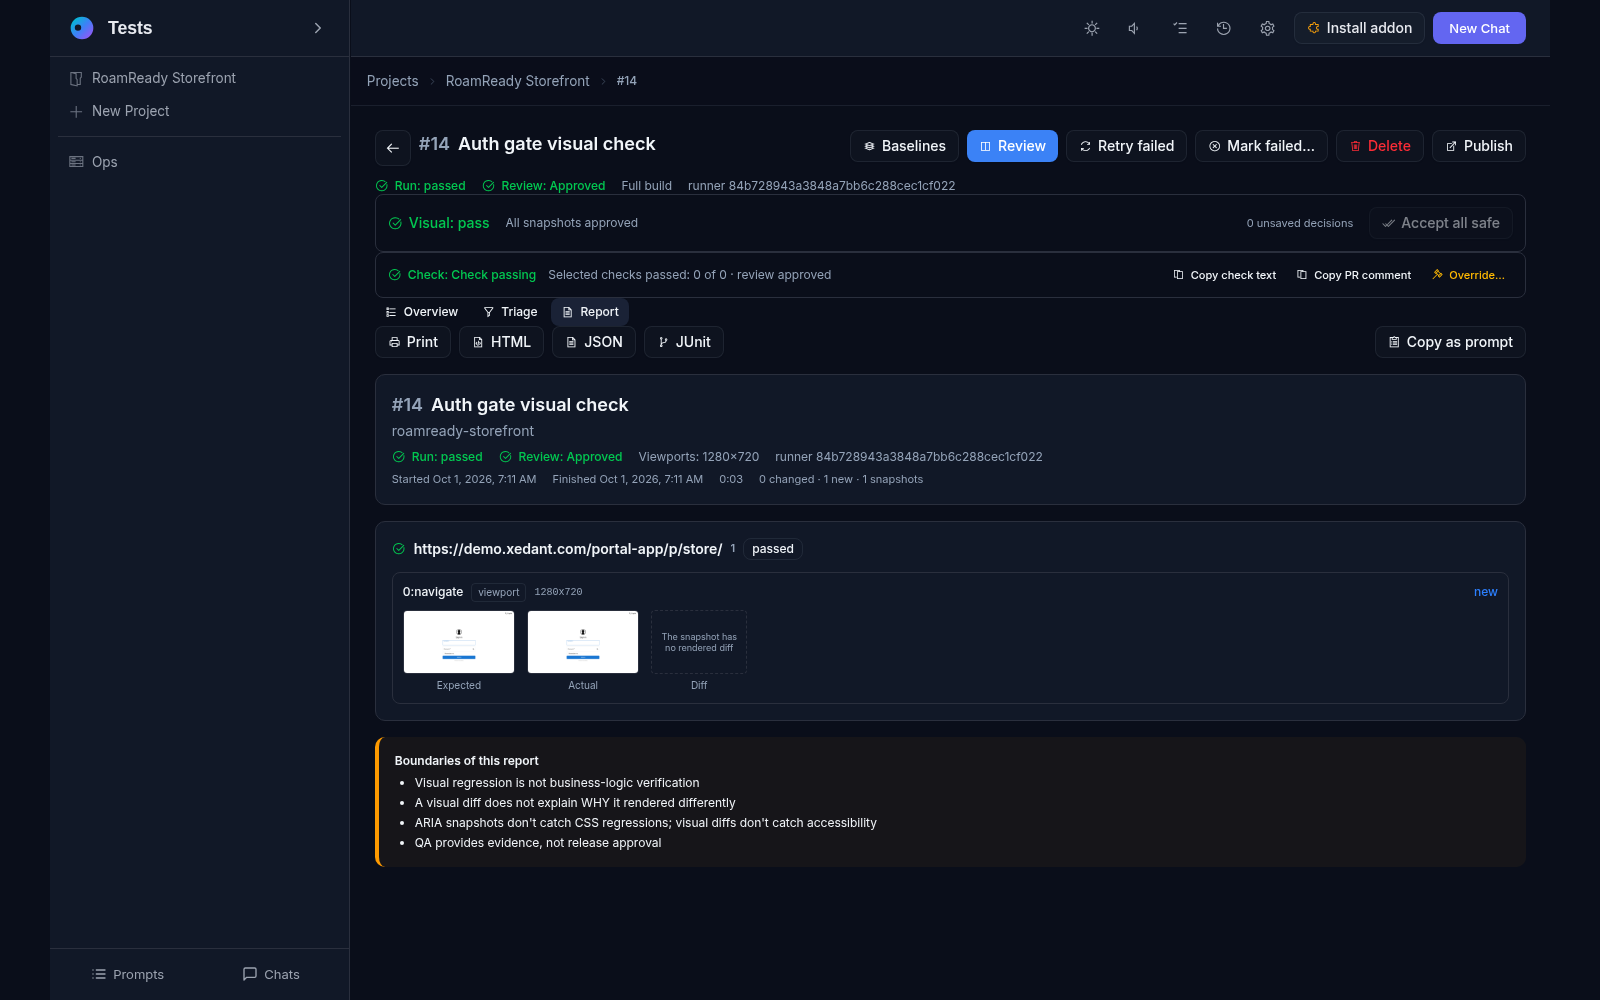
The printable report always carries the boundaries block — what a visual check catches and what it cannot
Share links open a build read-only, watermarked and expiring, with no sign-in
Operations and system health
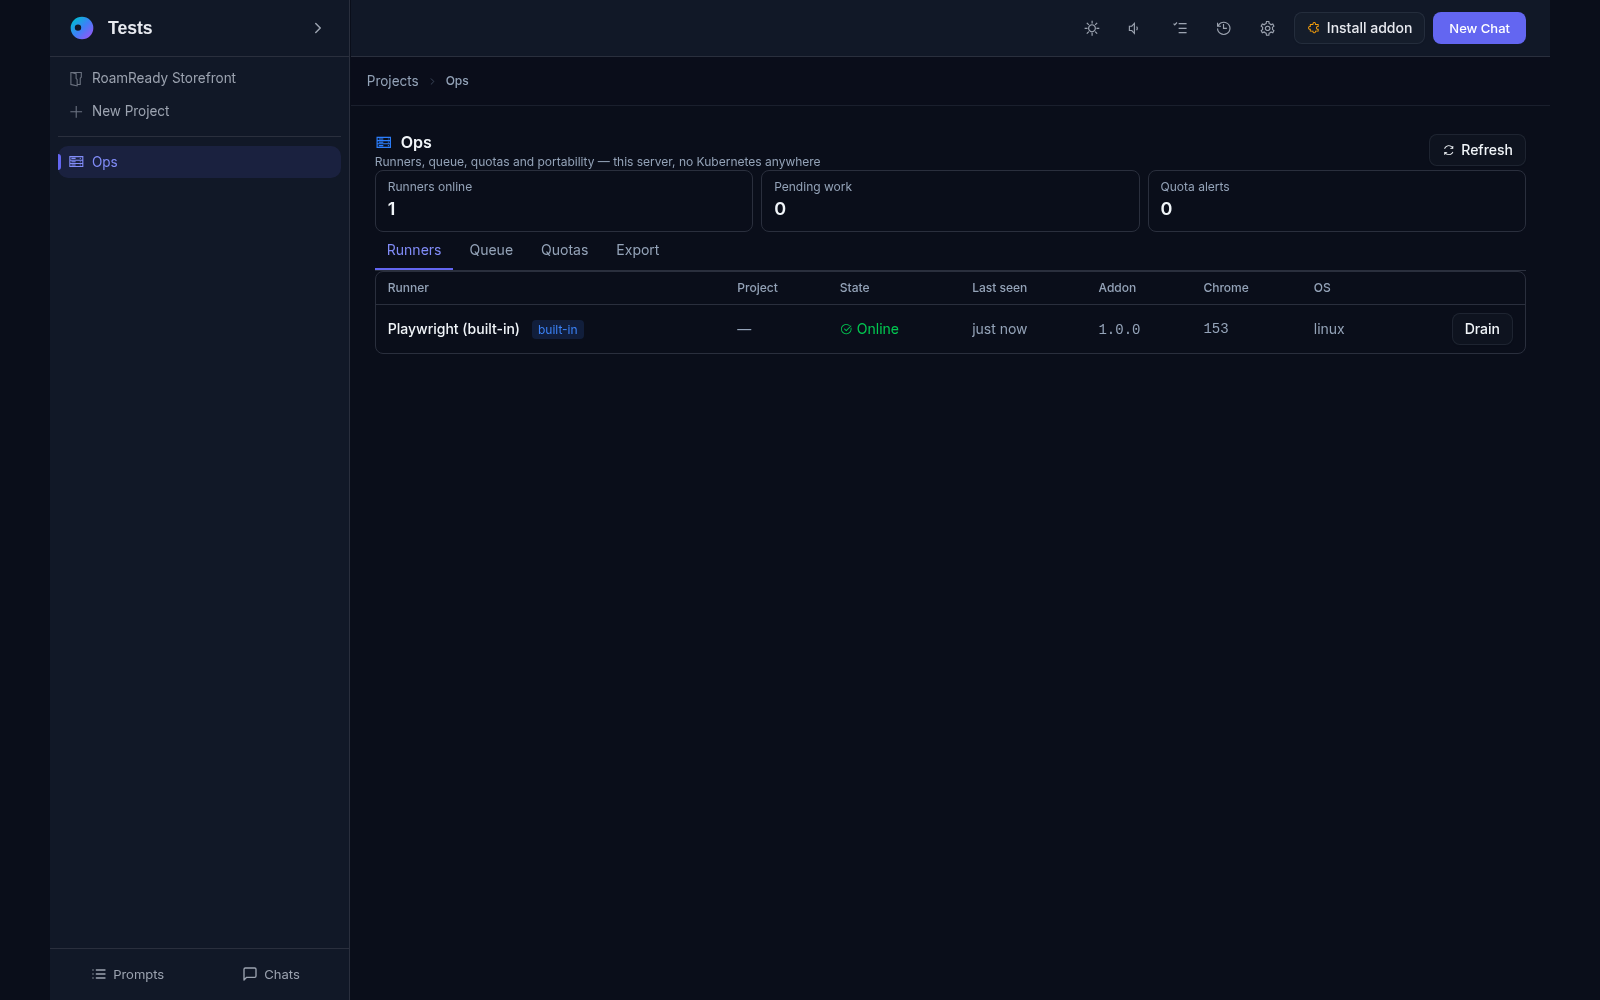
The runner registry shows online, degraded or offline and marks who it is — the built-in runner or Chrome with the addon; any runner can be drained and resumed
The queue shows what waits: builds, AI rounds, healing campaigns, crawls and webhook deliveries
The 50/80/100 budget ladder warns and blocks, but never bills
Health checks name what is wrong and how to fix it; on failure only bulk actions stop
Data export moves settings and baselines between servers and never carries credentials
Idle costs nothing: background jobs wake on events, and after 15 idle minutes memory is handed back to the server; the memory snapshot and a forced release are on the operations page
Visual testing settings
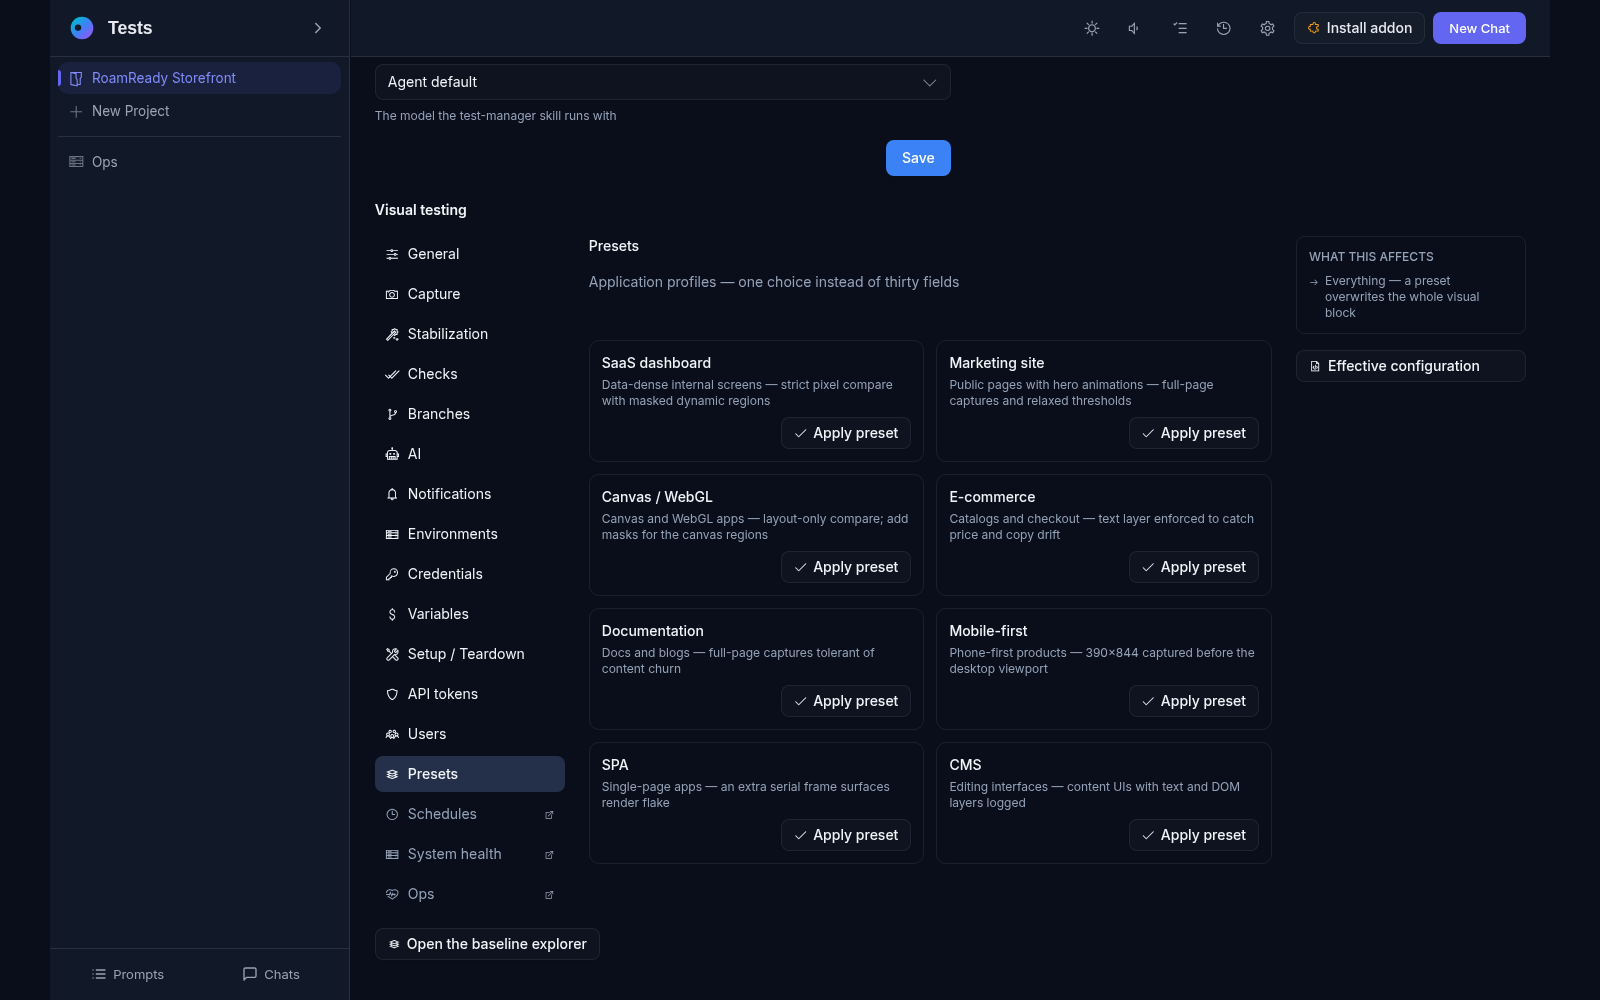
Eight application presets: one choice instead of thirty fields
Thresholds and check layers: visual, text, network, console, accessibility, design tokens, performance, URLs
Capture stabilization is on by default: frozen time, animations off, fonts and network idle awaited
Branches, auto-approval of safe differences and AI budgets are tuned per project
The setup checklist leads from connecting the agent to the first verdict and honestly shows what is done
Scripts: the product grows without a rebuild
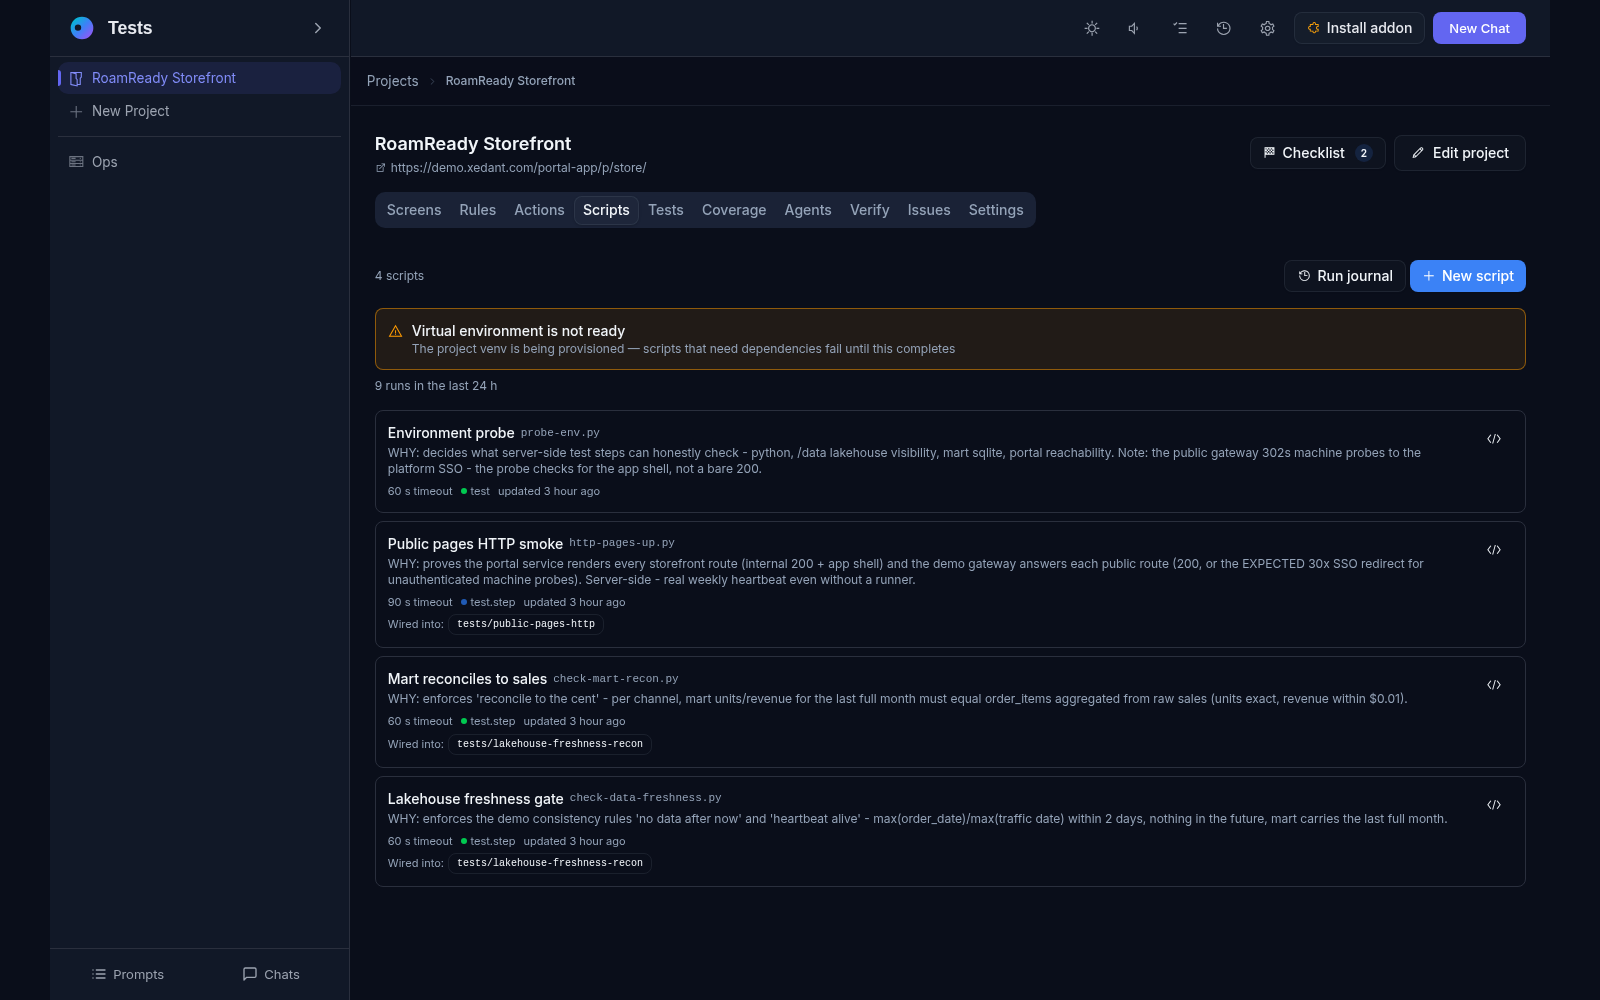
A script is an ordinary Python file in the project folder: next to the rules and actions, stored together with the project
An edit shows up right away: the next run picks up the new revision of the file, no product restart needed
Useful where a browser is not enough: check an API address, count rows in the database, look into a file, send a notification after a run
A script can be attached as a test step, a screenshot comparison engine, a difference classifier or a finished-run handler
Every attempt leaves one log entry: what was run, how it ended and how long it took; the project switch and the global switch stop everything at once
Built-in runner: checks work right away
Tests run without a separate computer
Scheduled checks used to need a computer with Chrome and our addon — the server did not open pages by itself. Now the built-in runner lives right in the container: it is a headless browser that runs tests right after installation. A separate machine with Chrome is no longer needed, and the schedule works even when nobody is sitting at the computer.
At idle the product keeps nothing running: the runner wakes up when a run appears in the queue and shuts down when the work is done. The Chrome addon does not go anywhere — it stays for hand captures, action recording, comments on a live page and runs you need to watch with your own eyes.
Runs and visual build captures need no separate computer and no addon
Nothing runs at idle: the runner starts for a queued run and exits when the work is done
Headless only: you cannot watch a run by eye — keep Chrome with the addon for that
Its captures form a separate baseline family — pick one engine per project and do not mix them
Shows up in the runner list on its own row, with pause and resume like a Chrome runner
Search across the whole app
One field instead of long navigation
When there are many projects and rules, finding things by hand takes a long time. Search lives in the sidebar and covers the whole app: rules and actions, tests, screens and comments, issues, scripts, project knowledge and docs files. Just start typing — hits appear as you type, grouped by kind, with title matches first.
A result row leads to where the find lives: a rule opens the right tab, an issue opens its own card, and a knowledge file is shown right in a window without navigating. Secrets and credentials never get into search — you cannot find them even by accident.
One field in the sidebar searches the whole app — projects, screens, rules, tests, issues, scripts and files
Keyboard: ⌘K (or Ctrl+K) opens the search, Enter jumps to the first hit, Esc clears it
Results are grouped by kind, title hits first
Knowledge and docs files open in a read-only preview right above the results
Russian and English match the same way; secrets and credentials are never indexed
To evaluate the product calmly, a free trial key is issued for 30 days. It is a separate license type (Trial) — it unlocks every feature, including the chat with the AI agent. Without a license the product is fully usable too: projects, screens, rules, actions, tests, runs, schedules, issues, auto-fix and the summary always work; the license is what opens agent messaging. The trial key is issued on request — write to us on Telegram with your name and email.
Every Test Agent feature with no limits for individuals: unlimited installations on any of your computers and servers. $197 one-time payment for a lifetime license. 12 months of free updates, then (optionally) a 50% discount on the next 12 months of updates from the original purchase price. Licensing works offline, and your key is truly lifetime. The matching Xedant Agent license is already included — the Agent is part of the product. The license is needed only for sending messages to the agent; screens, checks, actions, tests, runs, schedules, issues and the summary work without it.
Every Test Agent feature with no limits for everyone in a company or team, external contractors included. $497 one-time payment for a lifetime license with 12 months of free updates, then (optionally) a 50% discount on the next 12 months of updates from the original purchase price. Licensing works offline, and your key is truly lifetime. The matching Xedant Agent license is already included — the Agent is part of the product. The license is needed only for sending messages to the agent; everything else works without it.
Unlimited instances of Test Agent under your domain + the full source code with the right to change it any way you like, update the UI or branding for your company or domain, and integrate it closely with your infrastructure. Any visitor of your domain may use it as part of your services. $970 one-time payment for a lifetime license with 12 months of free updates, then (optionally) a 50% discount on the next 12 months of updates from the original purchase price. Licensing works offline, and your key is truly lifetime. The matching Xedant Agent service license is already included — the Agent is part of the product. The Agent’s source code is available only when you buy the service license for Xedant Agent itself. For smooth upgrades, we recommend changing only the branding and the integration — that keeps the effort of merging new features and fixes to a minimum.
In some cases we are happy to gift a free license:
- if you found a bug or a security vulnerability in any of our products (we honestly have no budget for a paid bug bounty, unfortunately);
- if you suggested a sound idea for improving our products (no coding needed — a useful idea is enough; you get a license if we add it to the roadmap);
- if you are an active contributor to open-source projects (we love open-source — we just have no time to maintain our own products as open-source);
- if you run a popular blog, Telegram channel or YouTube channel about programming, AI, interfaces, marketing, business or IT in general (no mention or promotion required — it is entirely up to you);
- if you are an active affiliate partner (sales are not required, but you should have at least some content dedicated to our products).
If any of the above is about you, just write to us on Telegram. Tell us your name and email, and we will generate your personal lifetime license key.